Human-centered GenAI feedback design in higher education: a multisite experiment on direct, reflective, and hybrid approaches to scientific argumentation
Huseyin Ates
International Journal of Educational Technology in Higher Education
500 字摘要
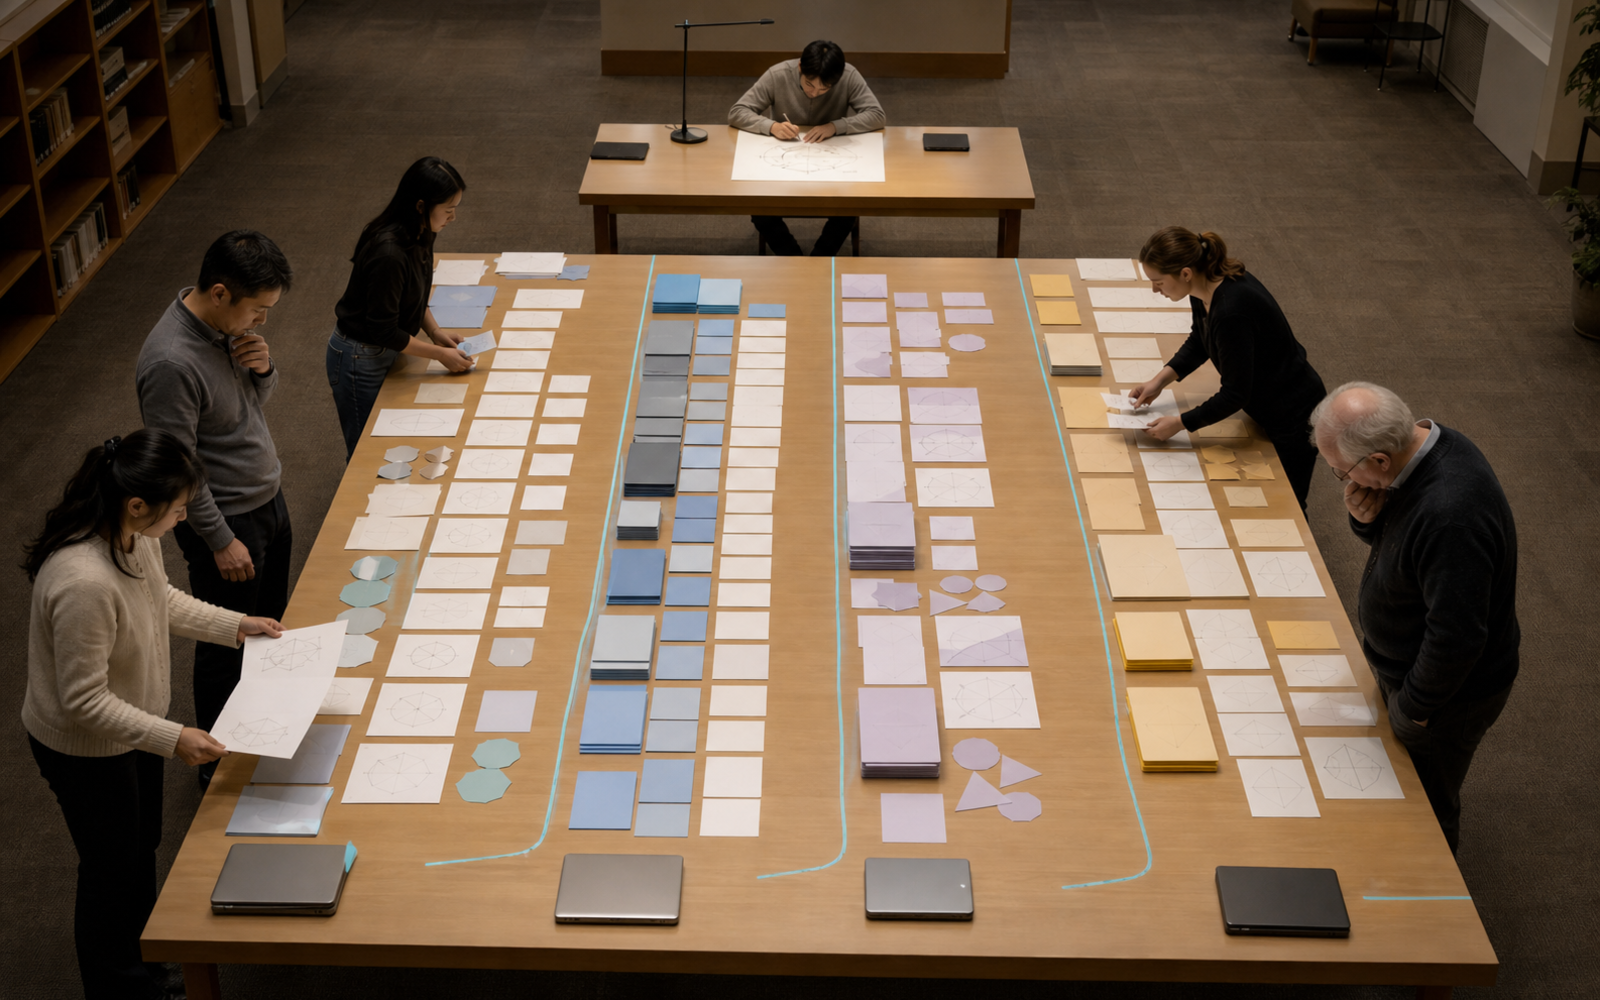
Ates tests a question that is more useful than whether generative AI can produce feedback: which feedback design helps students revise now and perform later without AI? The 2026 open-access study used a multisite, cluster-randomized, longitudinal field experiment in introductory biology, chemistry, and physics courses. It compared peer feedback, direct GenAI feedback, reflective GenAI feedback, and a hybrid sequence of self-evaluation, peer feedback, and GenAI critique.
The analytic sample included 1,176 first-year undergraduates in 48 course sections across four universities. Sections, rather than individual students, were assigned to conditions. The four groups were broadly comparable at baseline on demographics, prior knowledge, argumentation, achievement, feedback literacy, and previous GenAI experience. Attrition did not differ significantly by condition, and implementation audits indicated that 95.8 percent of applicable instructional steps were delivered as planned.
Students completed three cycles of drafting and revision around scientific arguments. Quality was scored on claims, relevance and sufficiency of evidence, coherence of reasoning, and treatment of limitations or alternative explanations. The study also measured conceptual learning, feedback uptake, self-regulated learning during revision, and a delayed transfer task completed individually under supervision without the GenAI tool or internet-enabled devices.
Direct GenAI feedback outperformed peer feedback on immediate argument-quality gain. Yet both reflective and hybrid feedback produced stronger immediate gains than direct AI feedback, and the hybrid condition had the highest adjusted mean. The hybrid-versus-reflective difference was not statistically significant. Revision-depth analyses followed the same pattern, suggesting that improvements were not limited to surface editing.
The differences became more educationally consequential beyond the revised product. Hybrid feedback significantly outperformed direct GenAI feedback on conceptual learning. The reflective contrast was positive but did not remain statistically significant after adjustment. On delayed AI-free transfer, both reflective and hybrid conditions significantly outperformed direct GenAI feedback, with no significant difference between them.
Process evidence helps explain the pattern. Reflective and hybrid designs produced higher feedback uptake and self-regulated learning than direct GenAI feedback. Multilevel mediation models found significant indirect pathways through uptake, self-regulation, and their sequence for argument gain and delayed transfer. The results support the interpretation that students learned more when the design required them to judge and work with feedback rather than simply receive a polished critique.
The study is unusually strong for educational GenAI research because it spans institutions, randomizes clusters, checks implementation, uses manually scored disciplinary work, and includes a delayed AI-free outcome. It also preserves important boundaries: submitted work had to remain the student's own, students received guidance on ethical use and data-entry limits, and monitoring was restricted to the study platform.
Limits remain. Cluster assignment leaves only 48 randomized units, the author conducted all major study functions, and the intervention focused on first-year science argumentation. The paper cannot establish that the same sequence will transfer to other disciplines, age groups, commercial tools, or longer periods. Self-regulated learning was partly measured through self-report, even though revision traces provided complementary evidence.
For Hong Kong higher education, the strongest design implication is sequencing. Ask students to assess their draft against criteria before seeing AI critique, incorporate peer evidence, require a rationale for accepted and rejected suggestions, and test later on a new task without AI. The study suggests that feedback becomes learning when students retain evaluative judgment and ownership, not when the system merely produces more comments.