← 返回研究新闻

#assessment

assessment

10 篇论文

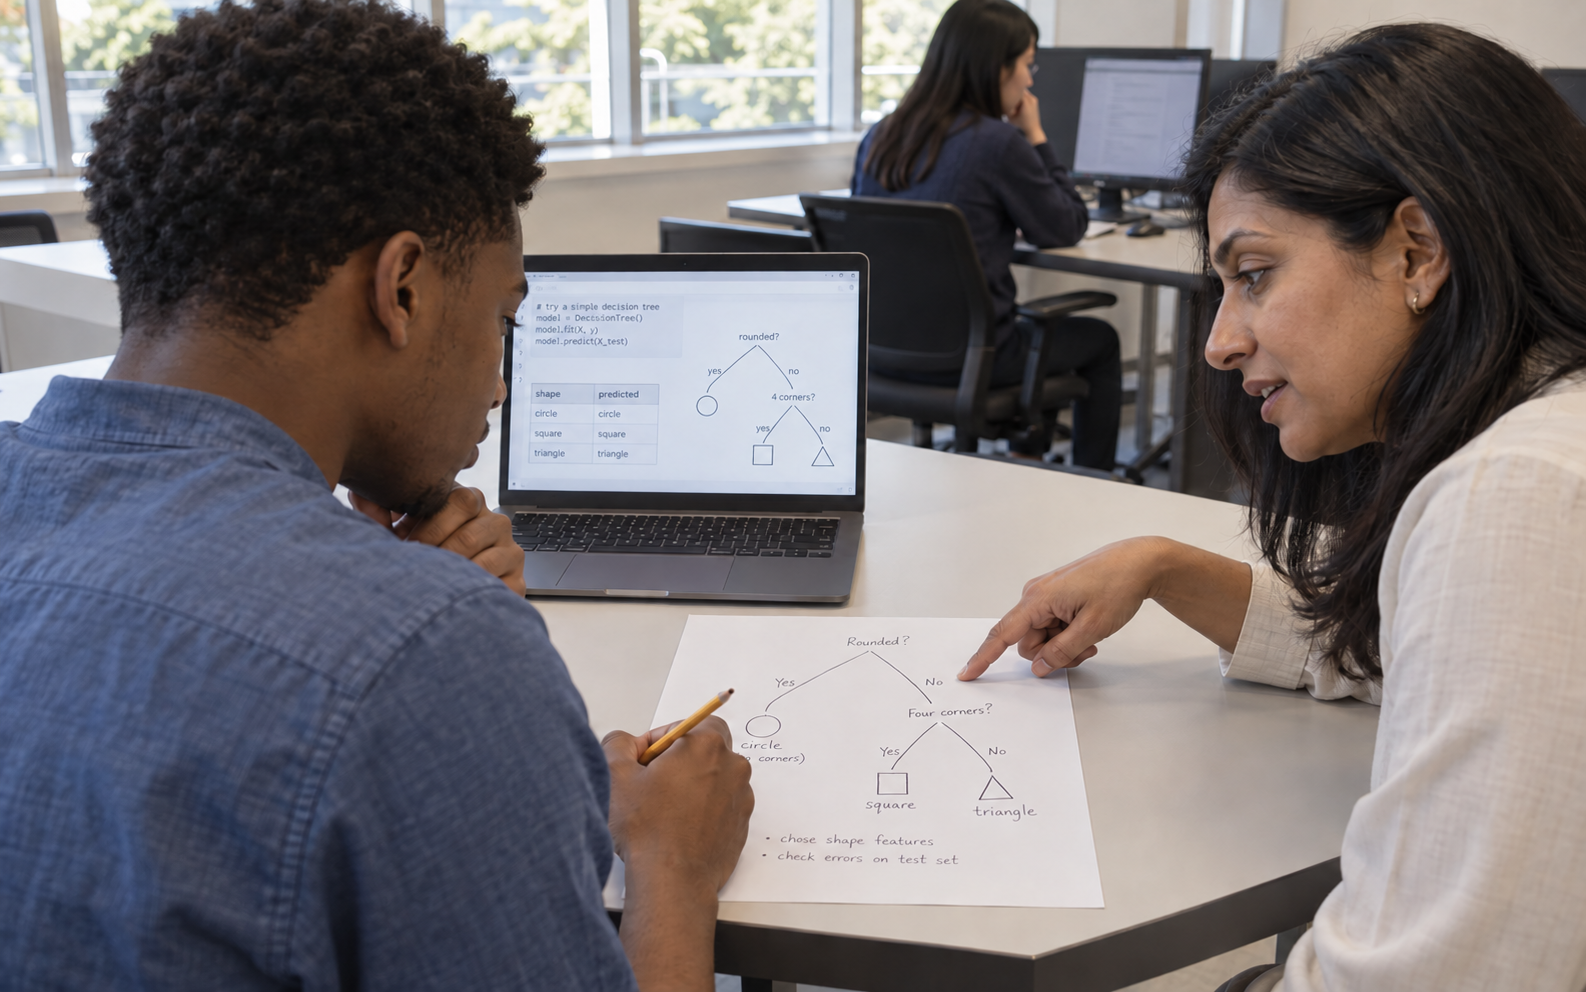
A university student explains a simple shape-classification decision tree to a lecturer during a supportive coding assessment conversation.
政策 / 伦理2026年10月13日
政策 / 伦理 213

Teacher case: A Malaysian lecturer uses oral defence to assess students' judgment in Gemini-assisted coding

Google

AI Product and Learning Report

An October 5 teacher account from Universiti Putra Malaysia describes students using Gemini in Colab while defending their modelling choices in verbal interviews. This October 13 report considers the assessment design, not a proven improvement in attainment. OpenAI's software-testing cases and Anthropic's project coordination provide context: when AI can produce working code, educators need evidence of what students understand, can troubleshoot, and can justify in a changed situation.

product newsGemini in Colabassessment
阅读 500 字摘要 →
A university student revises an essay using an evidence-to-claim sketch while a lecturer and peer discuss the feedback.
期刊论文2025
期刊论文 190

Teacher, peer, or AI? Comparing effects of feedback sources in higher education

Joshua Weidlich, Flurin Gotsch, Kai Schudel, Claudia Marusic-Würscher, Jennifer Mazzarella, Hannah Bolten, Dario Bütler, Simon Luger, Bettina Wohlfender, Katharina Maag Merki

Computers and Education Open

Students can welcome feedback without producing stronger revisions. A randomized university study compared teacher, peer, and language-model feedback while concealing its source from recipients. AI and peer comments were perceived as fairer than teacher comments, but teacher feedback supported better scientific argumentation than AI feedback. The findings separate the experience of receiving comments from the quality of the work that follows, with implications for evaluating automated feedback tools.

Higher EducationAI FeedbackPeer Learning
阅读 500 字摘要 →
A professor and teaching assistant compare a short-answer rubric, annotated responses and a laptop feedback draft while recording a justification.
期刊论文2025
期刊论文 174

AI-assisted short-answer grading broadly resembled instructor grading, without testing learning gains

Tobias Heinrich, Spencer Baily, Kuan-Wu Chen, Jack DeOliveira, Sanghoon Park, Navida Chun-Han Wang

PLOS ONE

Randomized grading comparisons across political-science courses analyzed 3,080 short-answer responses from 271 students. Instructor-guided GPT-4 prompts broadly resembled human grading on selected evaluation measures, with small and context-dependent differences. Human feedback was slightly more likely to be rated helpful overall. The study evaluates grading and feedback workflows, not student learning or critical-thinking gains, and low regrade-request rates cannot establish that all errors or biases were absent.

assessmentshort-answer questionsAI-assisted grading
阅读 500 字摘要 →
Participants in a university AI workshop compare a lesson activity, software workflow and reading notes while a student records questions.
政策 / 伦理2026年9月21日
政策 / 伦理 169

Industry news: OpenAI Academy adds learning paths for educators, students, developers, and leaders

OpenAI

AI Product and Learning Report

OpenAI expanded its Academy on September 21 with courses for educators, college students, developers, and leaders, alongside its existing workplace pathway. Course badges depend on passing an assessment. Anthropic's learning approach and Google's Gemini-related training provide useful comparisons, but the new portfolio is not evidence that all roles need the same skills. Institutions can choose tasks and assessments that reflect what each group actually needs to decide and do.

product newsOpenAI AcademyAI for Educators
阅读 500 字摘要 →
大学生向教师解释几何作图,同学在旁思考,桌上的电脑展示相关数字图解
政策 / 伦理2026年9月7日
政策 / 伦理 112

评论:Astra 的 AGI 主张,让教育更需要看见人的真实学习

AIED.HK Editorial

AI Product News Commentary

OpenAI 于 2026 年 9 月 3 日发布 GPT-6 Astra,并引发关于 AGI 是否已经到来的讨论。本文将这一说法视为需要归属的主张,而非已确立的共识。教育眼前的挑战,是分清 AI 能产出什么,以及学习者能独立解释、质疑和迁移什么,再以更强的代理能力支持真正的学习。

产品新闻评论GPT-6 Astra
阅读 500 字摘要 →
A programming student traces an algorithm and test cases on paper while a tutor points to a test report beside code on a laptop.
期刊论文2025
期刊论文 134

Students valued AI coding help while exam evidence exposed difficulties in correcting generated code

Dan Kohen-Vacs, Maya Usher, Marc Jansen

International Journal of Artificial Intelligence in Education

Two studies examined student attitudes to generative AI and performance on code-correction tasks. A survey found favorable perceptions, while exam analyses found lower performance on AI-generated debugging tasks in several cohorts. The studies involved different students and compared debugging with code construction, so they do not establish that positive attitudes caused weak verification or that AI origin alone made the tasks harder. They identify a specific skill worth teaching and assessing.

programming educationdebuggingassessment
阅读 500 字摘要 →
An educator demonstrates a paper-reading tool on a large screen while university students watch, take notes, and hold an annotated expectations card.
期刊论文2025
期刊论文 128

Students rated AI tools differently after demonstrations, but expected support was not tested learning

Joana Heil, Dirk Ifenthaler, Martin Cooper, Maria Lidia Mascia, Rachele Conti, Maria Pietronilla Penna

Smart Learning Environments

A survey of 223 students at universities in Australia, Germany, and Italy compared expectations about six AI tools after short demonstrations. Perceived support varied by tool, and students reporting greater AI competence tended to give more positive ratings. Participants did not use the tools during the study. The results therefore inform questions about expectations and training needs, not claims about actual learning improvements or a current product ranking.

AI competencestudent expectationshigher education
阅读 500 字摘要 →
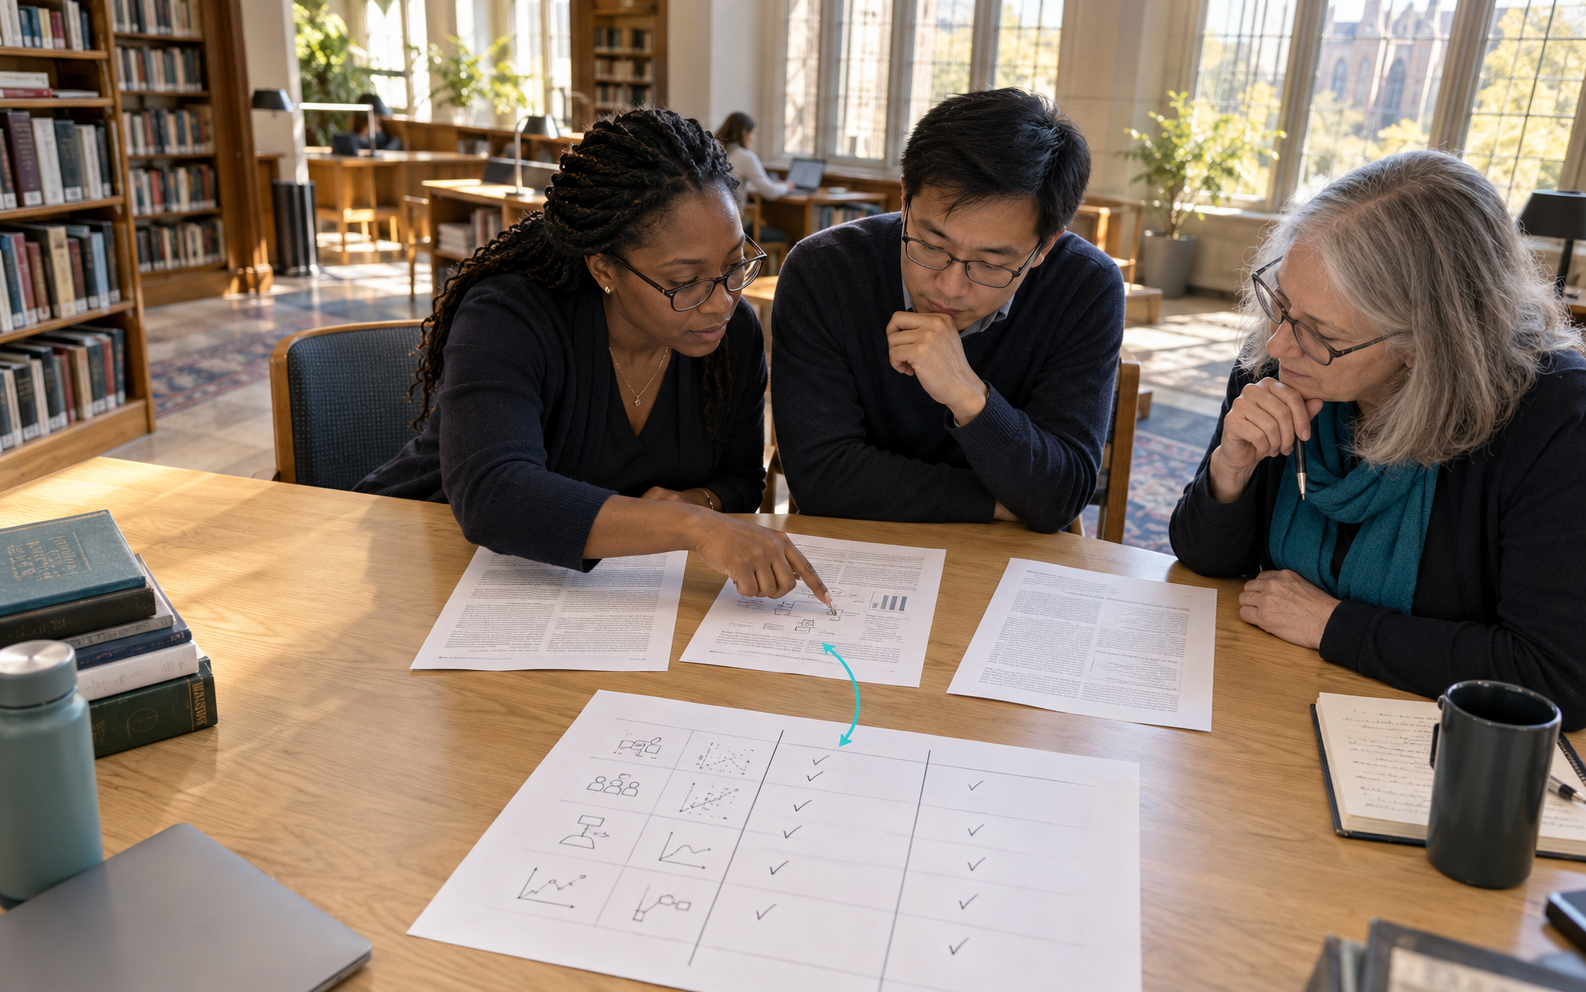
Three researchers compare printed studies and a hand-drawn evidence matrix at a sunlit library table, with a subtle cyan arrow linking the papers.
综述2025
综述 118

A review of early ChatGPT research separates model performance from evidence about student learning

Qian Liu, Anjin Hu, Tehmina Gladman, Steve Gallagher

Innovative Higher Education

A scoping review published in 2025 maps 39 studies from ChatGPT’s first eight months in higher education. It finds varied model performance, promising classroom uses, and repeated concerns about accuracy and assessment. Much of the evidence evaluated what the model could produce or what users believed. The review calls for stronger explanations of learning and should be read as an early baseline, not an evaluation of current models.

research reviewhigher educationassessment
阅读 500 字摘要 →