Using Language Models as Evaluators
Language models can help review AI outputs, but their judgments need calibration. Position, verbosity, shared errors and untrusted inputs can distort scores and preferences.
출처
전체 수업 요약
Using a language model as an evaluator means asking it to judge another output according to criteria. It might compare two explanations, check a lesson draft against a rubric, or identify unsupported claims in a response. This can make large-scale review more manageable, but the evaluator is itself a fallible model. A numerical score and a fluent justification are outputs to validate, not independent evidence that the judgment is correct.
Evaluation can take several forms. A pointwise judge scores one response, while a pairwise judge chooses between alternatives. A reference-based evaluation compares with an expected answer; an open-ended rubric may require judgment without a single reference. These designs answer different questions. A preference for one explanation does not establish mathematical correctness, and agreement on a small benchmark does not establish suitability for a school's curriculum or learners.
Research on MT-Bench and Chatbot Arena examined strong language models as judges and identified biases such as sensitivity to position and verbosity. Other work on evaluator fairness demonstrates how changing the order of responses can change judgments. The practical implication is to test evaluation behavior, not merely write a more elaborate rubric. A model may reward confident presentation, favor familiar stylistic patterns, or overlook a subtle error shared with the generator.
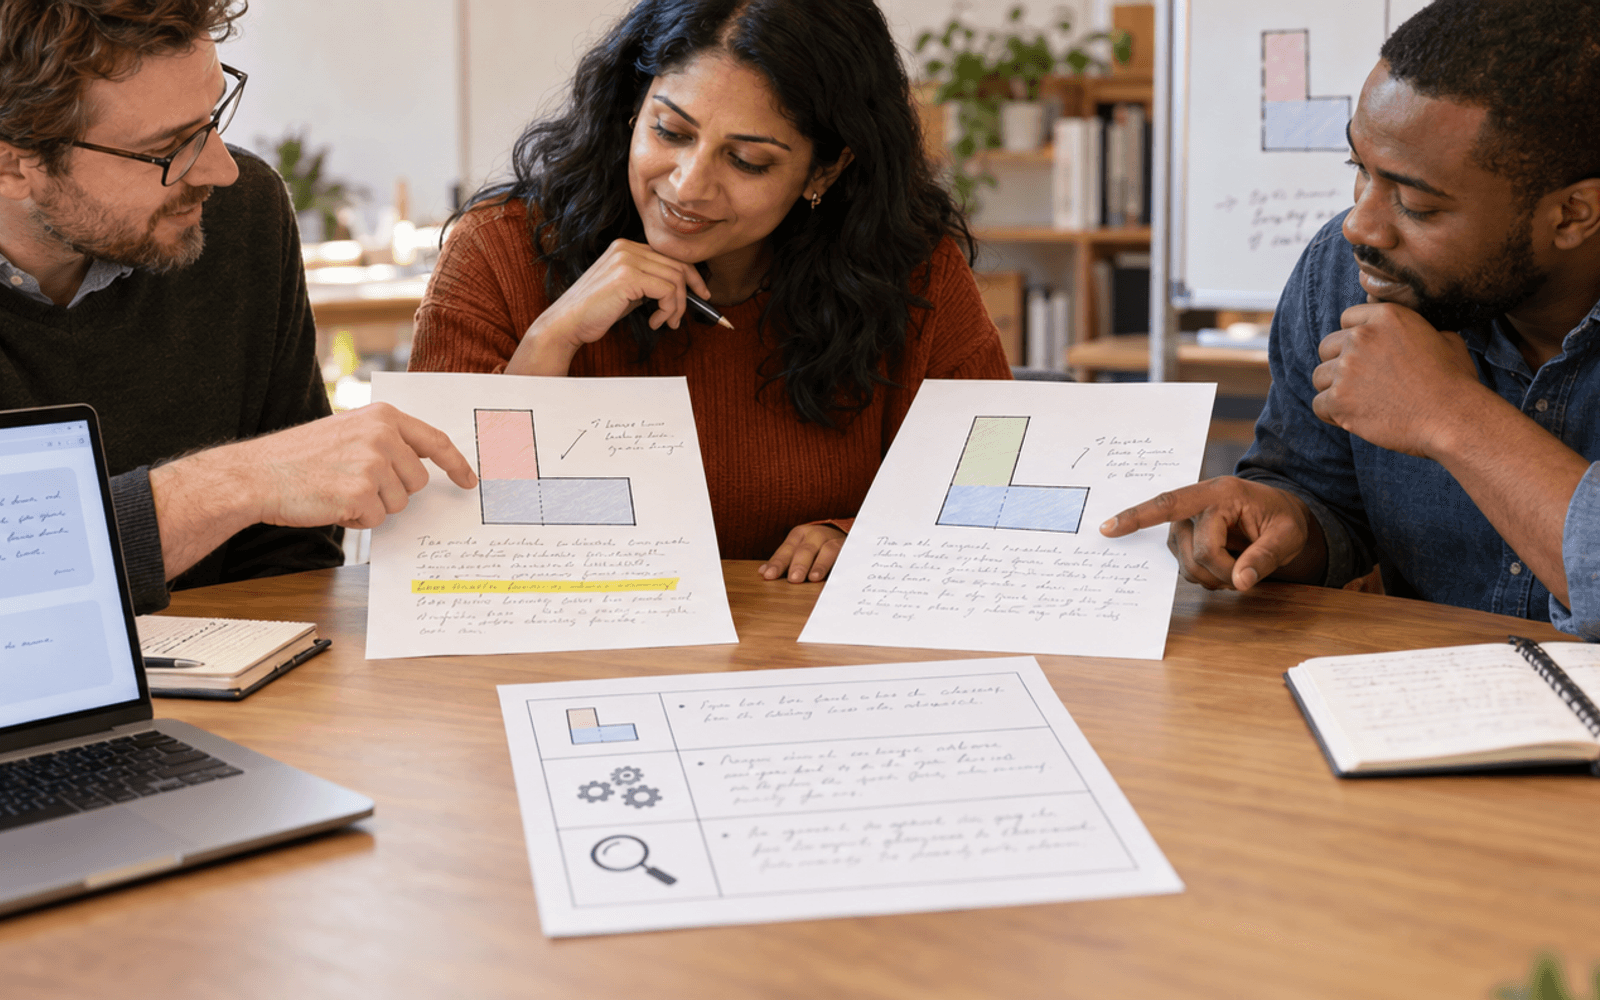
Imagine two explanations of why a fraction with a fixed positive numerator becomes smaller as its positive denominator increases. One is concise and correct; the other is longer but includes an invalid generalization. Teachers independently judge both using explicit criteria. The automated judge receives the pair in both orders. If it favors the longer response or reverses its preference when positions change, the result reveals a weakness in the evaluation process rather than a discovery about teaching quality.
Calibration uses examples with carefully reviewed judgments, including borderline and failure cases. Compare the model with independent reviewers and inspect disagreements by criterion. Keep generator and evaluator versions, prompts, input context and scoring rules recorded. Where repeated outputs vary, report that variability. Using a different model can reduce some shared errors, but two models can still inherit similar blind spots or favor the same superficial cues.
Evaluated content should be treated as untrusted input. A candidate response might contain instructions that attempt to influence the judge. The surrounding application must preserve the evaluation task and validate output structure, while human checks examine whether the reasoning supports the score. Sensitive student work also requires appropriate handling. Automated review should not create an unnoticed route for sharing identifiable writing with an external service.
A useful role is triage: identify likely problems, prioritize human attention, and summarize evidence for review. Consequential judgments need a process that allows correction and records who is responsible. Even a high agreement rate leaves open whether rare failures affect important decisions. Language-model evaluation is strongest when bounded to a clear task, checked against representative human evidence, and combined with deterministic checks wherever correctness can be established directly.