Out-of-Distribution Detection
Out-of-distribution detection flags inputs that may fall outside a model's supported setting. Confidence scores are imperfect signals, and useful detection requires realistic tests and an appropriate response to uncertainty.
출처
전체 수업 요약
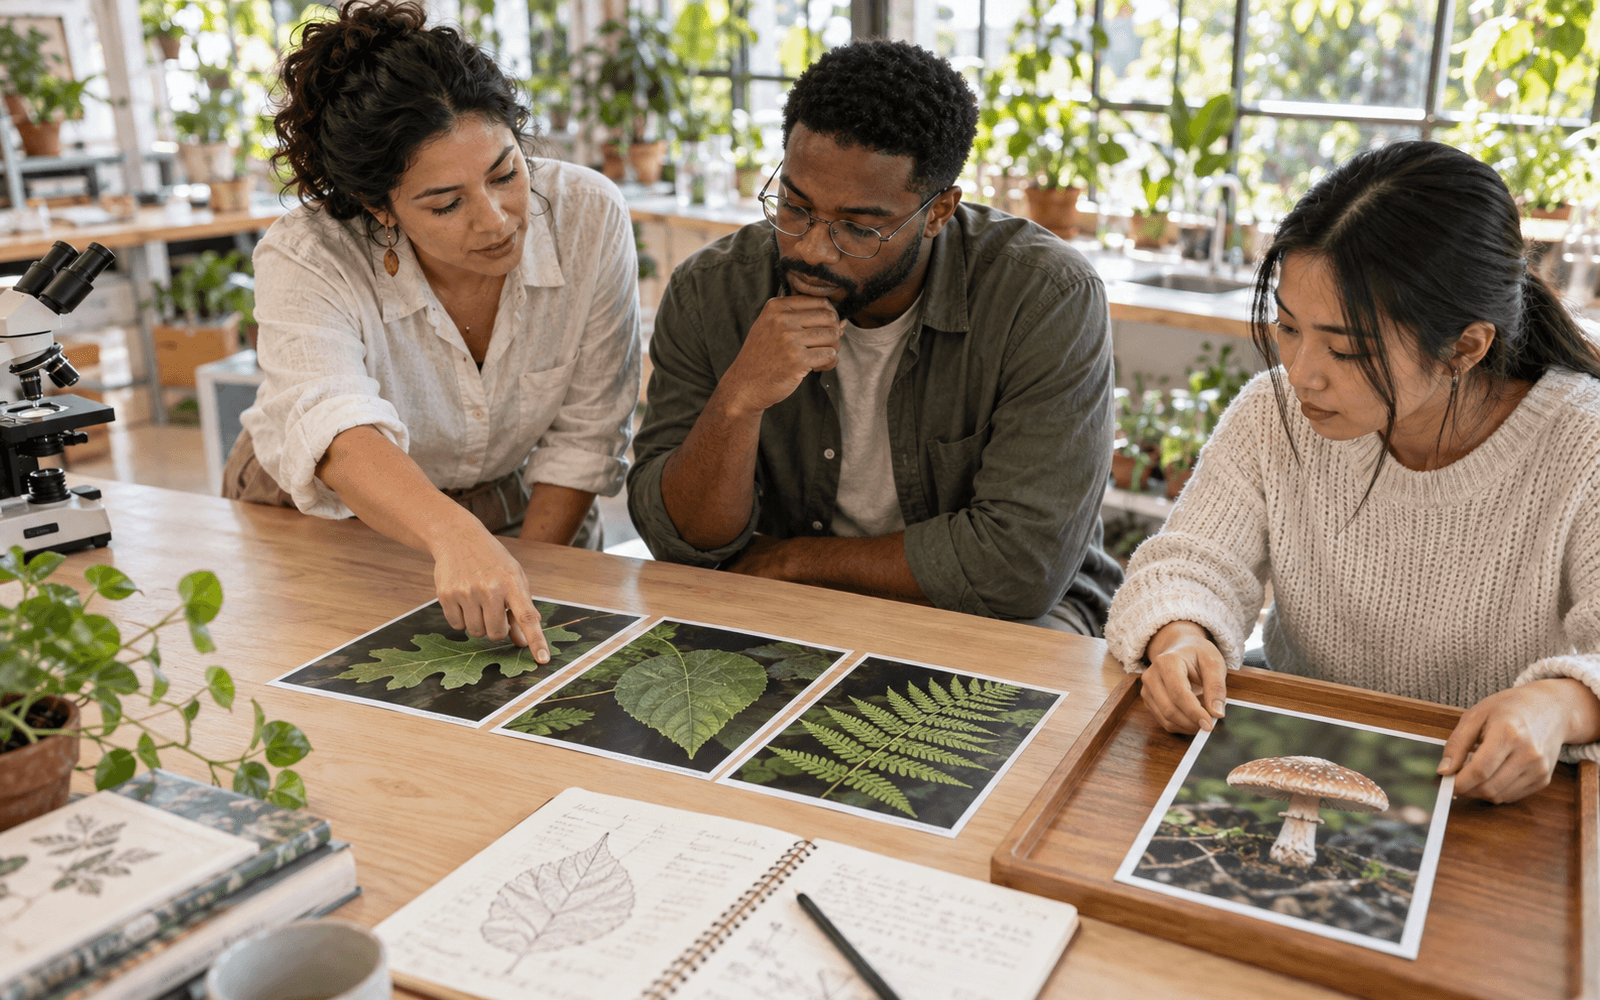
Out-of-distribution detection asks whether an incoming example differs enough from a system's reference data that its prediction may need special handling. A classifier trained to recognize several plant species might receive a photograph of a mushroom, an unfamiliar species, or a badly damaged image. It can still produce one of its available labels. Detection adds a separate question: is this input within the conditions for which the system has been prepared and evaluated?
The relevant boundary depends on the task. A new camera or lighting condition changes the appearance of an image without necessarily changing what it depicts. An unseen category changes what the system needs to recognize. In education, an unfamiliar language, curriculum, age group, or answer format can also create a mismatch. A difference is not automatically harmful, but it must be understood before the model's previous performance is assumed to carry over.
Hendrycks and Gimpel proposed a baseline that uses a classifier's largest softmax probability as a detection score. Correctly classified familiar examples often receive higher scores than mistakes or unfamiliar inputs in their evaluated settings. This supplies a useful comparison point for more elaborate methods. It does not establish that a large probability always means an input is familiar, or that the model's score is a reliable measure of educational correctness.
Other approaches use internal representations, alternative scores, or explicit examples of unfamiliar inputs. Their success must be tested rather than inferred from the method's complexity. Nalisnick and colleagues showed that some deep generative models assigned higher likelihood to certain unfamiliar image datasets than to their training distribution. A score that sounds mathematically appropriate can therefore behave counterintuitively. Research by Hendrycks and colleagues also demonstrates the importance of evaluating larger and more varied real-world detection tasks.
A detection threshold balances missed unfamiliar cases against false alarms on legitimate inputs. Evaluate both types of error using held-out examples that reflect expected use and plausible changes. Testing only obvious mismatches, such as unrelated photographs, may conceal failures on subtly unfamiliar inputs. Keep threshold-selection data separate from final evaluation, and describe which kinds of change were examined. No finite test collection demonstrates reliable detection of every future unknown.
Consider a fictional school botany activity. Learners test a plant classifier with ordinary plant photos, altered lighting, and a mushroom photo. They record the classification and detection result separately. If an unfamiliar case is flagged, the system could request another photograph, explain its scope, or refer the question to a teacher. The response should preserve access to learning; an unusual input should not become evidence that a learner is deficient or should be excluded.
Before using a detector in practice, check whether false alarms fall unevenly across languages, devices, or learner groups. Provide a route to correction and retain only the data needed for legitimate review. Out-of-distribution detection is one component of a broader reliability process. It can help expose situations that deserve caution, but it neither repairs a prediction nor proves that accepted inputs are safe, fair, or educationally useful.