← 研究ニュースに戻る

#assessment design

assessment design

3 論文

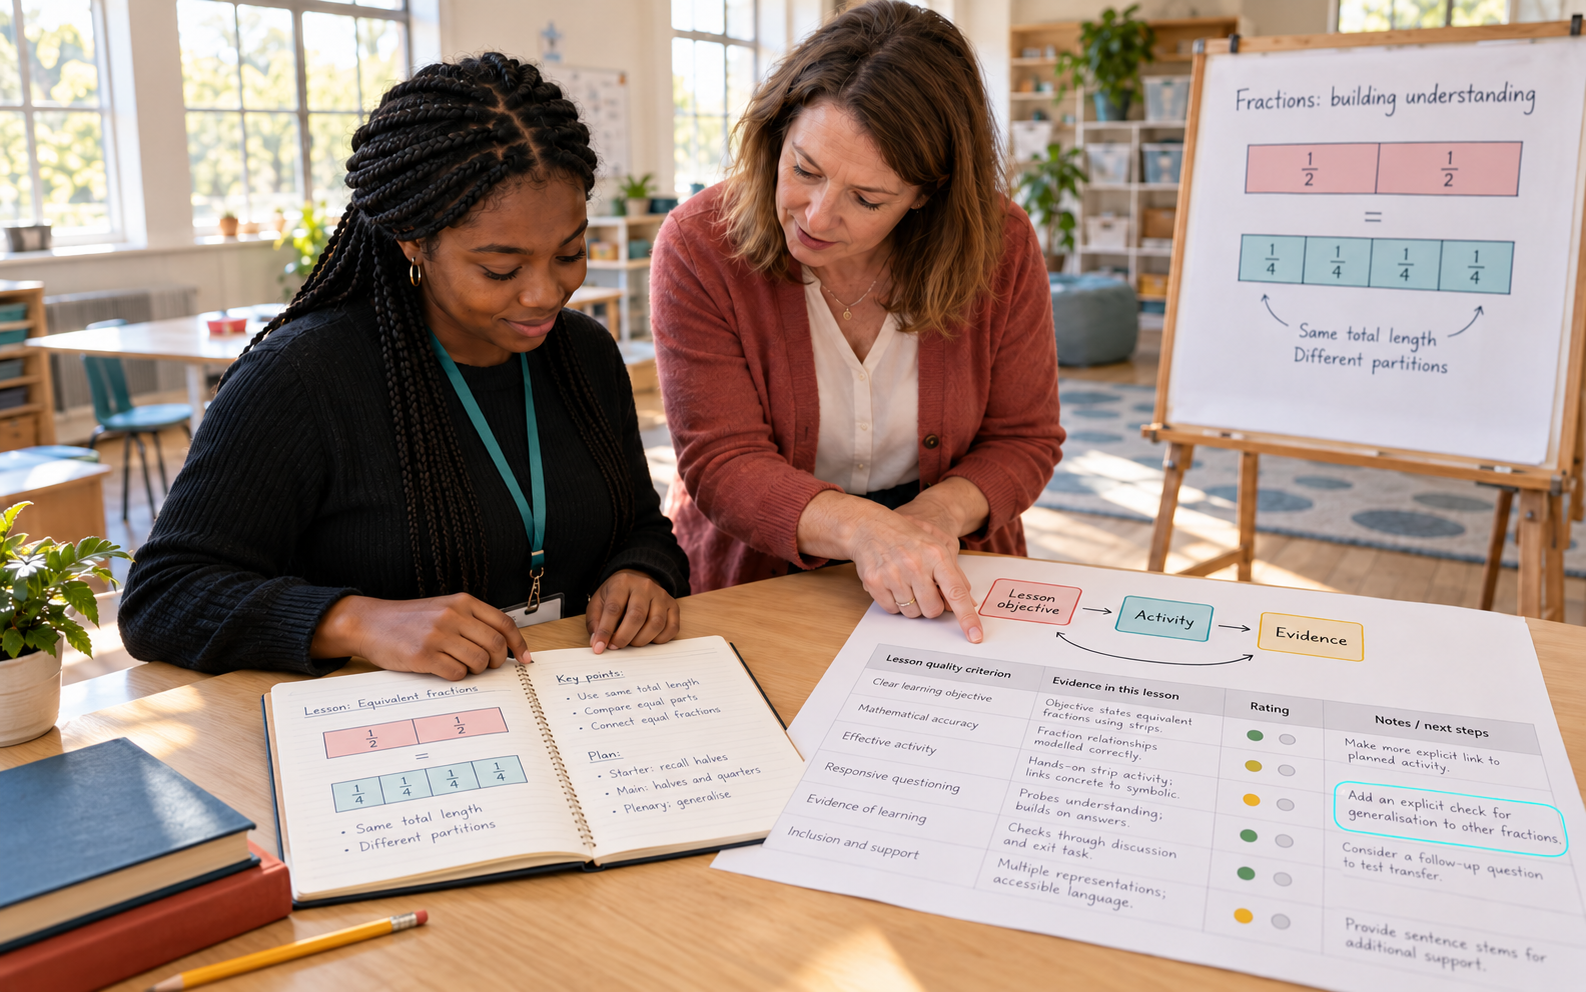
A White woman teacher educator and a Black female trainee review an annotated lesson-planning notebook and a marked assessment rubric beside an equivalent-fractions classroom diagram
ジャーナル論文2026
ジャーナル論文 220

Project scores improved with teacher and AI feedback in a structured university course

Valentina Grion, Beatrice Doria, Daniele Agostini, Giorgia Slaviero

Assessment & Evaluation in Higher Education

A University of Padua study compared two AI feedback systems with teacher feedback in a course involving 238 students. Forty-seven project groups entered the final analysis, and average project scores rose from 23.81 to 27.70 out of 30. The study found bounded evidence of comparability between sources, alongside a substantial ceiling effect. Its results concern a shared assessment design and revised projects, rather than proving general interchangeability between teachers and AI.

teacher educationassessment designproject-based learning
500語要約を読む →
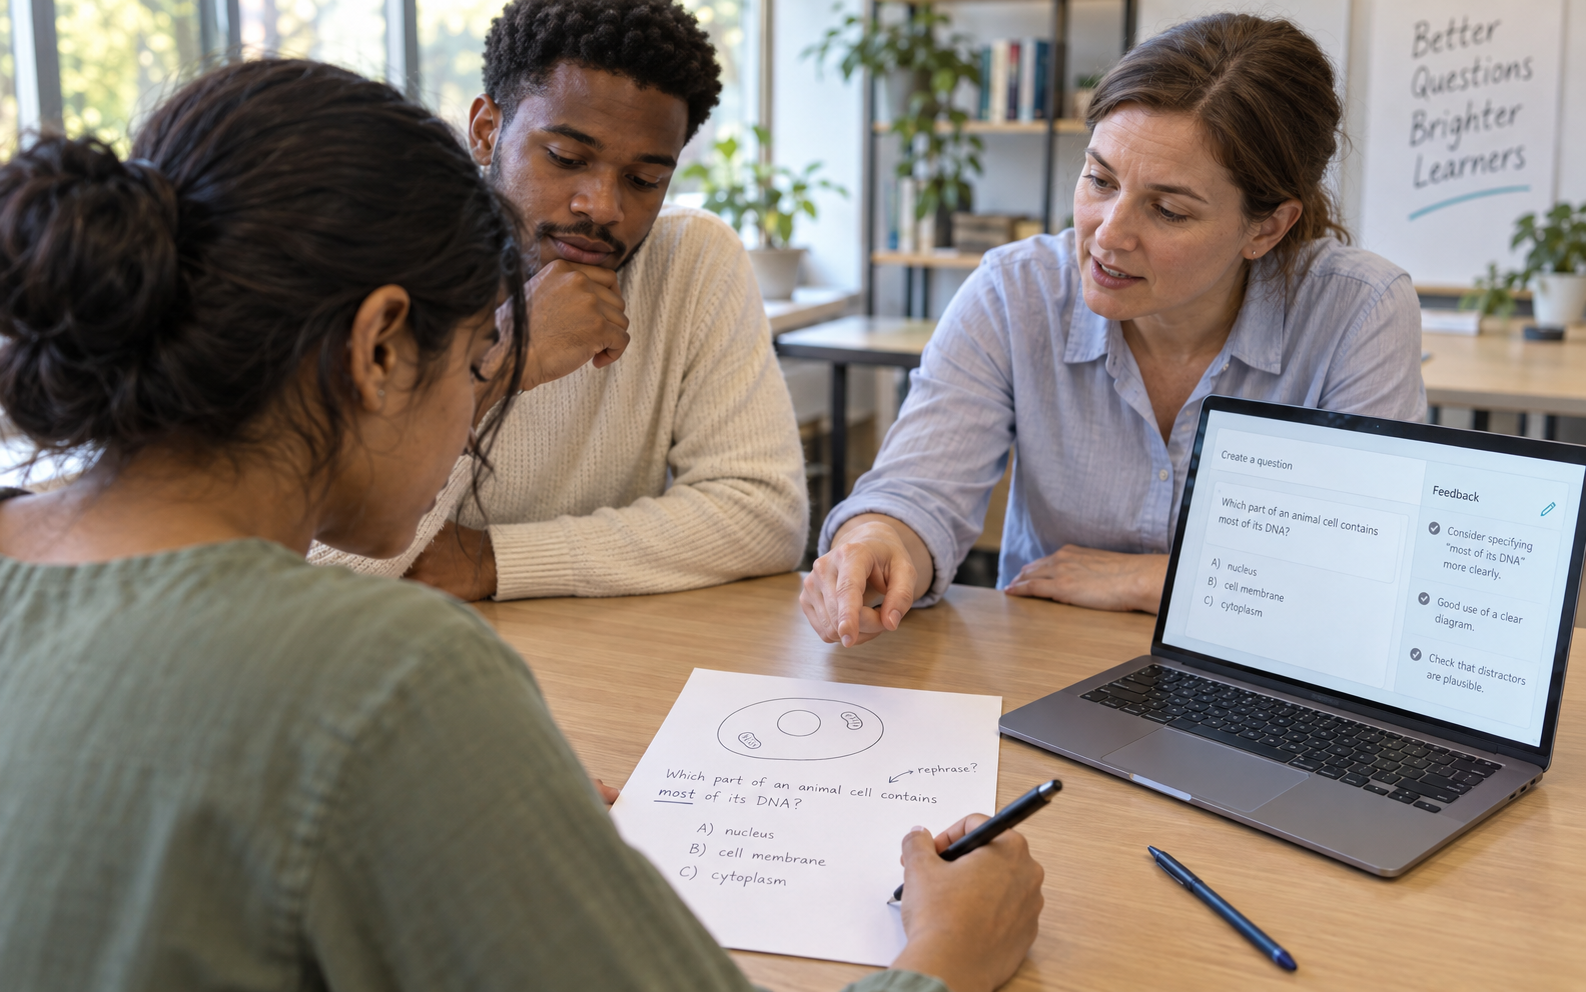
A university student revises a biology multiple-choice question while a classmate and lecturer consider feedback shown beside a simple animal-cell drawing.
ジャーナル論文2025
ジャーナル論文 212

AI-Assisted Co-Creation: Bridging Skill Gaps in Student-Generated Content

Stanislav Pozdniakov, Jonathan Brazil, Mehrnoush Mohammadi, Mollie Dollinger, Shazia Sadiq, Hassan Khosravi

Journal of Learning Analytics

Students often rated AI feedback positively when creating multiple-choice questions in RiPPLE, but visible revision followed in only about 35 percent of editing sessions. The study examined feedback, activity logs, and student comments across introductory university courses. Its findings separate liking a response from using it and from learning through it. They suggest that question-authoring activities need explicit support for evaluating feedback, alongside safeguards against inaccurate or irrelevant suggestions.

Learning AnalyticsStudent AgencyAI Feedback
500語要約を読む →
A programming lecturer and two diverse university students inspect compiled code, an inheritance diagram, and a grading rubric in a computer laboratory
ジャーナル論文2026
ジャーナル論文 102

Five AI systems outscored the average OOP cohort but still failed compilation and advanced concepts

Marina Lepp, Joosep Kaimre

arXiv preprint

Lepp and Kaimre evaluated ChatGPT-5.2, DeepSeek-V3, Gemini 2.5 Flash, Claude Sonnet 4.5, and Microsoft 365 Copilot on authentic introductory OOP tests and examinations using student grading criteria. Systems exceeded the historical average and often solved long tasks, yet some code did not compile and interfaces, abstract classes, inheritance, and image-based questions remained difficult. The results challenge take-home assessment validity without proving student learning.

programming assessmentobject-oriented programminggenerative AI
500語要約を読む →