AI-Assisted Co-Creation: Bridging Skill Gaps in Student-Generated Content
Stanislav Pozdniakov, Jonathan Brazil, Mehrnoush Mohammadi, Mollie Dollinger, Shazia Sadiq, Hassan Khosravi
Journal of Learning Analytics
500語要約
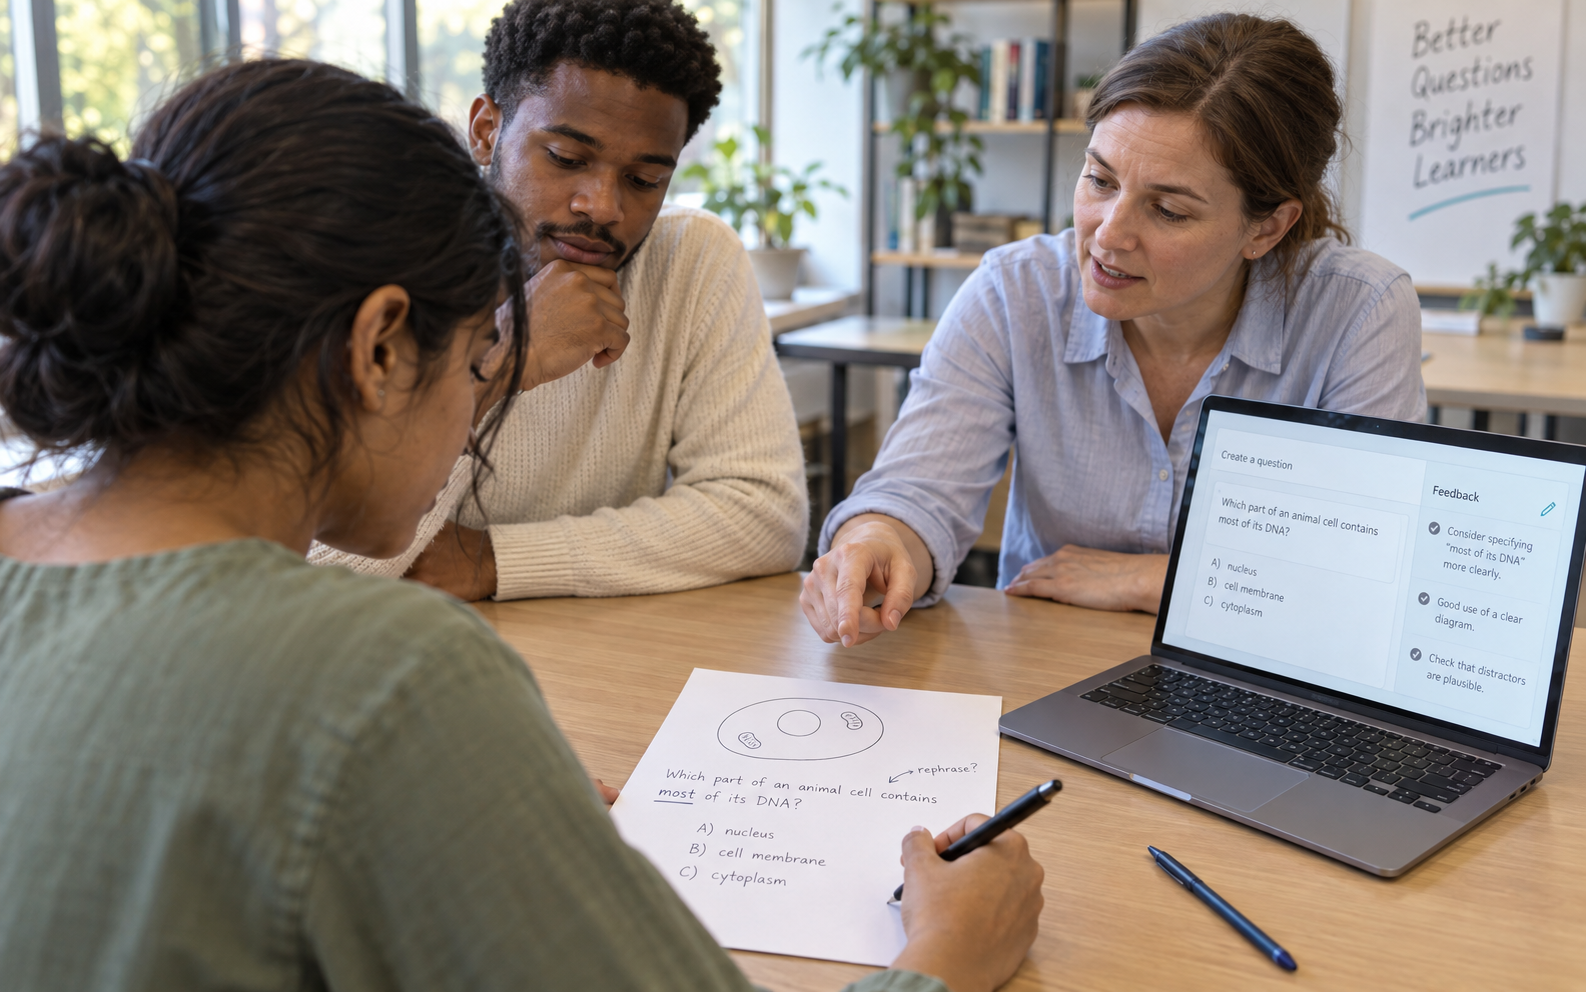
Asking students to write assessment questions can reveal what they understand about a subject. AI feedback may help them improve the wording, answer choices, and explanations, but receiving a useful-looking comment is only the start of that process. A Journal of Learning Analytics study of RiPPLE shows a gap between positive reactions to AI feedback and the revisions visible in students' activity logs.
Stanislav Pozdniakov and colleagues examined an Australian university setting spanning introductory information-systems, economics, and health-sciences courses. Students created multiple-choice resources as part of assessment work, including a question, correct and incorrect options, and explanations. Once they had a draft, they could request AI feedback in a sidebar. The feedback summarized the resource, identified strengths, and suggested improvements. Students retained the option to proceed without adopting the advice or to disable assistance.
The research combined several sources of evidence rather than relying on a satisfaction survey alone. The authors analyzed 1,063 feedback instances linked to student-created questions, activity traces, 3,324 helpfulness ratings, and 601 comments. These are different analytic units, not a single sample size to apply to every result. The feedback analysis examined its focus, readability, and tone, while the logs examined the sequence of actions after students requested help.
Learners generally responded positively: 79 percent of helpfulness ratings were positive, twelve percent neutral, and nine percent negative. Comments appreciated clarity, encouragement, and suggestions about question design or disciplinary explanation. Other comments identified incorrect information, repetition of changes already made, misunderstandings of the question's purpose, or advice that was difficult to act on. Positive sentiment therefore coexisted with concrete quality problems that students needed to recognize.
Visible behavior was more selective. In approximately 65 percent of resource-creation sessions, the next step after feedback was self-assessment rather than editing. The authors summarized active attempts to revise as occurring in about 35 percent of sessions. When learners did revise, they often changed the question body or answer options. These logs show observable interaction patterns, but they cannot fully reveal whether a student considered and reasonably rejected a suggestion, felt satisfied with the draft, or overlooked a useful improvement.
The study does not establish that feedback caused better questions or improved subject knowledge. It lacked a randomized comparison for those outcomes, and helpfulness reports are not independent assessments of learning. The authors also used language models to help classify feedback content, with human checks and acknowledged disagreements; that analytical process carries its own uncertainty. Findings from this interface, prompt design, and university context should not automatically be extended to essays, projects, or younger learners.
For instructors, the practical opportunity is to connect AI comments with an explicit decision. Students could explain which suggestion they accepted, which they rejected, and why the final question better tests the intended concept. That would make judgment more visible without assuming every suggestion deserves adoption. It remains a teaching implication to test, not an intervention proven by this study. The research offers a realistic account of feedback reception and use, and a reminder that the path from a positive rating to stronger independent understanding still needs to be demonstrated.