Students’ feedback ratings reflected source credibility without consistently matching expert judgments
Tanya Nazaretsky, Hagit Gabbay, Tanja Käser
Computers and Education: Artificial Intelligence
Ringkasan 500 kata
A study by Tanya Nazaretsky, Hagit Gabbay, and Tanja Käser examines how students judge feedback when human and AI sources are involved. The researchers paired feedback variants for 979 authentic responses from six EPFL STEM courses and analyzed evaluations from 472 students. Their rubric distinguished pedagogical features at sentence level, offering a more detailed comparison than a single helpfulness score.
Expert analysis found broadly comparable feedback quality, with statistically significant differences associated with small effects. Students’ ratings were related to perceived provider credibility. Their judgments aligned with some expert measures for human feedback, but the corresponding alignment was absent for AI feedback. The authors also found gaps in metacognitive support in both kinds of feedback. These are findings about messages and perceptions, not demonstrated advantages in learning.
The study involved one institution and a single evaluation occasion. It did not assess feedback uptake or performance gains, and its models left substantial variation unexplained. Prior experiences with AI and other relevant personal characteristics were not fully captured. The result therefore does not establish that students always misjudge AI advice, or that source information alone caused every rating difference.
For AIEDHK, an editorial teaching proposal is to turn feedback evaluation into a small, visible reasoning task. Before choosing whether to follow a comment, a learner could identify the claim it makes about the work, check that claim against the original response, and specify what an adequate revision would accomplish. Source identity would remain available, but students would have to provide evidence for their judgment. This activity has not been validated by the reported study; it is a concrete candidate for a classroom pilot.
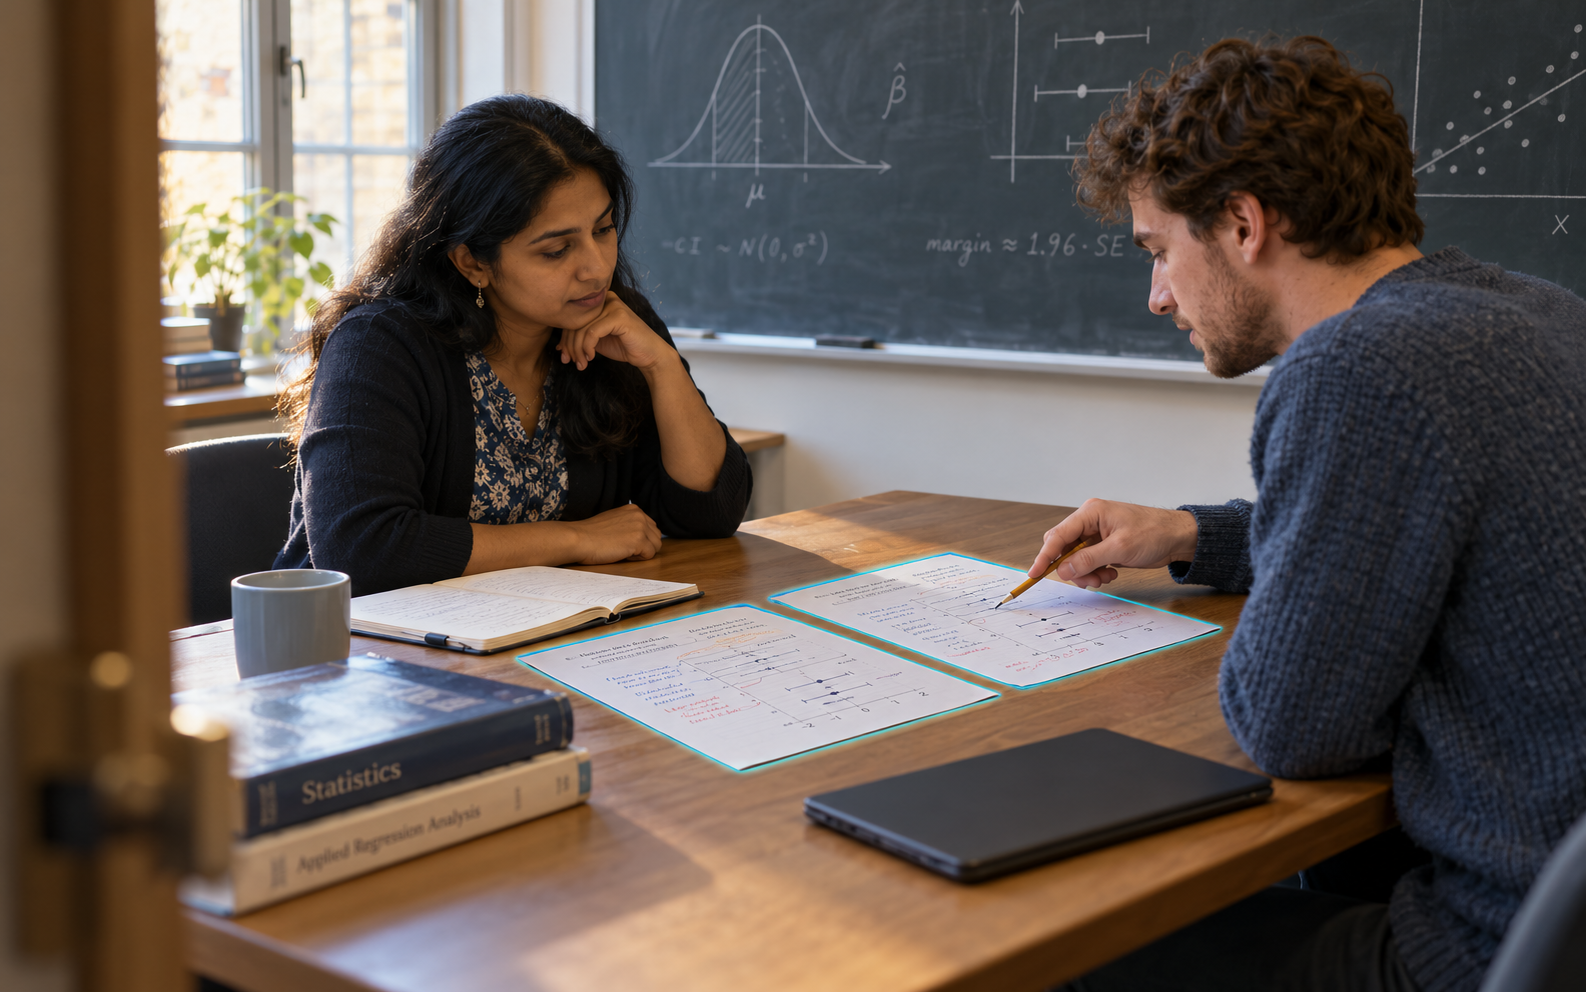
In a statistics class, for example, students might compare two comments on the interpretation of a confidence interval. One sounds reassuring but leaves the misconception untouched; another points to a specific error and asks for a corrected explanation. The teacher could ask pairs to highlight the exact words that support each evaluation. Revealing or discussing provenance after an initial reading could then open a conversation about why opinions changed. The aim would be defensible evaluation, without treating either human authorship or automated generation as a substitute for checking the mathematics.
A classroom assessment could retain the first judgment, the evidence cited, and the eventual revision. An independent follow-up problem would give a different kind of information from a satisfaction survey. Teachers could also examine disagreements between student and expert ratings rather than immediately averaging them away: a learner might notice that a technically correct comment is difficult to act upon. Such disagreements would need discussion, because an expert rubric and a student experience can illuminate different aspects of the same feedback encounter.
For institutions purchasing feedback systems, this distinction suggests a cautious evaluation plan. Ask whether a tool produces accurate and usable advice, whether students can explain their response to it, and whether later independent work improves. Each question needs its own evidence. A high approval rating could help identify an accessible interface, but it should not be the sole basis for an educational claim. The proposed comparison activity offers one way to start gathering richer evidence while keeping judgments about effectiveness open.