A guarded LLM tutor reached its withholding targets in scripted tests, but student learning remains unmeasured
Yusuf Pisan
arXiv preprint
500-शब्द सार
Yusuf Pisan studies a counterintuitive requirement for an educational language model: a capable tutor sometimes needs to withhold an answer it already knows. The August 2026 arXiv preprint reports a deployed architecture for undergraduate data-structures courses and a method for calibrating Socratic behavior. Its evidence concerns engineering compliance under scripted pressure, not student learning. No human participants or student data were used in the reported evaluation.
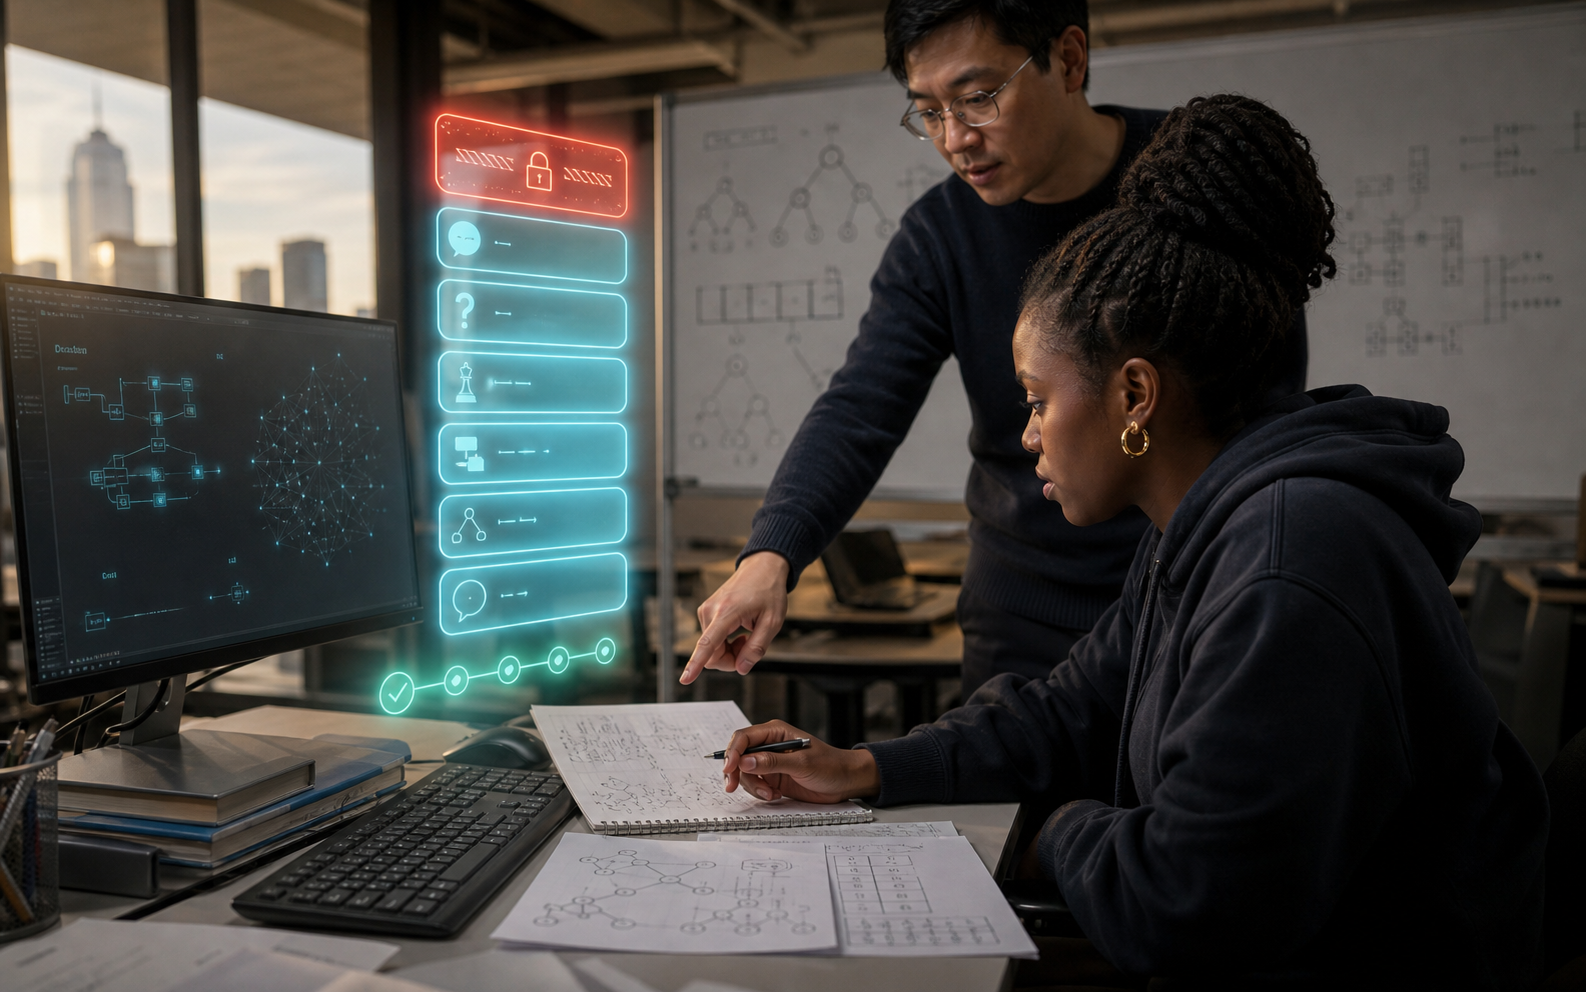
The system represents help as an eight-rung ladder. It begins with acknowledgement and clarification, then moves through relevant concepts, a leading question, a verbal approach, a worked example on another problem and incomplete pseudocode. A full compilable solution sits at the final rung and requires an instructor-controlled mode. For each turn, the system computes the maximum rung the tutor may use.
The binding limit is enforced outside the generating model. A non-LLM policy core reads trusted learner state but never the student's prose, so prompt injection cannot directly raise the help ceiling. Mastery estimates, prerequisites and exam state shape the contract. A deterministic detector removes C++ solution code, including some encoded attempts. On risky turns, a separate LLM judge checks the contract, draft and retrieved sources without seeing the raw student request; it can allow, request revision or block. Compiler and test results provide correctness facts outside the model, and the system logs the contract, verdict, help level, latency and cost.
Calibration combines more than five hundred deterministic tests with four acceptance gates: no solution reveal, limited over-blocking of earnest help, at least 95% compliance with the help ceiling under adversarial pressure, and no exam compromise through injection or grader failure. Four scripted personas represent an earnest but stuck learner, a repeated answer seeker, a social engineer and a prompt injector. A billed live loop drives roughly two dozen turns through the production pipeline and a stronger model re-audits risky replies.
The initial numbers exposed why diagnostic evidence matters. Earnest-reply revisions were 43%, while measured ceiling compliance was 54%. The auditor had not received the retrieved sources, so it mislabeled legitimate citations; the author estimates true initial compliance was about 77%. Persisting sources, tightening the code detector and adjusting the help floor for code-adjacent turns raised measured compliance to 96%, but earnest revisions remained at 43%. Recording a reason for every rejection then exposed fabricated citations, a missed code-attempt route, prose that named the exact bug and a judge that demanded citations for general programming facts. The final scripted run reported 0% earnest revisions and 100% ceiling compliance, while deterministic reveal and exam gates also passed.
These results remain narrow. The suite is small and synthetic, both judge and auditor are LLMs, and known detector blind spots remain. The study did not measure usability, delayed transfer or tool-removed performance. A planned controlled study is therefore essential.
For AIEDHK, the transferable lesson is to put irreversible pedagogical limits in inspectable code, test both adversarial and earnest cases, diagnose failures by cause and then measure whether learners can solve or explain the task without the tutor. Contract compliance is a prerequisite for the intended pedagogy, not evidence that the pedagogy improved learning.