Preprint: Grammar-game traces reveal context-sensitive reasoning patterns
Trystan Geoffre, Zheng Yuan, Thierry Geoffre
arXiv manuscript
500-शब्द सार
A manuscript posted on October 26, 2026 examines how action sequences in a grammar game can inform a more specific account of learner difficulties. Trystan Geoffre and colleagues analyze 36,234 interactions from 234 students across 42 morphosyntactic exercises. Their framework combines interpretable strategy indicators with a coordination-demand index, then groups activity into four states. It attempts to describe how learners approach a task rather than relying only on a final correct or incorrect response.
The authors report substantial variation with context and predictive performance for validation success. However, the study is observational and focuses on French morphosyntax in one educational context. The paper explicitly leaves causal effects of hint timing and type for future randomized trials. Its indicators are model-based interpretations of behavior, not direct measurements of thought or emotion. This report treats the accessible arXiv version as a preprint; a journal name on the manuscript is not taken as independent confirmation of publication status.
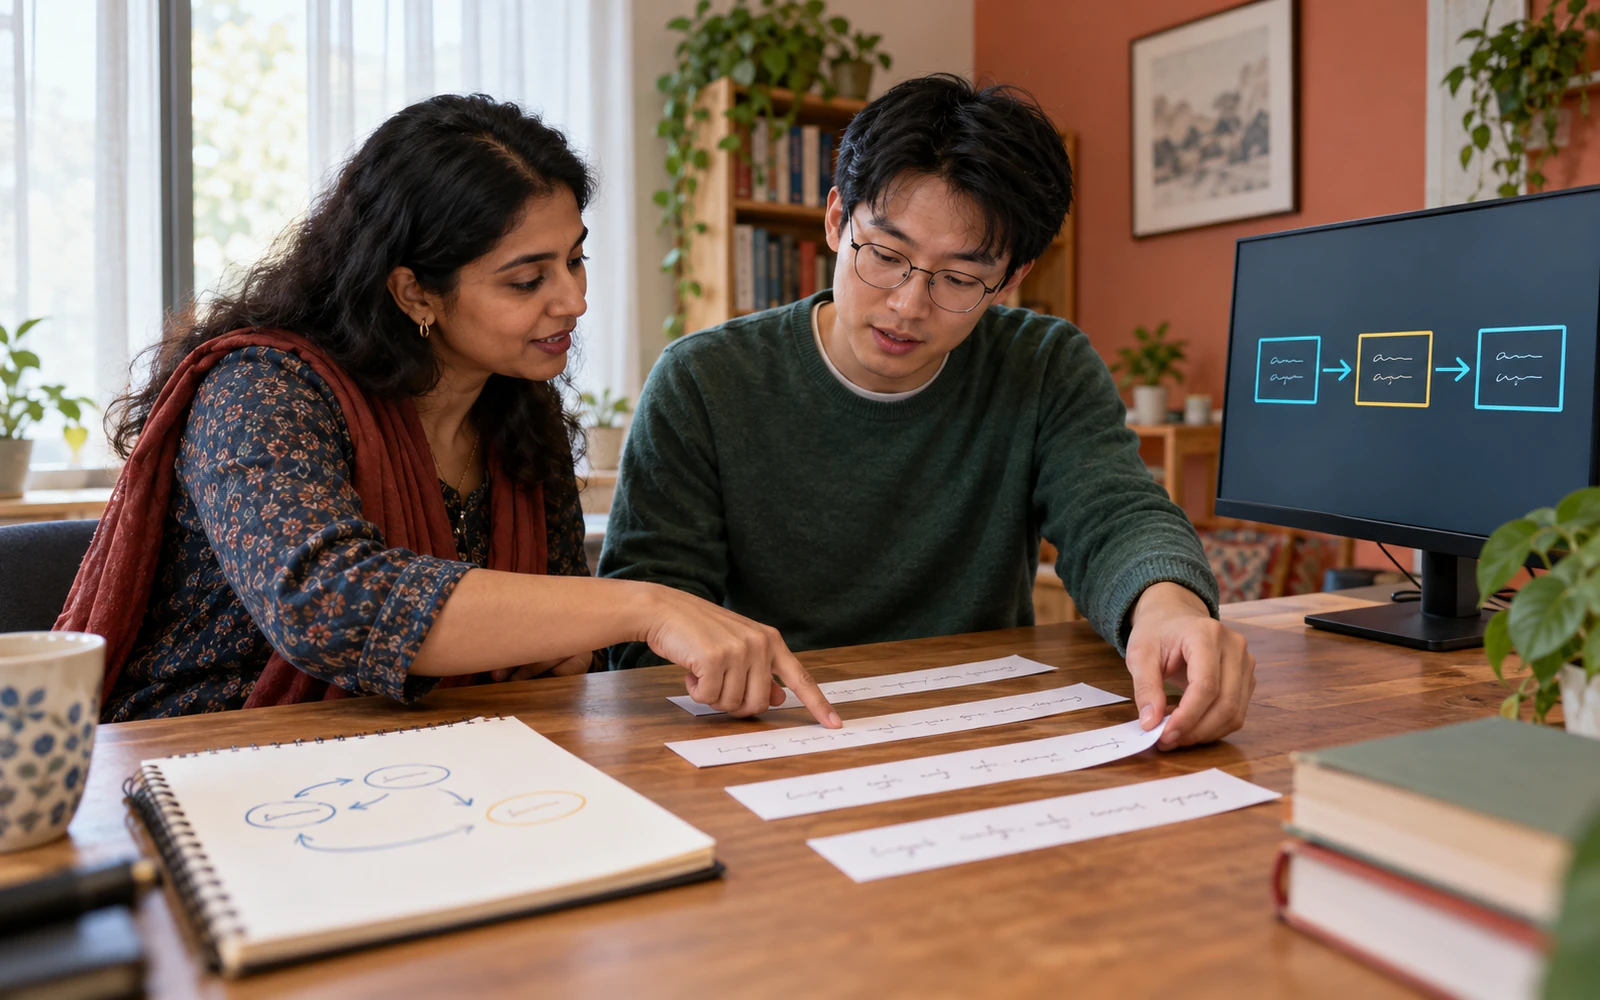
For teachers, the work invites a useful distinction between a response and the process that produced it. The following classroom-review activity is an AIEDHK proposal. A language teaching team could examine two fictional attempts that end with the same grammatical error. In one attempt, a learner changes several choices quickly. In the other, the learner repeatedly revises one relationship after careful pauses. The team would list possible explanations and identify what further evidence would distinguish them.
A short follow-up question might be more informative than an immediate label. The teacher could ask the learner to explain which words need to agree or to show the relationship with a simple diagram. If the explanation reveals a sound rule but difficulty coordinating several parts of the sentence, the next task might reduce the number of simultaneous decisions. If the rule itself is unclear, a contrasting example could serve a different purpose. These choices would be hypotheses to check in the learner's subsequent work.
The team could then test whether a proposed dashboard preserves uncertainty. Does it show the observations behind a flag? Can a teacher record an alternative interpretation? Does the display distinguish a repeated error from evidence that an intervention helped? A useful interface would support those questions without turning a temporary pattern into a stable description of a learner. Students should have a way to explain what the recorded sequence missed.
Before a pilot, educators could decide which traces are necessary and avoid collecting additional information merely because the software permits it. A small set of relevant actions may be enough to evaluate the proposed support process. The evaluation could compare the teacher's initial interpretation, the support offered and a later independent response, while keeping usability and learning outcomes separate.
The research contribution is a more structured way to inspect behavioral evidence. Its practical value for education will depend on whether the interpretations remain meaningful across tasks and whether the resulting teaching decisions help learners. Predicting a validation event is an intermediate result, not the endpoint of that evaluation.