Preprint: Tutoring logs add little to simple score predictions in one course
Zeyu Dong, Mikael Kwame Kuada, Asa Holley Buchakjian-Tweedy, Ibrahem Aljabea
arXiv preprint
৫০০-শব্দের সারাংশ
An October 24 preprint by Zeyu Dong and colleagues examines whether summaries of AI-tutor interactions improve assignment-score prediction over simple constant baselines. The StudyChat corpus contains 16,851 exchanges, but the supervised analysis has outcomes for 175 student-semester records. These are different units of evidence. The study compares six fitted estimators using repeated nested cross-validation and describes its results as retrospective prediction, not an early-warning intervention.
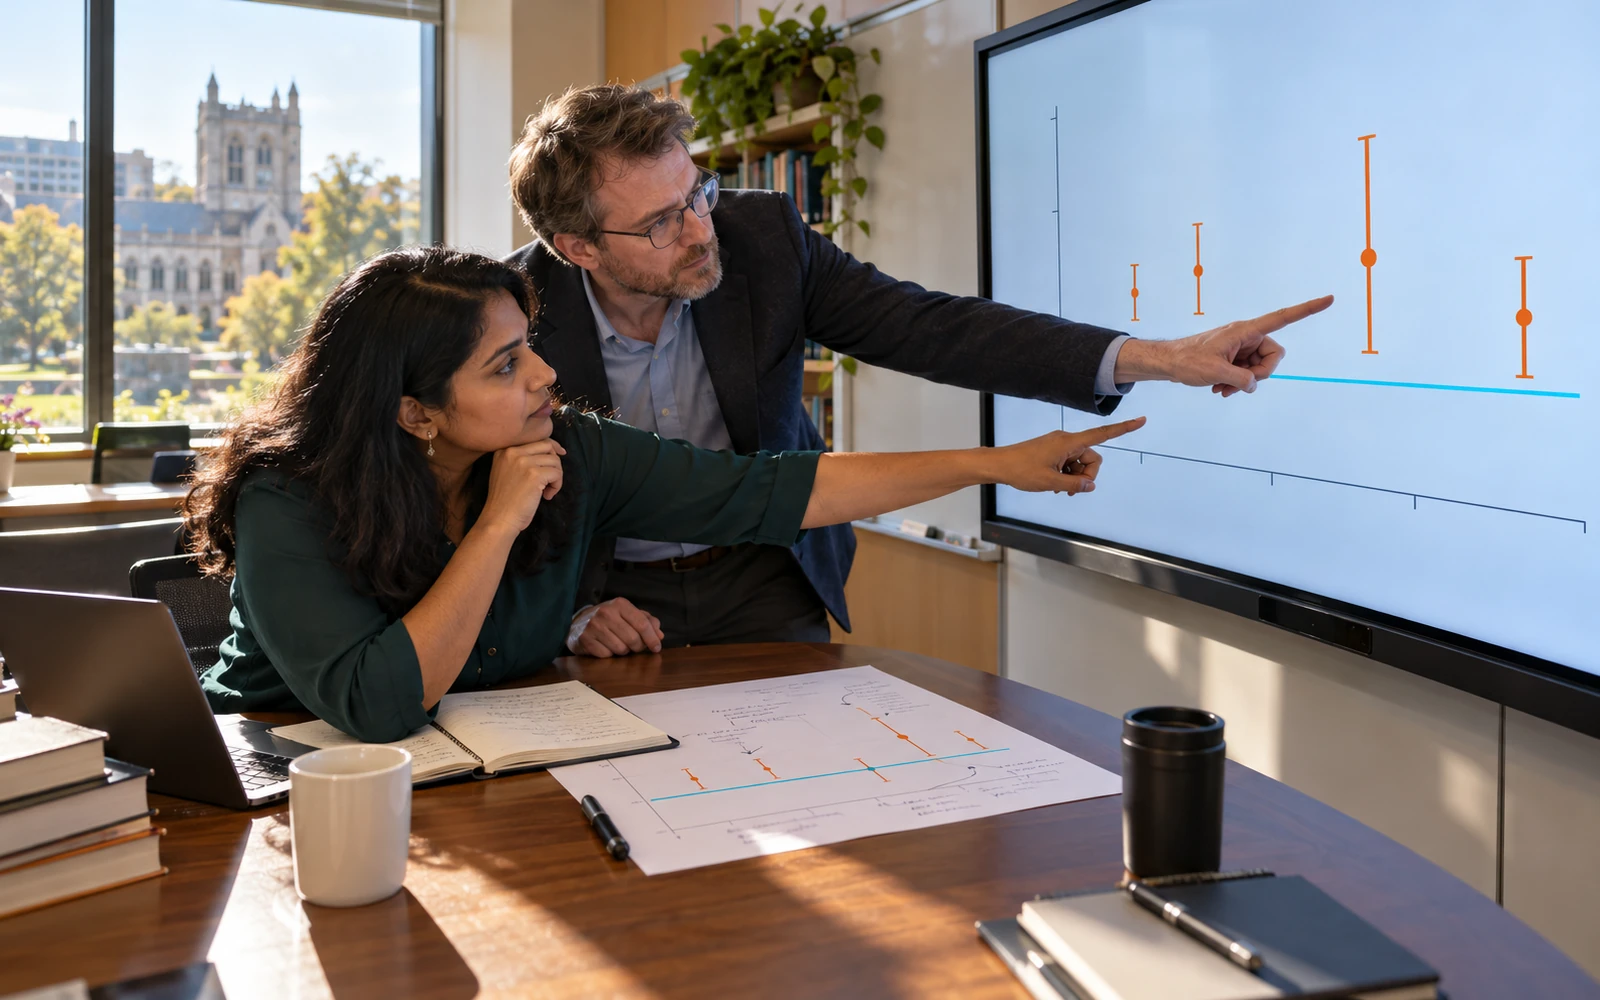
Gradient boosting achieved a mean absolute error of 3.023 grade points, compared with 3.138 for the median baseline. The reported conditional bootstrap interval for the difference crosses zero. Scores were concentrated near the ceiling, and the model ranking changed when the authors examined lower-scoring students. The analysis does not establish a learning effect or added predictive value beyond prior academic performance. Its central contribution is a closer look at what the chosen comparison and error distribution allow a researcher to claim.
For a teaching team, this suggests an accessible evaluation exercise. The following is an AIEDHK proposal using fictional data. Create a small set of assignment scores, most near the top of the scale, and ask participants to predict every score using the training group's median. Then compare those predictions with a mock system's outputs. A simple method can look surprisingly strong when the range of observed outcomes is narrow.
Next, inspect the individual errors. Participants could mark the cases where a prediction would have caused a teacher to overlook a learner who needed support. They could also identify unnecessary alerts and discuss the consequences of each type of mistake. A single average error gives neither decision a complete answer. The exercise should make the intended support action explicit before selecting the measurement used to judge the model.
The time at which information becomes available needs equal attention. If a feature summarizes conversations from the whole semester, it cannot automatically support a claim about identifying difficulty before the first assignment. Reviewers could draw a timeline and place each input on it. Any proposed early-support system would need to be evaluated using only information available at the actual decision point, with an outcome that occurs afterward.
Students and teachers could also examine what a prediction leaves unexplained. Frequent requests for help might reflect productive persistence, confusion, accessibility needs or the structure of an assignment. A model can find an association without resolving these interpretations. A follow-up conversation and the learner's actual work may provide information that an interaction count cannot. The prediction should therefore remain open to correction rather than becoming a fixed description of a student.
Before deploying an analytics tool, an institution could require a meaningful baseline, errors for the intended population and a prospective test of the proposed support process. It could then check whether teachers can act on the information and whether the action helps. This preprint provides a useful warning against skipping those steps simply because a fitted model produces a plausible score.