A Sri Lankan case study found AI use varied across assessment functions
Amali Henadirage, B. T. K. Chathuranga, Nuwan Gunarathne
International Journal of Educational Technology in Higher Education
৫০০-শব্দের সারাংশ
Amali Henadirage, B. T. K. Chathuranga, and Nuwan Gunarathne studied AI assessment practices at a management faculty in Sri Lanka. Their evidence included 15 interviews with nine academics and document analysis, collected between April and June 2024. Published in January 2026, the paper examines how adoption differed across parts of academic work, rather than measuring an AI intervention’s effect on student attainment.
The researchers interpreted reported practices using the SAMR model and institutional theory. They found more developed AI use in assessment design and setting, while grading and feedback largely remained at a substitution level. Professional expectations and norms were identified as a prominent adoption driver. The interviews also described concerns about contextual understanding, accuracy, and institutional support.
This is a single-faculty qualitative case, with purposively selected academics who already used ChatGPT. It cannot estimate national adoption rates or establish learning benefits. The accounts also describe an earlier period of rapidly changing technology. Their value is a detailed example of uneven adoption: a department can use AI to prepare questions while maintaining quite different practices for deciding grades.
For AIEDHK, an editorial governance proposal is to document AI use by assessment function. A faculty team could separately record who drafts a question, checks its disciplinary accuracy, approves the task, evaluates responses, and resolves disputed judgments. That exercise would avoid treating the whole process as a single yes-or-no adoption decision. It would also make clear where responsibility sits when an apparently small drafting aid begins influencing what students are asked to demonstrate. This proposal is not an intervention evaluated in the study.
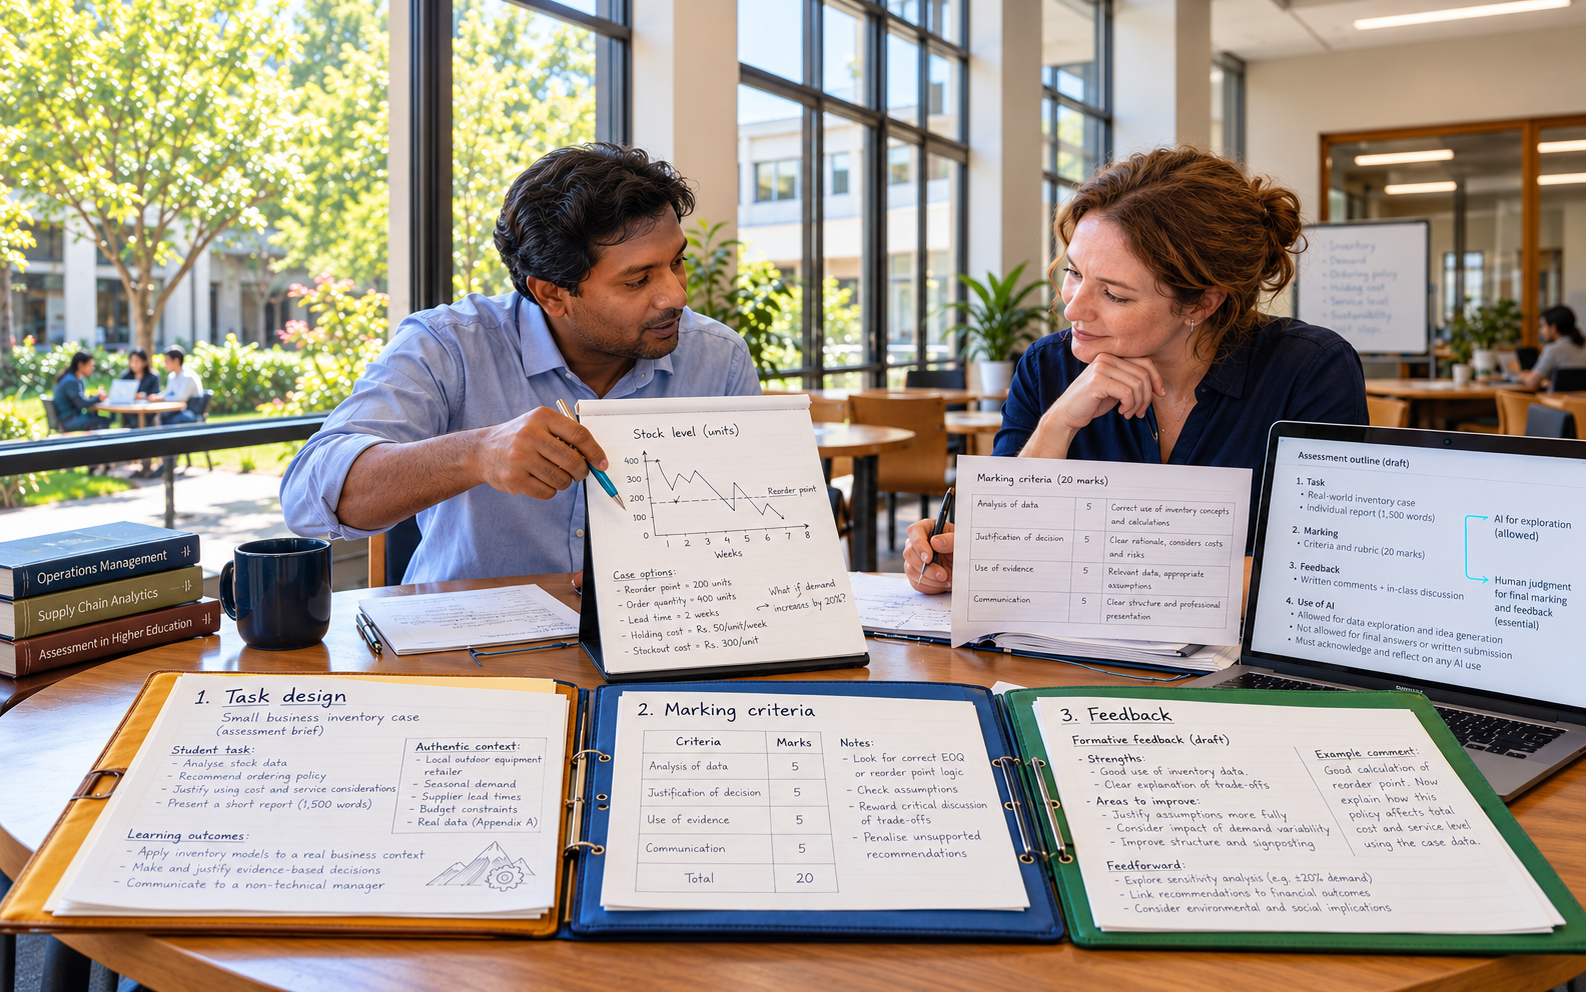
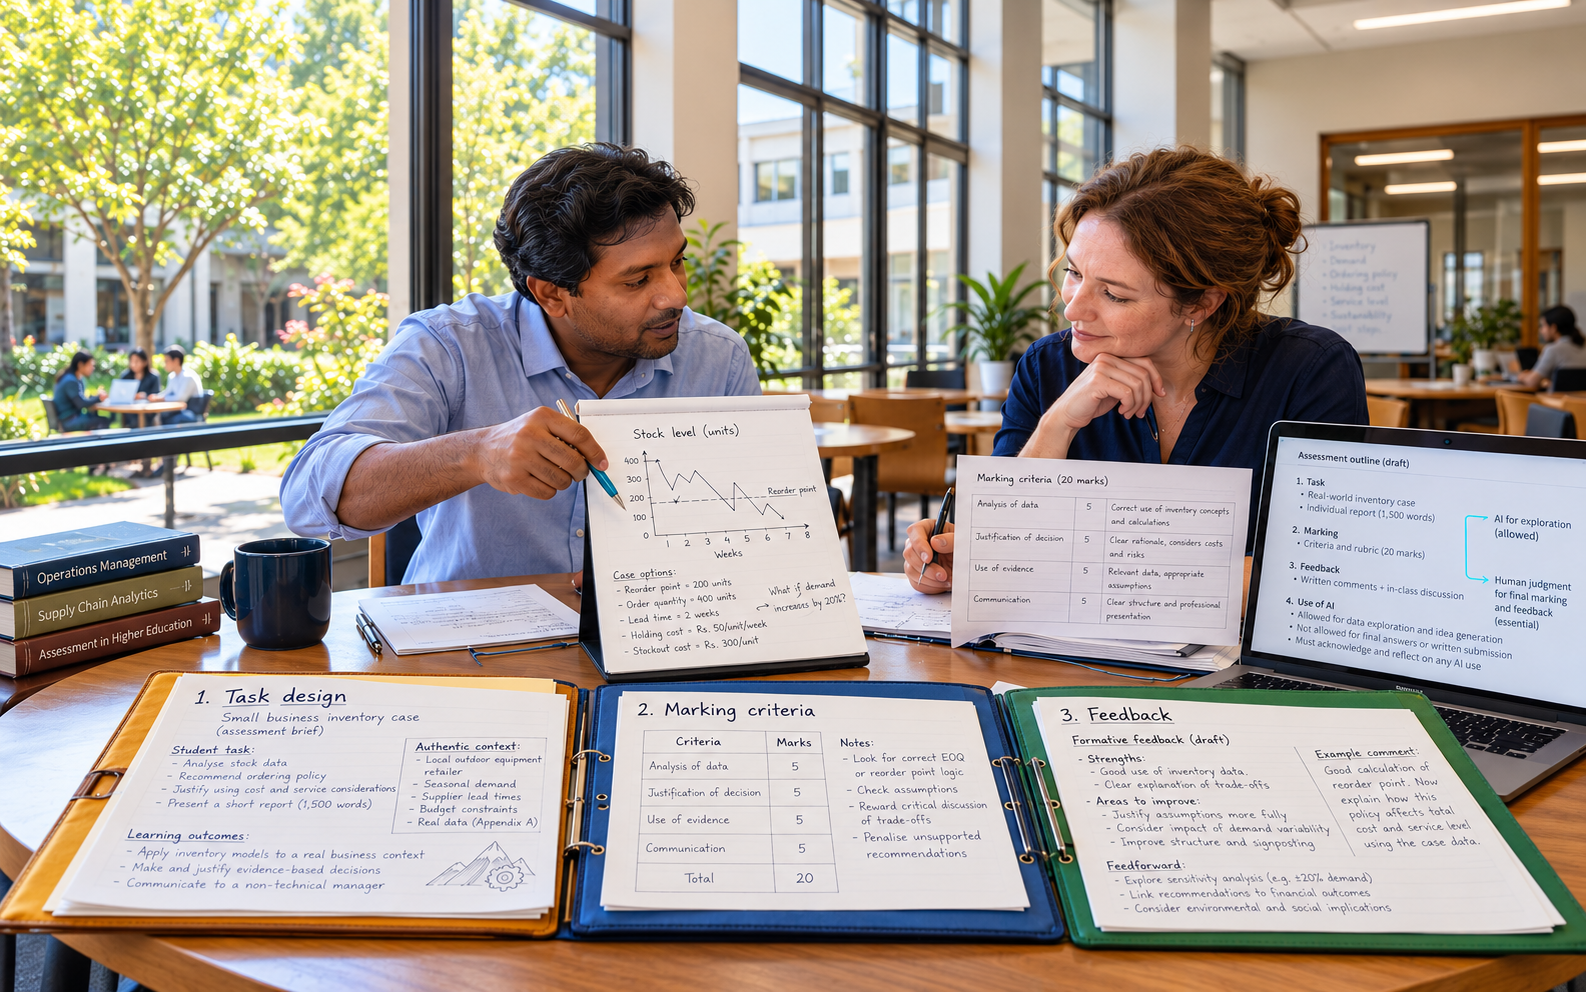
Consider a management lecturer preparing a case about a small firm’s inventory decision. An AI tool could suggest alternative scenarios, but a subject specialist would still need to verify that the numbers and constraints make sense. A colleague could then test whether the marking criteria reward the intended reasoning. If the same tool later drafts comments on student submissions, that would introduce a separate use requiring its own review. Approval to brainstorm a case would not automatically answer questions about the quality of generated judgments.
Professional development could use that concrete workflow as a discussion object. Academics could bring one draft task, explain where assistance entered, and show the changes made after checking it. A peer might identify an implausible business assumption or a criterion that accidentally rewards polished prose over analysis. Recording the issue and resolution would create a practical teaching resource. It would not prove that the revised task improves learning, but it would let a department inspect the basis for its assessment decisions.
A local evaluation could then examine a small set of outcomes: question accuracy, alignment with course objectives, consistency of marking, student understanding of expectations, and staff review time. It should keep those measures distinct from tool-use frequency or enthusiasm. The study’s case encourages institutions to ask which part of assessment is changing and why. The proposed response is a more explicit account of academic responsibility, followed by evidence about the particular task and students affected.