Preprint: Lecture audio-description rules and listener preferences did not always agree
Stylianos Psychias, Yingqiang Gao
arXiv preprint
500 字摘要
An October 12 preprint by Stylianos Psychias and Yingqiang Gao introduces AD4Edu, a benchmark for audio descriptions of university lectures. The corpus draws on 66 recordings covering six subjects. Its 45-rule framework combines existing guidance with provisional education-specific rules, while an evaluation tool checks aspects of description quality. Four blind or low-vision raters assessed 400 pairs of descriptions.
The researchers found that rule compliance and listener preference could diverge. A rubric agreed strongly with judgments about resolving references such as pointing, but much less with preferences about length. Some raters preferred longer descriptions that the framework penalized. The study also found that its preference-optimization training did not consistently improve the earlier model baseline across evaluation measures.
The evidence is preliminary and not peer reviewed. Four raters cannot represent the full diversity of accessibility needs, and their agreement was low. Descriptions were played separately rather than inserted into lecture audio, so extra length did not compete with the lecturer’s speech. The benchmark also relies on machine-generated reference descriptions that professional describers had not checked. It is an evaluation resource, not a certification of accessible teaching or a test of learning gains.
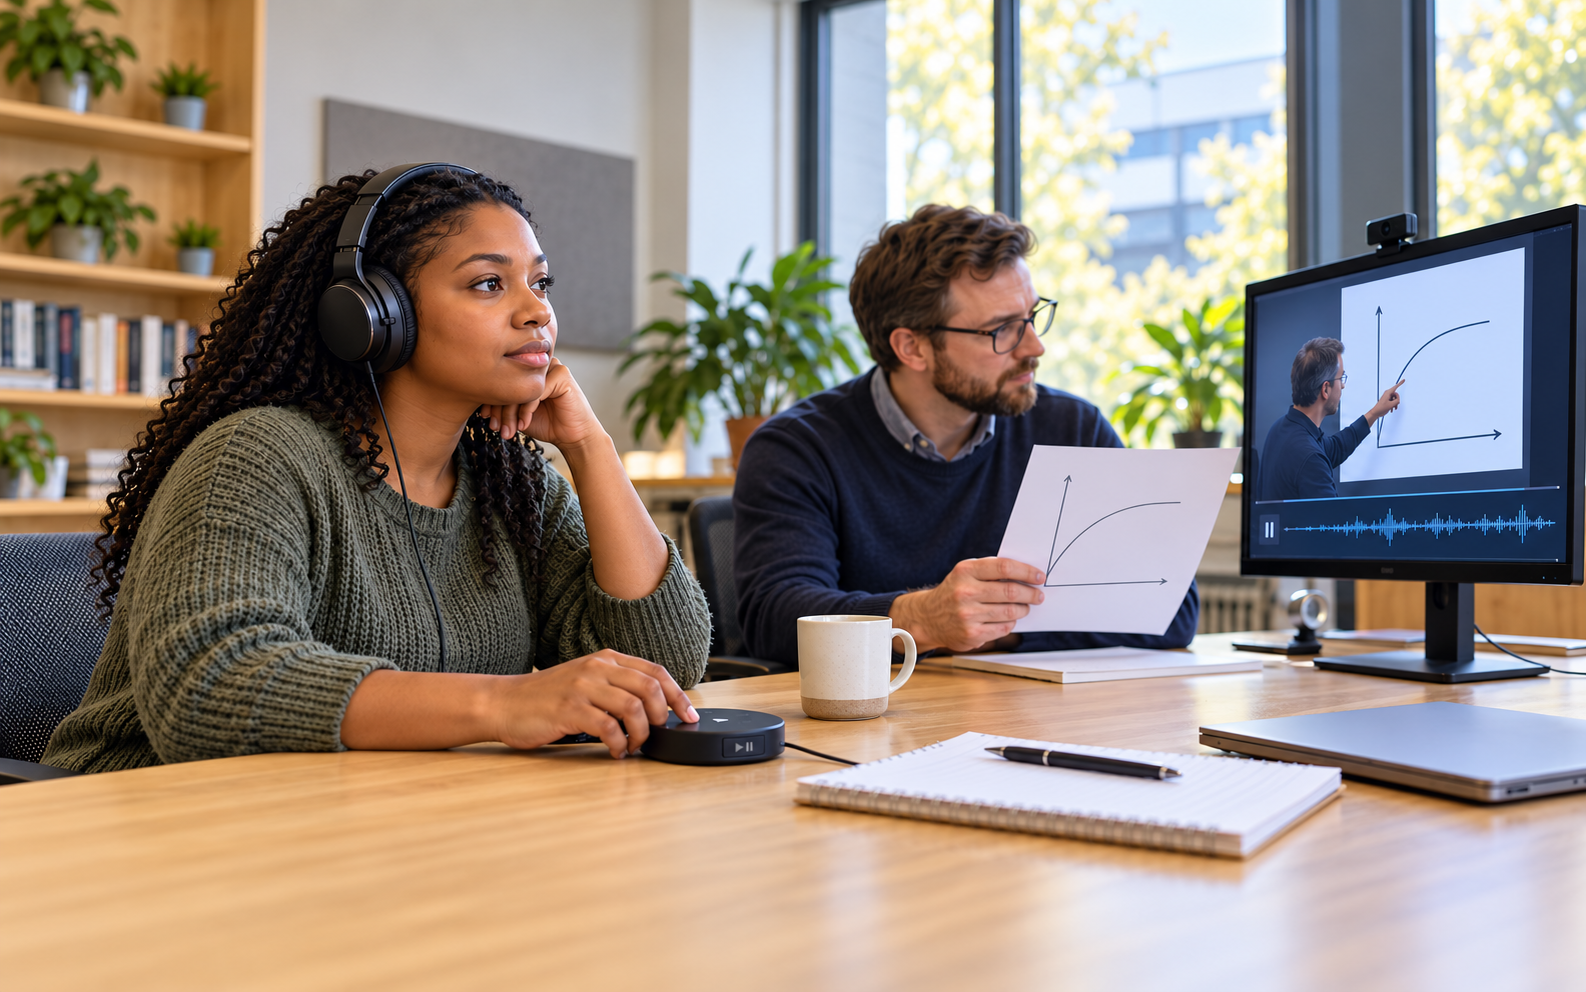
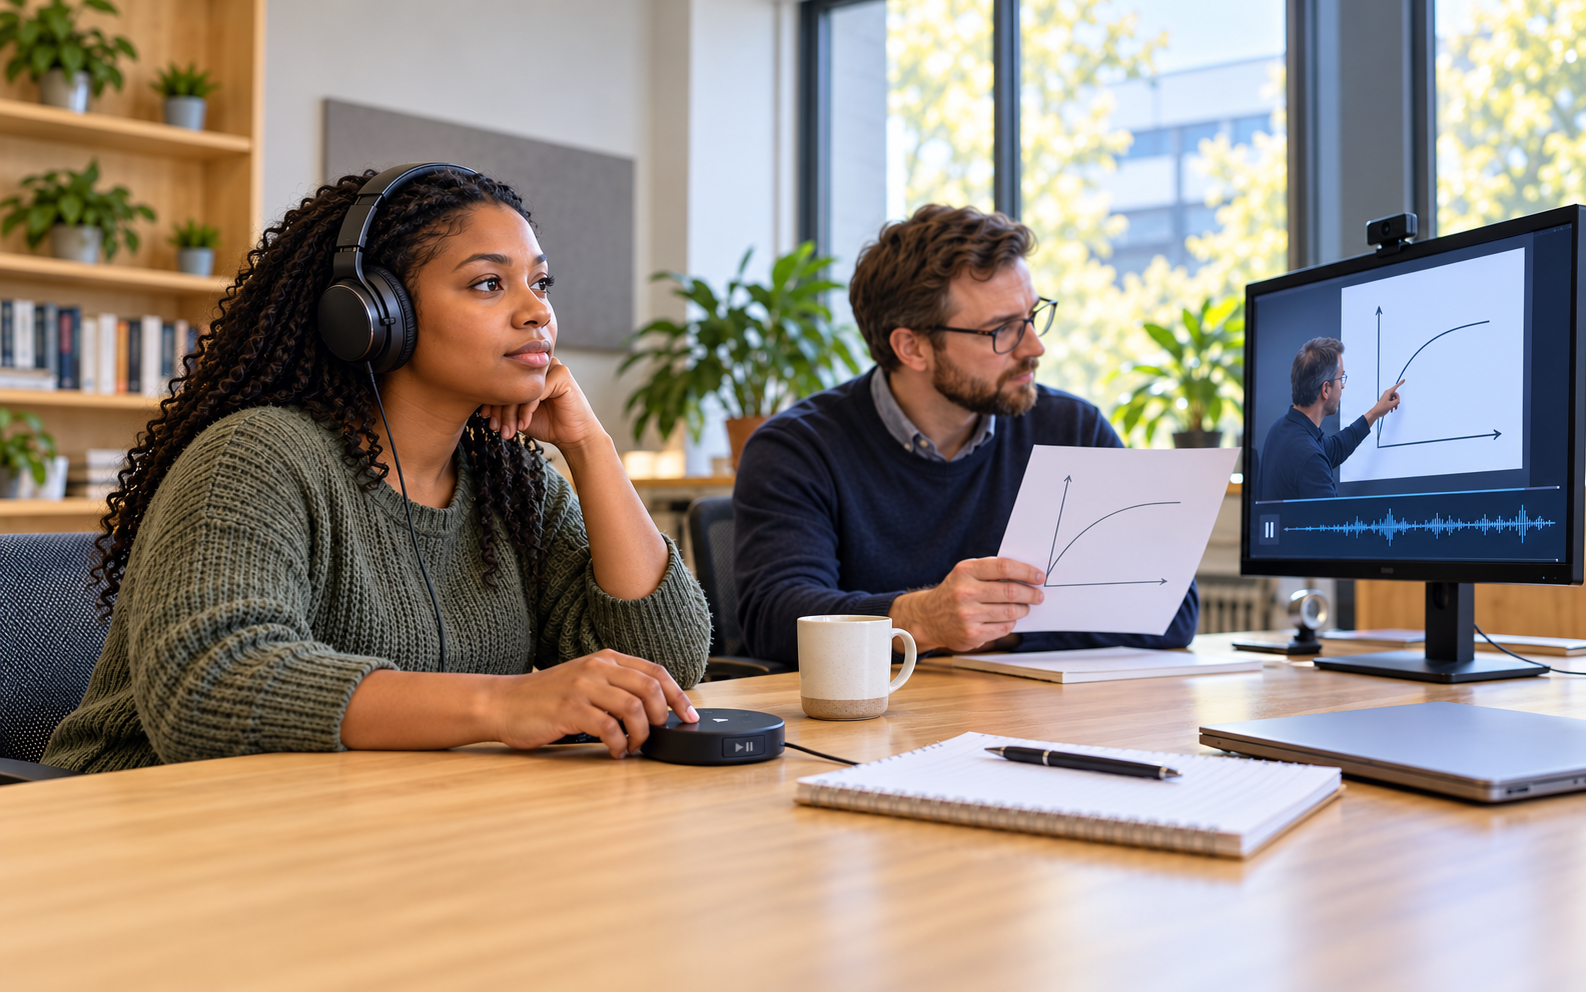
For AIEDHK, an editorial design proposal is to evaluate a description inside the teaching activity where it will be heard. An accessibility team could select a short lecture segment containing a graph, test whether the narration identifies the relevant axes and relationship, and ask listeners what remains unclear. That proposed pilot would examine both factual adequacy and the experience of following the explanation. It should let participants explain their preferences rather than forcing every response into a single quality score.
Consider a lecturer saying that a curve rises more quickly after a threshold. A description might need to name the axes, identify the threshold, and connect the visual change to the spoken claim. Listing every tick mark could be unnecessary for one learner and helpful for another who wants to reconstruct the graph. A player could therefore offer an optional extended description while retaining a concise synchronized version. This is a hypothetical interface idea; the preprint does not establish that such a control improves comprehension.
A local evaluation could separate several questions. Does the description accurately represent the graph? Does it arrive at a usable moment? Can the listener answer the course’s intended question? Does the playback control work comfortably with their assistive technology? These outcomes would provide different evidence, and a high automated score should not collapse them into one conclusion. Testing a second segment with different subject matter would also help identify whether a successful explanation depended on unusually simple visuals.
The broader opportunity is to involve learners in choosing what an educational description must accomplish. Automated checks can help flag missing references or likely repetition, while user evaluation can reveal needs that a rule does not anticipate. Universities considering a pilot could treat the benchmark as a starting resource and document where local requirements differ. The result would be an inspectable design process whose success is assessed in real listening and learning tasks, with individual preferences still visible.