Pedagogical-fit feedback improved 51 of 62 weak AI-tutor responses, but scaffolding gains created trade-offs
Benjamin Barlog, Hudson Craig, Zedong Peng
IEEE 27th International Conference on Information Reuse and Integration for Data Science (IRI 2026)
500 字摘要
Barlog, Craig and Peng ask a sharper question than whether an AI tutor gives a correct answer: is the help appropriate for this learner at this point in a course? Their paper, presented at IEEE IRI 2026 and posted to arXiv on August 5, introduces the Pedagogical Suitability Index, or PSI. The study evaluates ChatGPT, Gemini, Gemma 4 and Qwen 3 in an introductory Python course. Across 30 scenarios, paired standard and deliberately defective student prompts and four models, the authors produced 240 tutor-response evaluations.
PSI combines six equally weighted components: knowledge distance from the learner’s current foundation, prerequisite-order violations, scaffolding density, retention timing, avoidable cognitive load and alignment with the intended Bloom level. The course model included 85 Python concepts and their prerequisites. Scenarios represented two questions for each week of a 15-week course and included learner profiles, common misconceptions and eight prompt-defect categories such as missing context, vague errors and wrong terminology. Two former students rated the scenarios for realism and course fit, although this was a small validation step.
Baseline PSI scores ranged from 0.557 to 0.638. ChatGPT scored highest in this implementation, followed by Qwen 3, Gemma 4 and Gemini, but the spread was modest and did not support a simple closed-versus-open model conclusion. Overall PSI barely changed under defective prompts, declining by 0.002, yet the sub-scores moved in different directions. Missing context reduced knowledge calibration and scaffolding while prerequisite ordering improved, suggesting that a stable composite can hide educationally important trade-offs.
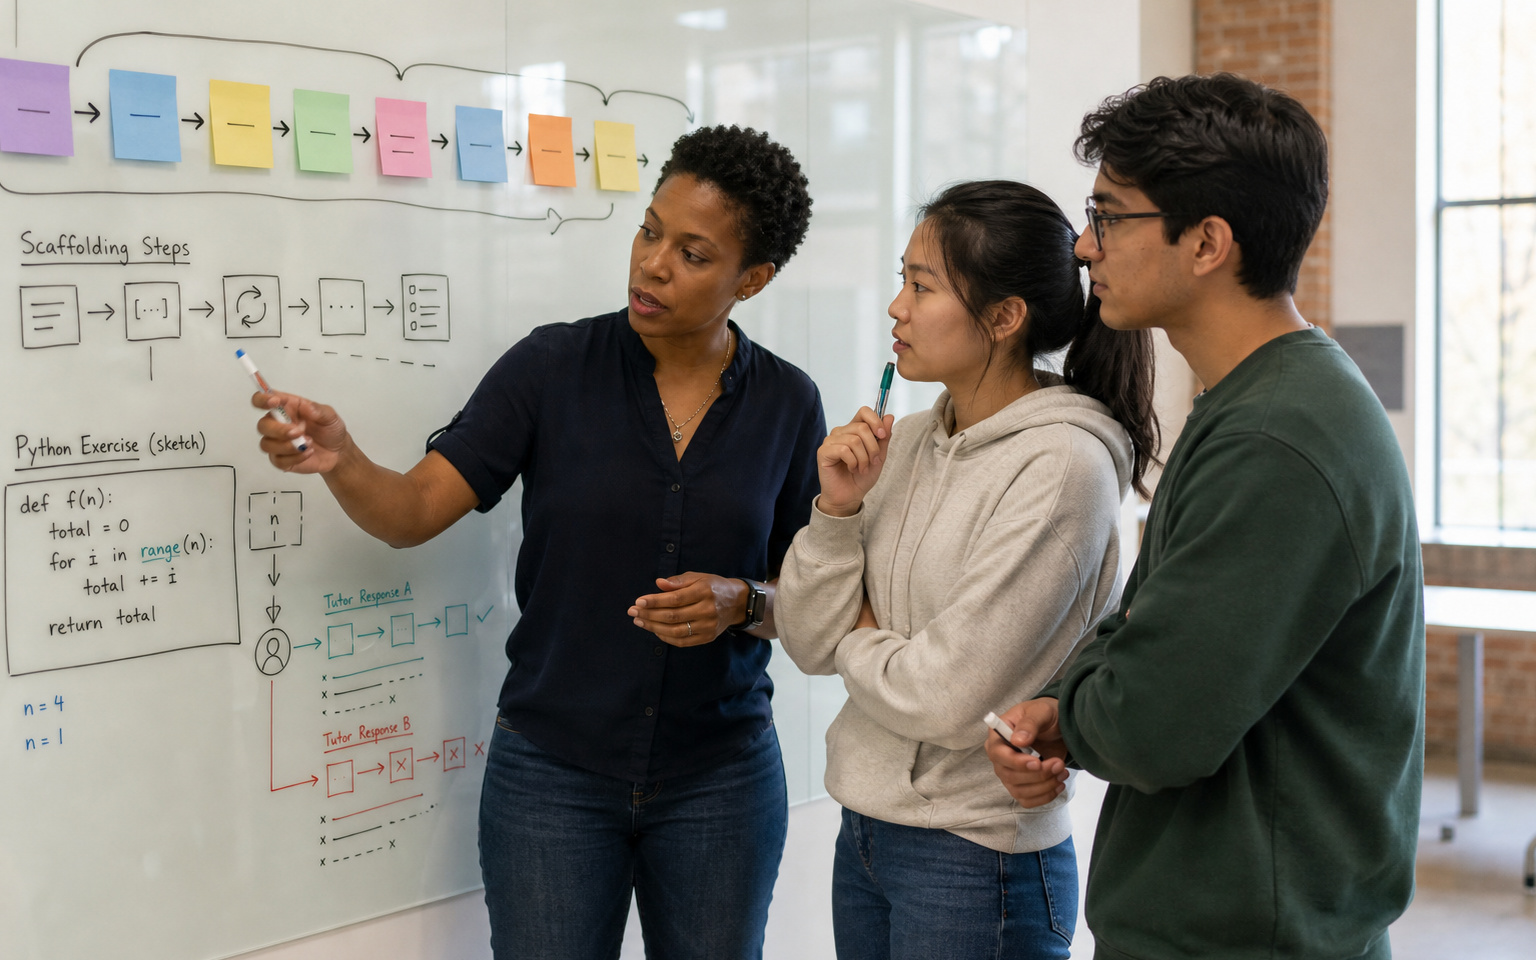
The researchers then selected 62 weak defective-prompt cases for one round of PSI-guided regeneration. The feedback included the original context, the first response, all six scores, a diagnosis and an improvement checklist. Fifty-one of 62 cases improved, or 82.3 percent, and mean PSI rose by 0.049. Scaffolding density produced the largest change, increasing by 0.272 as responses added worked examples, steps and comprehension checks. A single instructor judged 46 of 62 regenerations meaningfully better and 51 of 62 to have resolved the flagged weakness. However, prerequisite-order and Bloom-alignment scores declined on average, so adding visible support did not improve every pedagogical dimension.
The evidence is promising but preliminary. PSI relies on keyword and regular-expression proxies, uses unvalidated equal weights and has two components with little discriminative power in this implementation. It covers one course, 30 scenarios, one model snapshot and no live student learning outcomes; manual review involved one expert and only the selected weak cases. The model names also describe tested product snapshots, not permanent rankings, so later versions should be re-evaluated rather than assumed to preserve the same order. For Hong Kong education, the practical lesson is to evaluate tutor responses against curriculum sequence, learner readiness and intended cognition, then inspect the components rather than trusting one score. A pilot should combine teacher review with authentic student interactions and independent measures of what learners understand and can transfer after the tutor is removed.