Multilevel AI-assisted feedback supported collaborative regulation, with human review built into delivery
Guoqing Lu, Shen Ba, Lan Yang
Education and Information Technologies
500 字摘要
Useful feedback can address whether a group’s answer is correct, how the group worked, and how its members regulate their next steps. Guoqing Lu, Shen Ba, and Lan Yang investigated those design choices in an AI-supported collaborative learning study. Their findings favor attention to several levels of feedback, while challenging the assumption that longer or more elaborate AI comments are automatically more effective. The workflow also retained human review, an important part of what the study actually tested.
The participants were 114 preservice teachers specializing in geoscience at a public university in Northwest China. They took an introductory course on artificial intelligence and its educational applications. The study used a two-by-two design crossing feedback focus with complexity. Task-level feedback concentrated on the work itself; multilevel feedback additionally addressed process and self-regulation. Simple feedback identified strengths and weaknesses, while elaborate feedback included more detailed evaluation and concrete improvement suggestions. All conditions also received common basic oral feedback from the teacher.
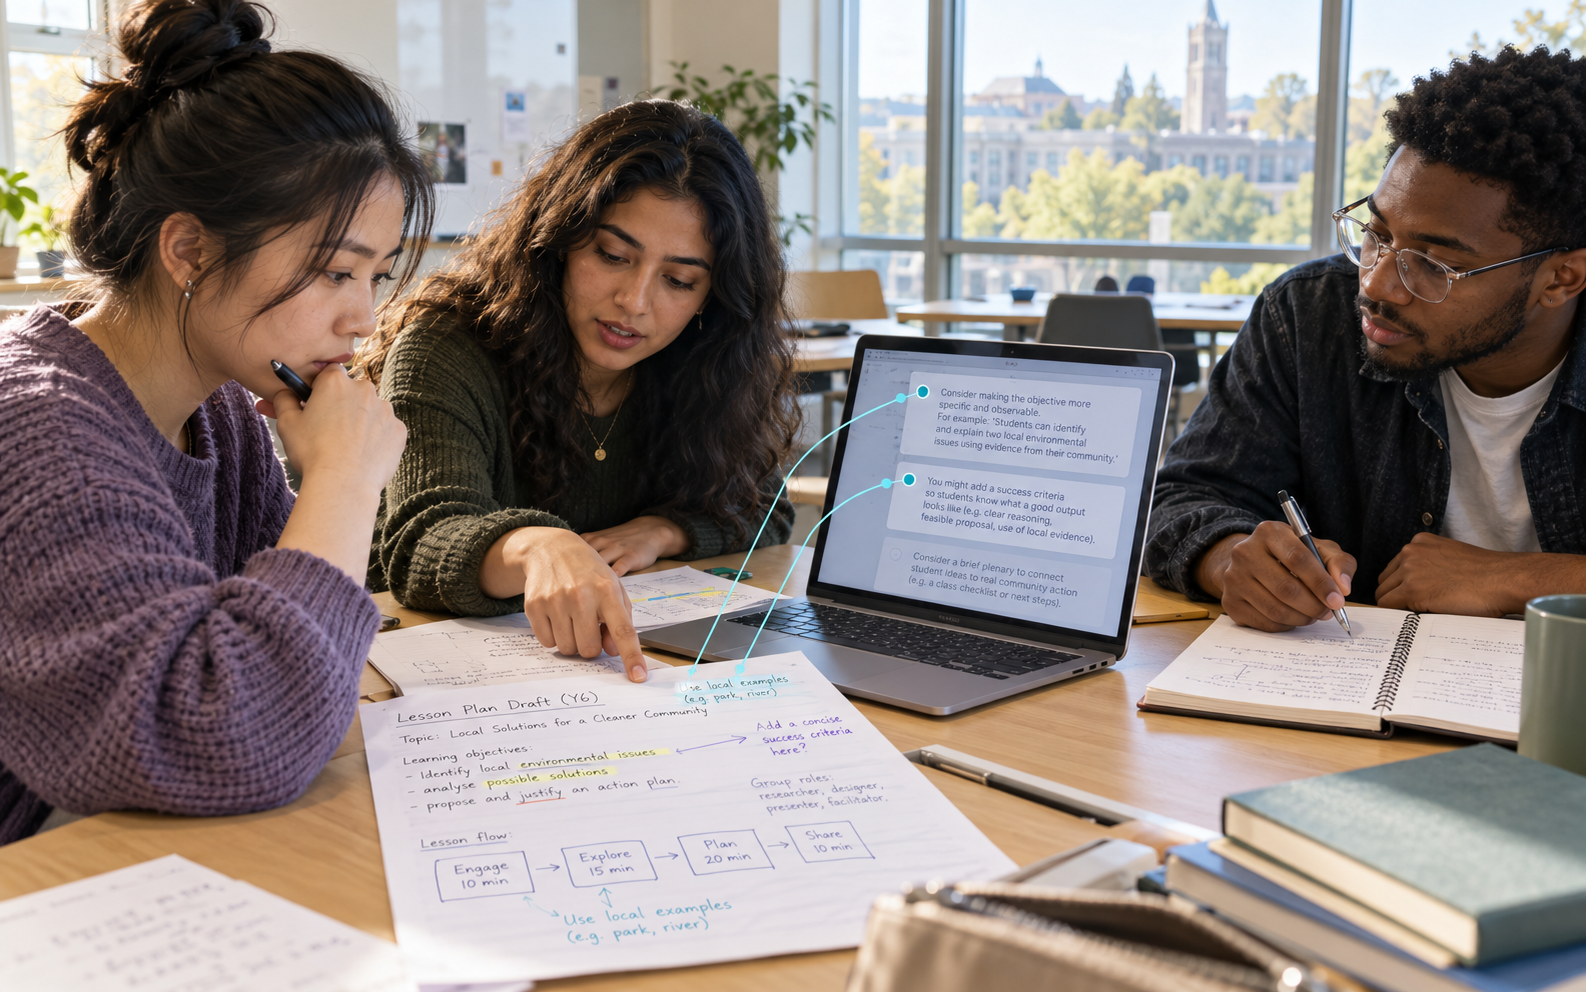
Students worked collaboratively on the educational uses and risks of AI, producing mind maps and presenting group solutions. At designated stages, a teaching assistant used GPT-4 to generate feedback from group task sheets and discussion information. The assistant checked responses against the assigned feedback protocol, corrected logical or content errors, and refined prompts when necessary. Students therefore did not directly converse with the model. The tested intervention combined model generation, structured prompts, human checking, and an established classroom activity.
Results differed by outcome. Multilevel conditions showed stronger behavioral participation on certain comparisons and an advantage in reported group-shared metacognition. Feedback complexity alone did not have a significant main effect on that measure, although focus and complexity interacted. Several group-product measures also favored multilevel feedback. The multilevel-elaborate condition exceeded the task-simple condition on the course achievement comparison. These patterns suggest that what the feedback addresses can matter more than simply how much text it contains.
The null results are equally relevant. The conditions did not significantly differ in perceived cognitive or emotional engagement, individual shared metacognition, or post-course AI literacy. AI literacy improved across the course, but every condition experienced the same broader instruction; that change cannot isolate the effect of AI feedback. Likewise, this was a comparison between feedback designs, not a trial against entirely human feedback or a no-feedback baseline. The study does not establish the independent contribution of the language model within the supervised package.
The authors describe the research as an exploratory quasi-experiment and acknowledge its distinctive preservice-teacher sample. Much of the engagement and metacognitive evidence relied on self-report, and the intervention did not test direct student interaction with an AI system. Group artifact quality and course scores add useful perspectives, but they do not remove every measurement or generalizability limitation. A school adopting the approach would still need to test whether its own learners understand and act on the feedback as intended.
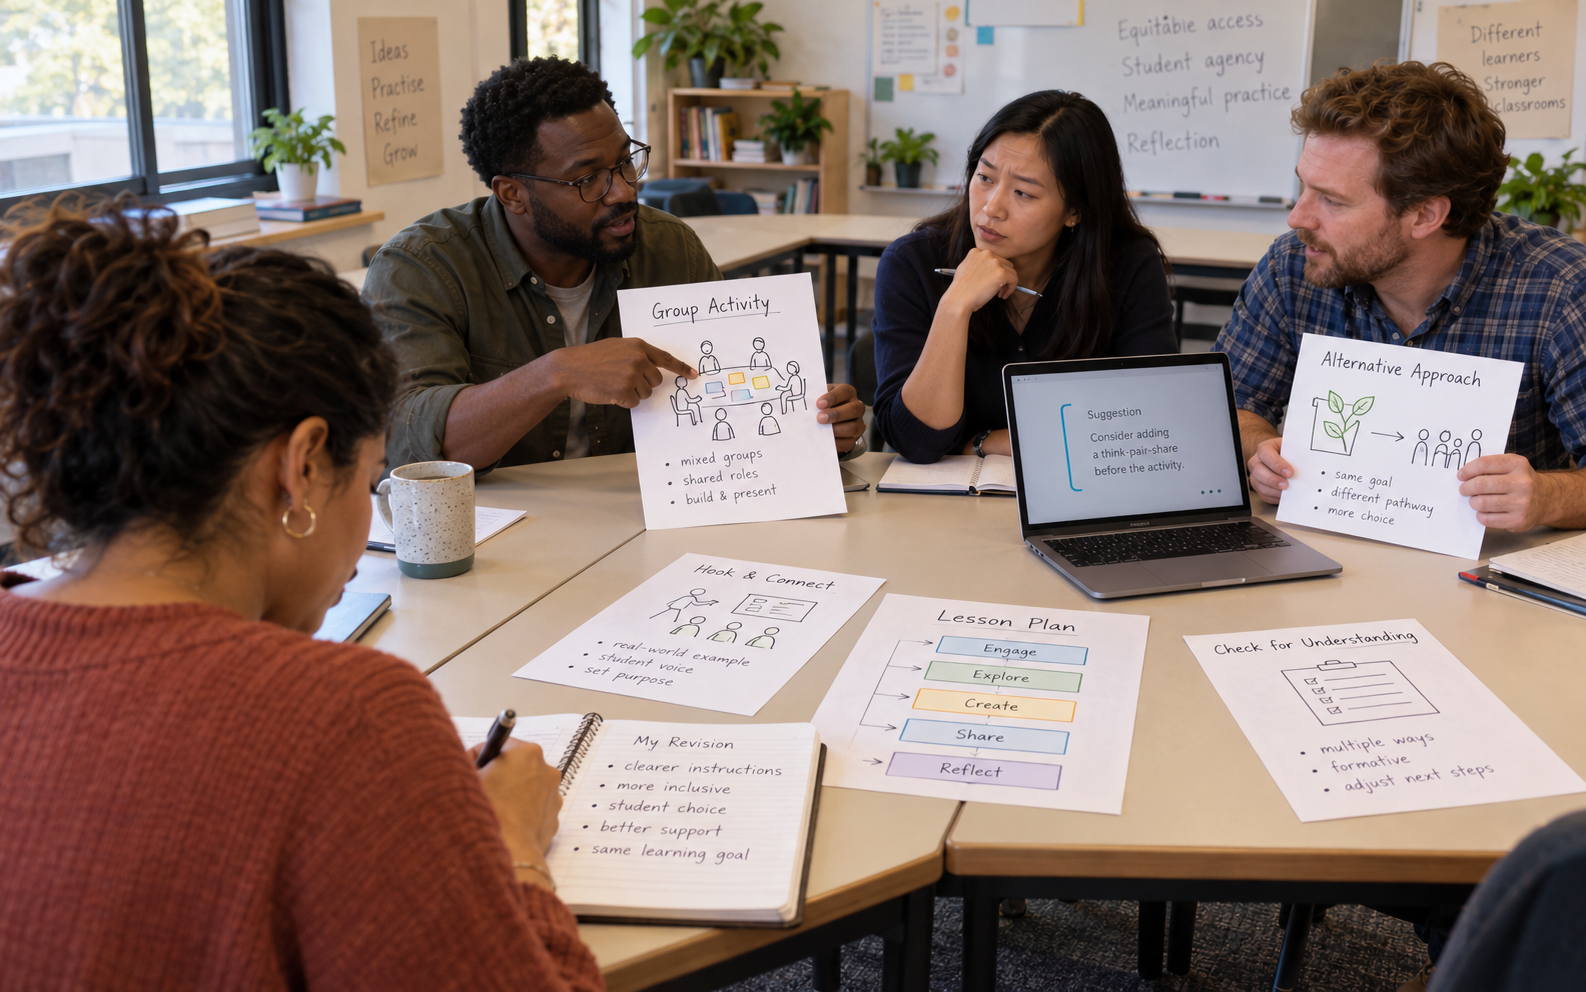
For AIEDHK, the design implication is concrete: a feedback tool can ask about the group’s plan, division of work, and next check alongside the correctness of its answer. Teachers can retain responsibility for verifying that advice fits the activity. Any local evaluation should measure the response to feedback and independent achievement separately. That would test the pedagogical workflow represented in this study while avoiding an unsupported claim that automated feedback alone produces better collaboration.