Product news: Claude adds OpenTelemetry export, giving education developers a clearer view of AI requests
Anthropic
AI Product and Learning Report
500 字摘要
Anthropic's October 14, 2026 release notes announce beta OpenTelemetry export for Claude API requests and Managed Agents sessions. Its documentation describes traces that can include model requests and tool activity, with timing and token information. SDK and API tracing cover different parts of the workflow and can be combined. This is a developer capability: it does not automatically turn the Claude interface into a classroom assessment system or provide a validated measure of learning.
The documentation distinguishes a default metadata mode from an optional mode containing prompts and responses. Exported information is stored under the receiving monitoring service's access and retention settings. An education team should therefore decide what a diagnostic question actually requires before expanding collection. A failed request may be explainable without retaining a student's entire conversation. Conversely, a neat sequence of successful software operations says little about whether the student understood the answer that appeared on screen.
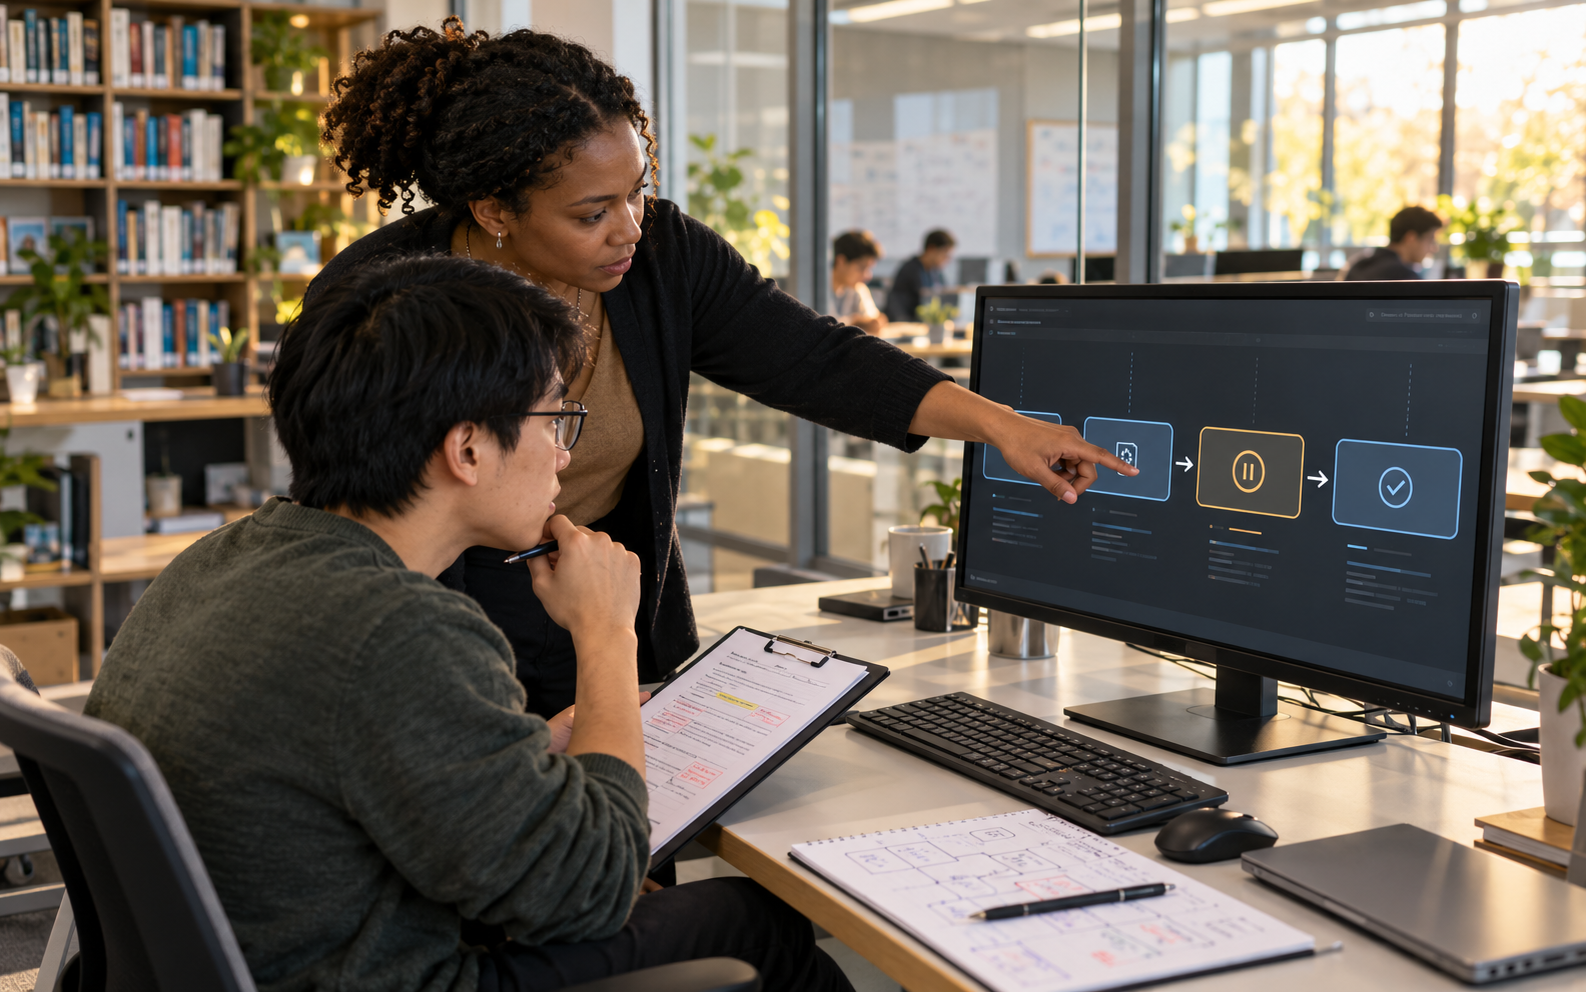
Consider a proposed pilot for a course assistant that answers questions from teacher-approved readings. A student reports that the assistant cited the wrong chapter. Developers could inspect the relevant technical sequence, while the teacher compares the displayed answer with the assigned source. The learner then explains which claim seemed convincing and how they checked it. These are three different objects of inquiry: application behaviour, answer quality, and the student's interpretation. Keeping them separate makes the investigation more useful than treating a single activity record as an explanation of everything that happened.
A debugging workshop could begin with a deliberately prepared example using fictional student data. Learners predict which source the assistant should retrieve and which error would change the result. After running the example, they compare that prediction with the available record and identify any missing information. The task should reward a defensible explanation of a discrepancy, including uncertainty, rather than simply counting tool calls. This is an instructional proposal for using process records; the release announcement does not report a classroom trial of that activity.
For institutional evaluation, teams could define a small set of concrete questions before instrumentation begins. Can a reported failure be located? Can someone explain which material informed the response? Can unnecessary content be excluded from the diagnostic record? Reviewers should also examine cases where the application behaves as configured but still produces an unsuitable explanation. Technical success and instructional suitability need separate criteria, and a successful demonstration should not be presented as proof that every learner will receive appropriate support.
The change gives education developers another way to investigate AI workflows, while leaving the educational interpretation to people. A useful local pilot would document the diagnostic task, the information collected, the decisions made from it, and the questions it could not answer. Students' own work and explanations can provide complementary evidence without being reduced to system events. The immediate outcome to seek is a more accountable investigation of application behaviour; any claim about improved understanding would require a study designed to measure that outcome directly.