Blending guidance with reflection prompted more revisions than reflective AI feedback alone
Omar Alsaiari, Nilufar Baghaei, Jason M. Lodge, Omid Noroozi, Dragan Gašević, Marie Boden, Hassan Khosravi
Computers and Education: Artificial Intelligence
Резюме на 500 слов
Omar Alsaiari and colleagues compared three AI feedback designs during a 12-week design and programming course involving 329 students. Learners created resources such as questions and explanatory notes in RiPPLE. The platform allocated students to directive, metacognitive, or hybrid conditions on first login. Feedback combined common summary and strengths sections with different suggestions: explicit guidance, reflective questions, or both.
Content-revision rates were 21.1% for directive, 12.1% for metacognitive, and 27.5% for hybrid feedback, calculated over analyzed submission events. Both directive and hybrid conditions exceeded the metacognitive condition in adjusted comparisons. Hybrid did not significantly exceed directive feedback. Engagement time, confidence, and resource quality showed no statistically significant condition effects.
The authors identify a single course, high starting performance, behavioral proxies, and absent transfer evidence as limitations. Their analysis did not distinguish superficial edits from deeper changes. The study therefore supports a difference in observable revision behavior, without establishing that hybrid feedback produced superior understanding. A useful next question is what kinds of revision an educational activity should invite, and how a teacher could recognize them.
For AIEDHK, one editorial proposal is to let students author a practice question, receive a short correction plus a reasoning prompt, and then explain the revision to a peer. The correction could identify an ambiguous answer option; the prompt could ask why a learner with a particular misconception might select it. This combination is a suggested classroom design, not an intervention whose benefits were demonstrated by the paper. It would make the intended thinking task explicit before the teacher interprets a higher revision count.
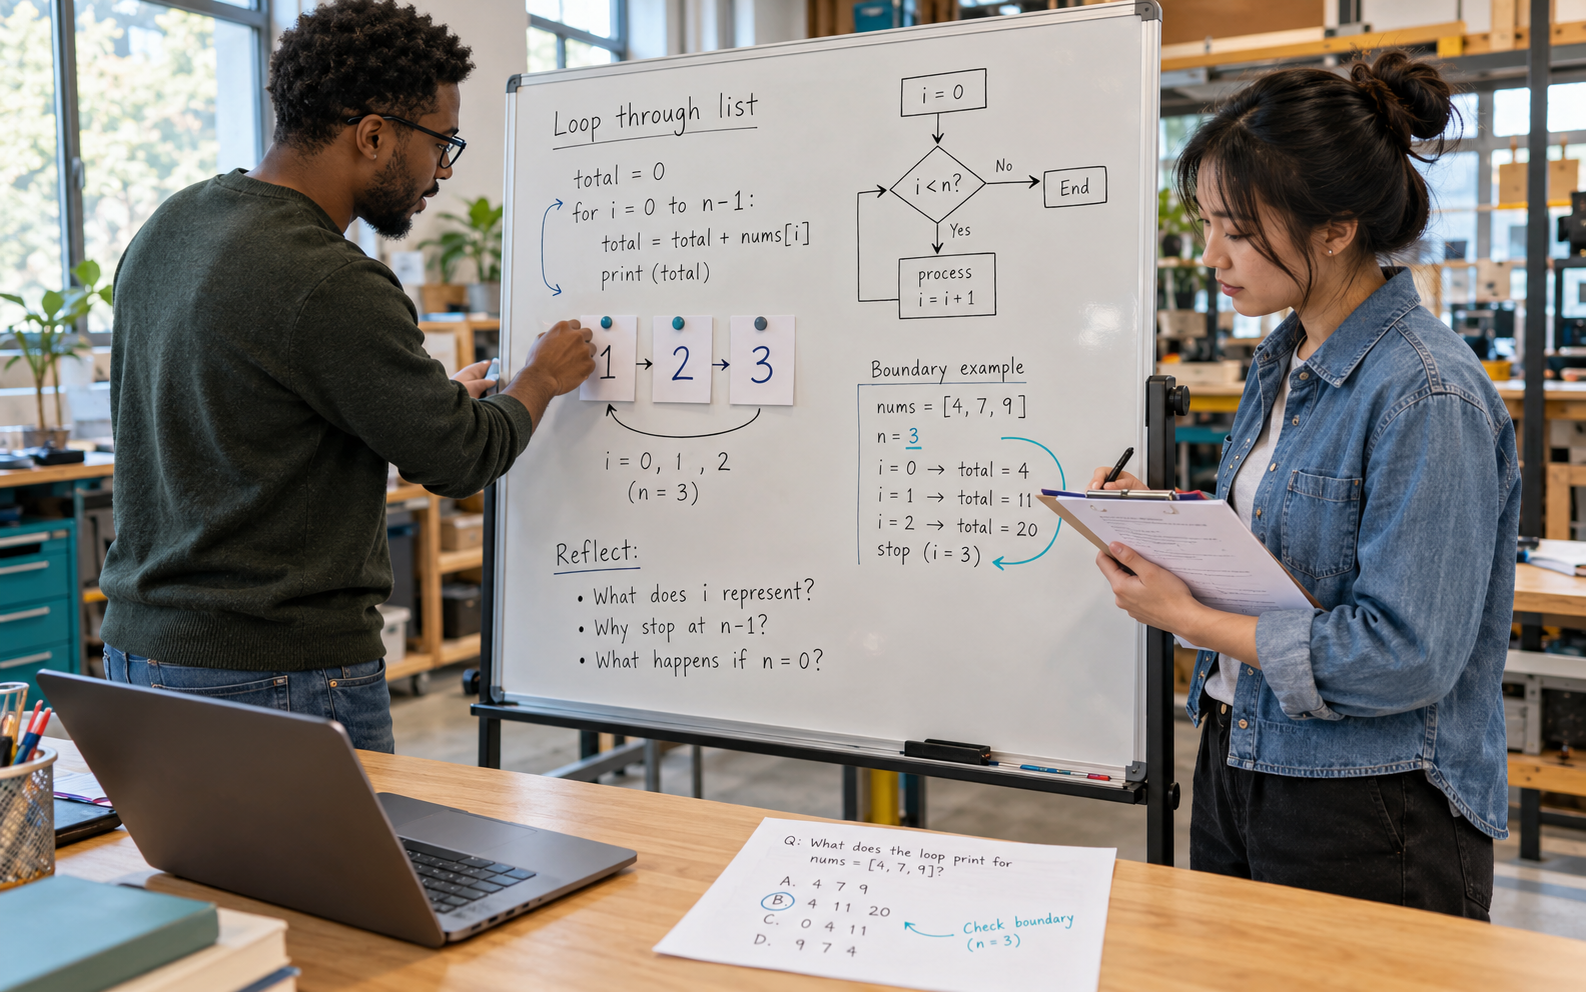
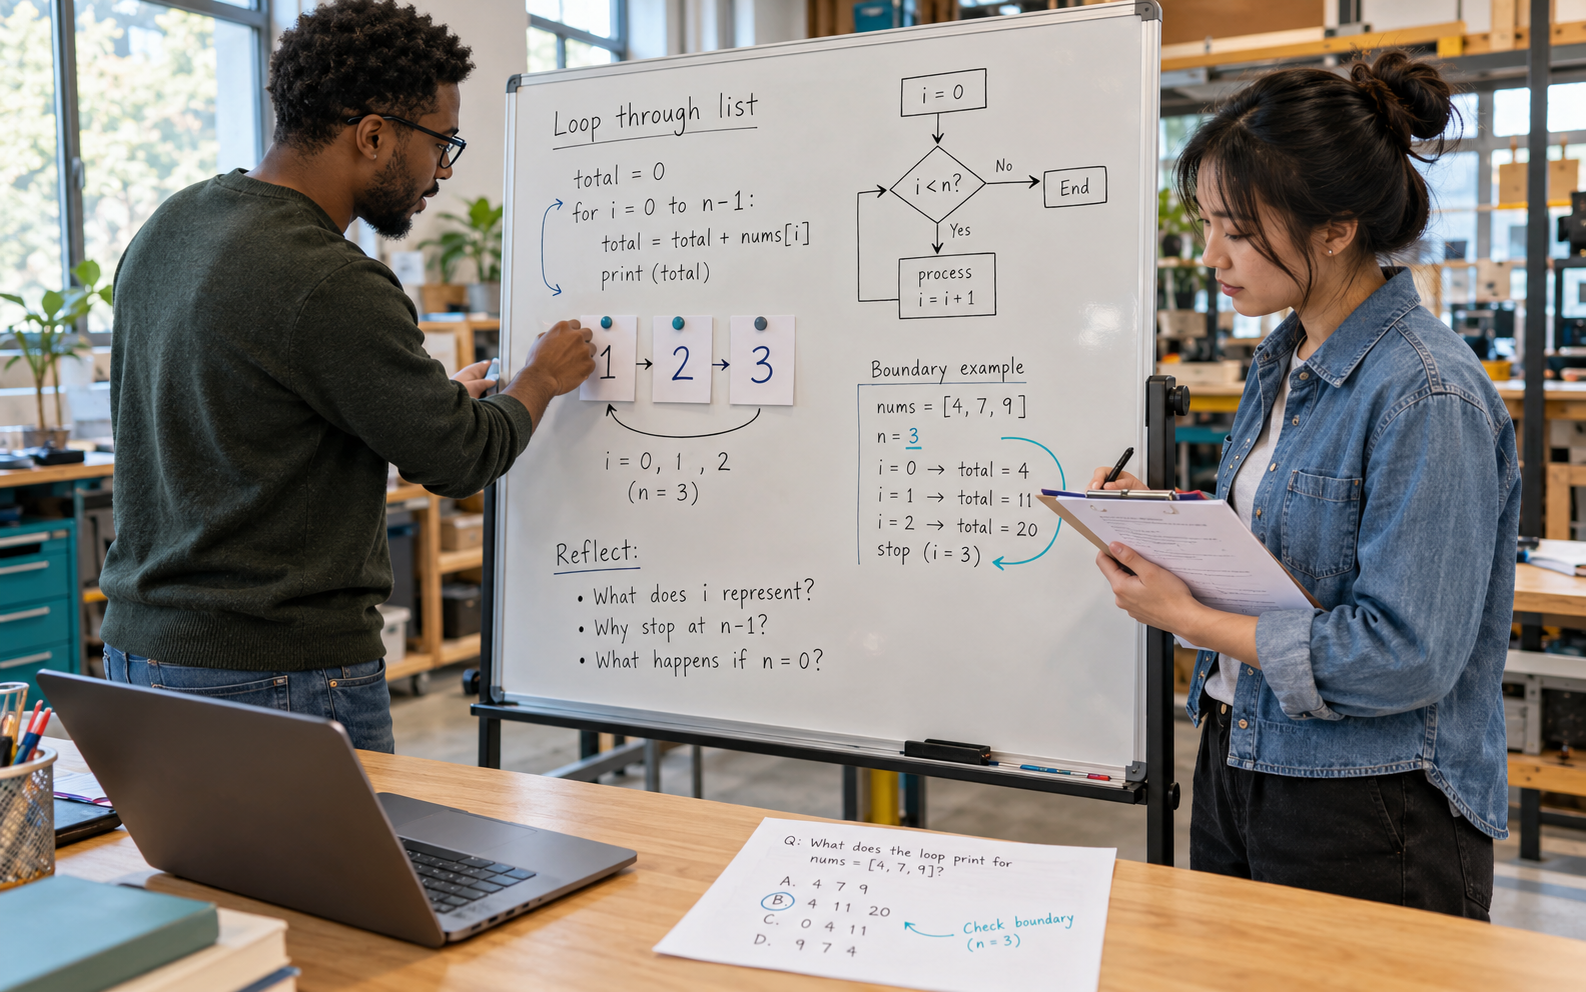
Consider a beginner programming question about a loop that stops too early. A directive comment might point to the boundary condition. A reflective question might ask the author to predict what happens when the input contains one item. Students could trace that case, revise their explanation, and add a contrasting case with no items. The teacher would then have three artifacts to inspect: the original question, the test reasoning, and the revision. Counting keystrokes or reopened drafts would not reveal whether the author understood the boundary.
A small pilot could score revision depth using a few concrete criteria: whether the error was correctly diagnosed, whether the explanation now matches the code, and whether the new example discriminates between plausible answers. The same students could later solve a related question without feedback. That follow-up would address a different outcome from resource quality, while the peer explanation would help identify copied reasoning. Teachers would also need to allow a justified decision to keep an already sound question unchanged.
For developers, a useful evaluation dashboard could place revision frequency beside examples of what changed and a measure of independent performance. These indicators should remain separate because a system can stimulate activity without improving understanding. A more reflective message may also require time that is invisible in click data. The practical opportunity is to compare feedback designs against the learning task they are meant to support, then investigate the decisions behind both action and deliberate non-action.