Translation students welcomed AI feedback but still needed help turning broad advice into revisions
Simin Xu, Yanfang Su, Kanglong Liu
Education and Information Technologies
Resumo de 500 palavras
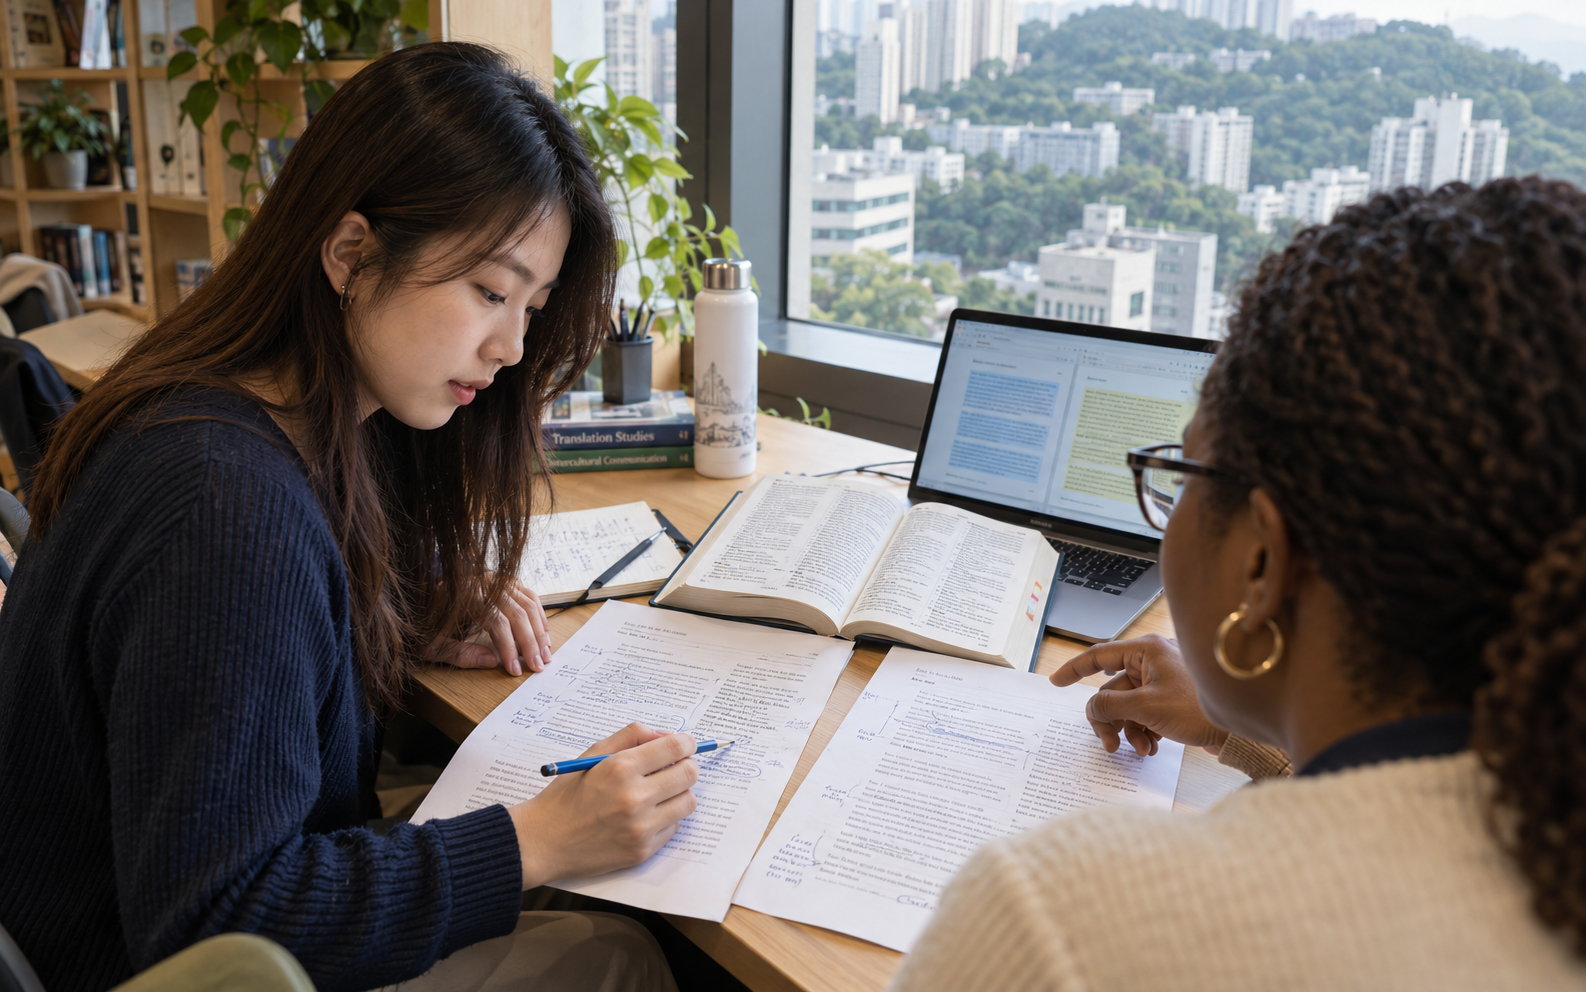
AI feedback can feel clear and encouraging while remaining difficult to use. A study by Simin Xu, Yanfang Su, and Kanglong Liu examines that gap through the revision practices of translation students at a Hong Kong university. Rather than measuring whether participants liked a chatbot in general, the researchers connected their reactions to draft changes and screen recordings. The result is a detailed account of how feedback can stimulate effort without automatically resolving problems in meaning and translation quality.
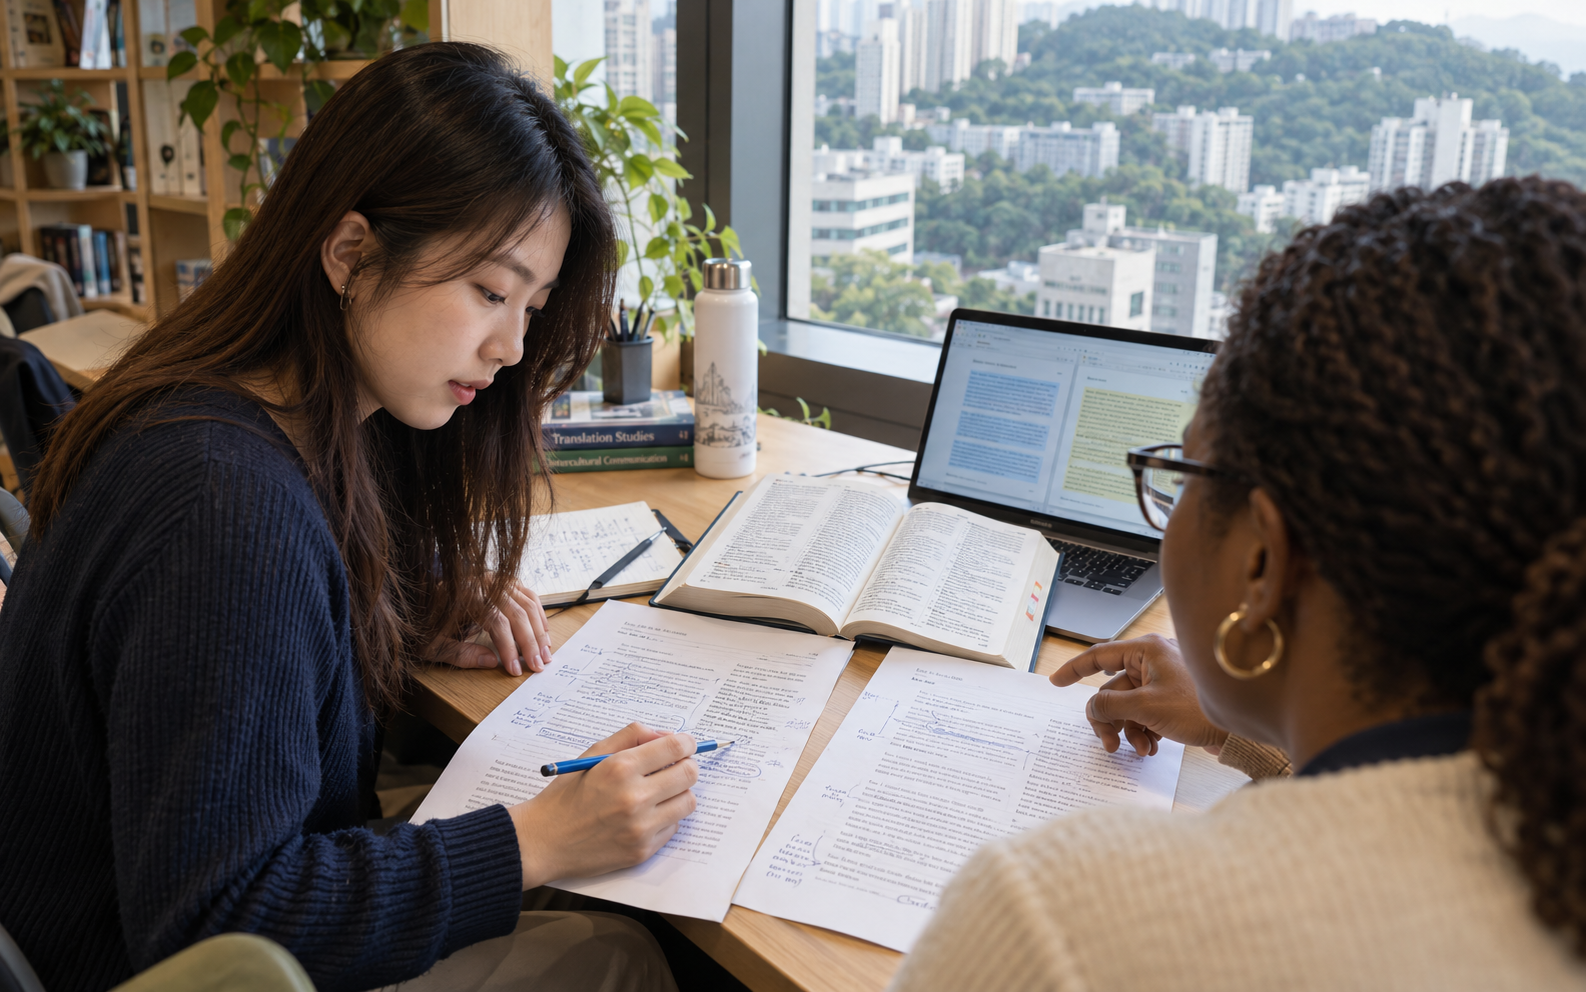
The participants were 29 students enrolled in a Master of Translating and Interpreting programme. They completed an online activity using a teaching platform that integrated ChatGPT. A built-in prompt drew on a translation assessment rubric, and two experienced teachers had reviewed the platform’s feedback before data collection. Students translated a Chinese political-news text into English, received the first feedback output generated for their draft, and then revised their work. Their initial translation was completed without machine translation or online resources under screen-sharing observation.
The researchers assembled original and revised translations, model feedback, revision recordings, a post-task questionnaire, and interviews with four purposively selected students. Analysis separated cognitive engagement, emotional and attitudinal engagement, and observable revision behavior. Feedback itself typically combined a reference translation, comments, and a grade. That combination matters because students might respond to a reassuring score, imitate a reference phrase, or interpret a diagnostic comment in quite different ways.
Participants generally reported understanding the feedback and investing effort in revision. Interviews nevertheless revealed confusion when advice referred broadly to coherence or clarity without identifying a specific problem. Students often checked disputed suggestions against other resources and made changes the chatbot had not proposed. They appreciated lexical and sentence-level assistance, but some considered particular substitutions unnecessary. Positive comments could increase confidence, while excessive praise became frustrating when learners wanted concrete criticism that would help them improve.
Observed behavior also complicated a simple acceptance story. The researchers documented revisions connected to AI feedback alongside self-initiated changes. Students did not adopt every suggestion, and the relationship between reported ease of understanding and actual uptake was uneven. These findings concern how learners processed feedback in this task. They do not show that a high uptake rate necessarily produced a better translation, nor that a positive experience represented durable growth in independent translation ability.
The paper identifies limitations involving prompt quality, the use of ChatGPT 3.5, a restricted sample, and the need for broader investigation. The design also lacks a parallel teacher-feedback or no-feedback group that could isolate a comparative learning advantage. A single translation and revision episode cannot establish how students would handle unfamiliar genres later without assistance. The strongest inference is about the demands of feedback engagement, not a general ranking of AI and human translation teaching.
For AIEDHK, the practical lesson is to teach the response to feedback as explicitly as the request for feedback. A tutor could ask students to locate the passage at issue, explain the intended meaning, and justify a proposed revision before accepting it. Comparing an AI suggestion with a dictionary, corpus, or teacher explanation would make disagreement productive. These are pedagogical implications for local design: helpful feedback should support a learner’s judgment, while confidence and fluent wording remain only part of the evidence.