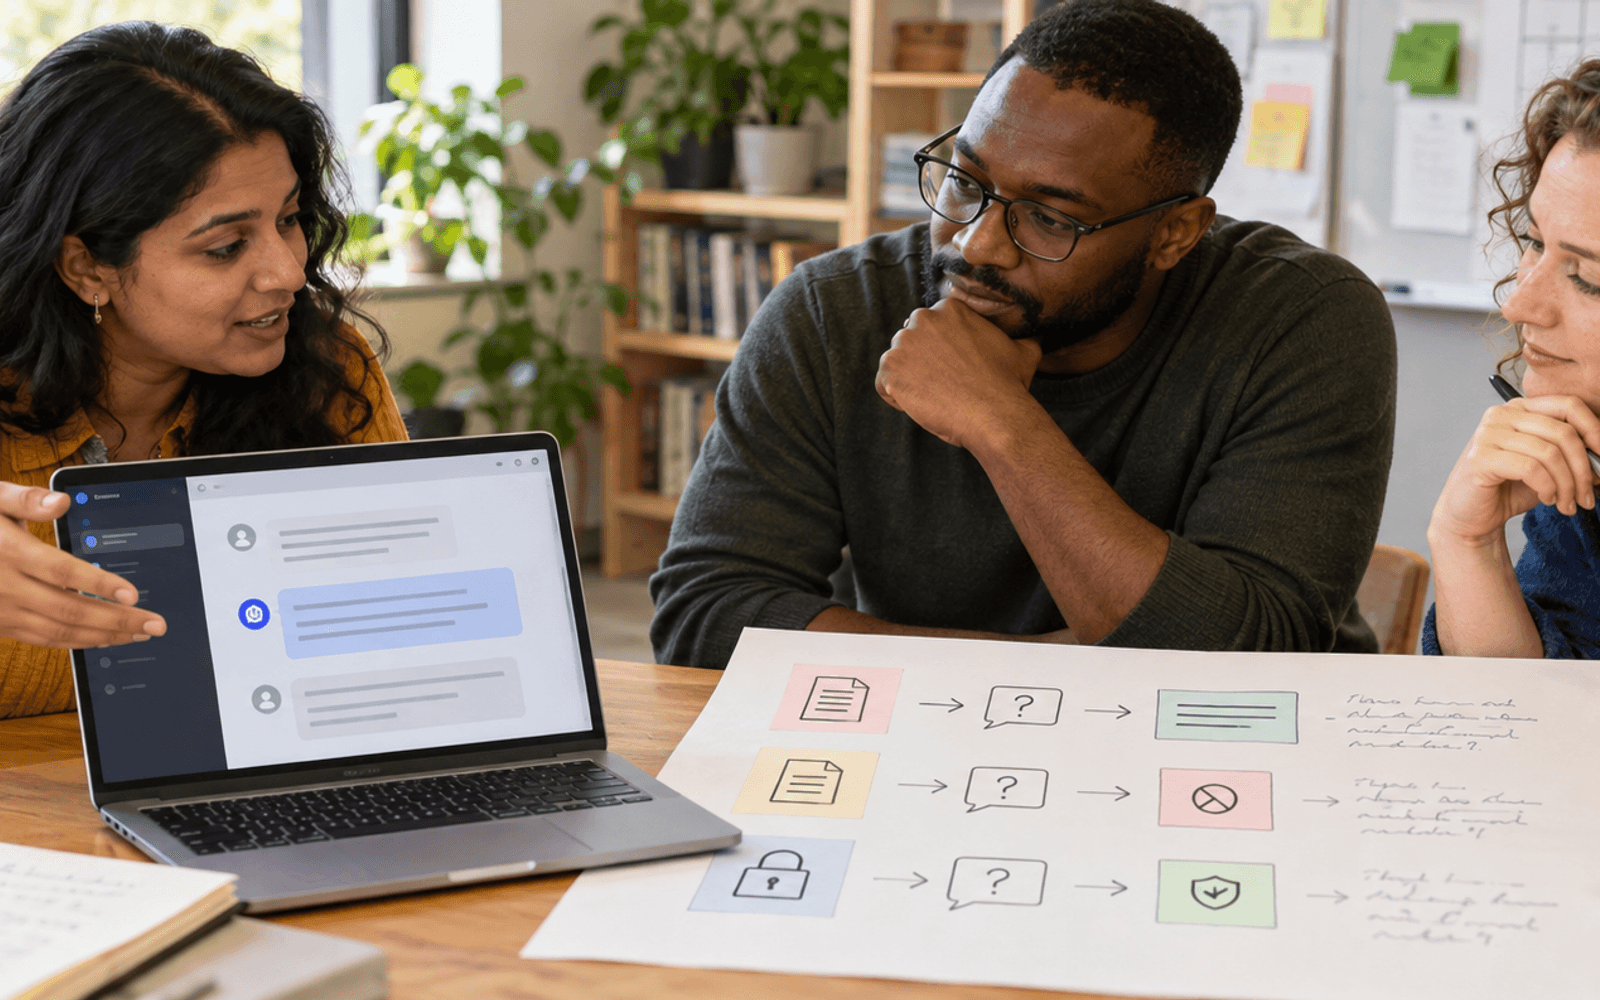
Red-Teaming Educational AI
Red-teaming tests how an educational AI workflow fails under challenging conditions. Useful findings are bounded, reproducible and tied to concrete consequences, fixes and regression checks.
Fontes
Resumo completo
Red-teaming educational AI is an organized attempt to discover how a system might fail under challenging, unexpected, or adversarial conditions. The activity starts from a defined use and plausible harm. A tutoring assistant, a grading tool, and an administrative chatbot have different failure possibilities. Testing should examine the complete workflow, including retrieved material, tool permissions, user interfaces, and human review, because a model's isolated response may not reveal the eventual consequence.
A useful test plan specifies who may interact with the system, what information and actions they can access, and which boundaries matter. Cases might examine whether a tutor reveals another learner's data, follows instructions embedded in an untrusted document, supplies an incorrect explanation with false confidence, or mishandles a request for accessible support. The aim is to reveal a reproducible failure mechanism rather than collect sensational screenshots.
Consider a school assistant that answers questions from an approved course folder. In a controlled test environment, evaluators add a fictional document containing both legitimate course information and conflicting instructions directed at the assistant. They check whether the application treats the document as evidence or allows it to alter its operating rules. Synthetic names and records keep the test from exposing real student information. The educational failure is defined beforehand: unauthorized disclosure or a misleading answer attributed to course policy.
Researchers have explored using language models to generate challenging test inputs, as in work on red-teaming language models with language models. Automated generation can broaden the search, but the resulting cases still need human interpretation. A model may produce implausible scenarios or miss culturally and contextually important risks. Educators, accessibility specialists, and people familiar with the actual learning setting contribute knowledge that general automated tests may lack.
For each finding, record the system version, relevant configuration, minimal test case, observed behavior, expected behavior, and possible consequence. Distinguish a repeatable issue from a one-off result while retaining uncertainty where outputs vary. Prioritize by severity, likelihood, exposure, and available remedies. Fixes should be checked against the original case and related variations, then tested for unintended effects on ordinary educational use, including unnecessary refusals or lost accessibility.
Red-teaming requires authorization and a bounded environment. Set limits on data, tools, external actions, and what testers may attempt. Provide a route for stopping a test and handling sensitive findings. Protect participants from unnecessary exposure to disturbing material, and avoid using real learners as unwitting test subjects. These arrangements make the evidence interpretable as well as keeping the exercise proportionate to the institutional purpose.
A clean test run is evidence about the cases attempted, not proof that the system is safe. Coverage changes when models, prompts, tools, content or user populations change. NIST's generative AI risk guidance places evaluation within ongoing risk management rather than a single certification moment. Schools should retain a route for reporting real incidents and revisiting earlier assumptions. Red-teaming is valuable when discovered failures lead to concrete changes and honest limits on the system's use.


