Loss Functions and Learning Objectives
How a loss function defines what a model is rewarded for improving, and why that mathematical objective may differ from the learning outcome educators value.
Fontes
Resumo completo
A loss function assigns a numerical penalty to a model's prediction. Training then adjusts parameters to reduce that penalty across examples. The choice of loss shapes which errors matter most and what the system is encouraged to learn. An educational learning objective, such as explaining a concept independently, is a different kind of objective. The two can be connected, but they should never be assumed equivalent merely because both use the word learning.
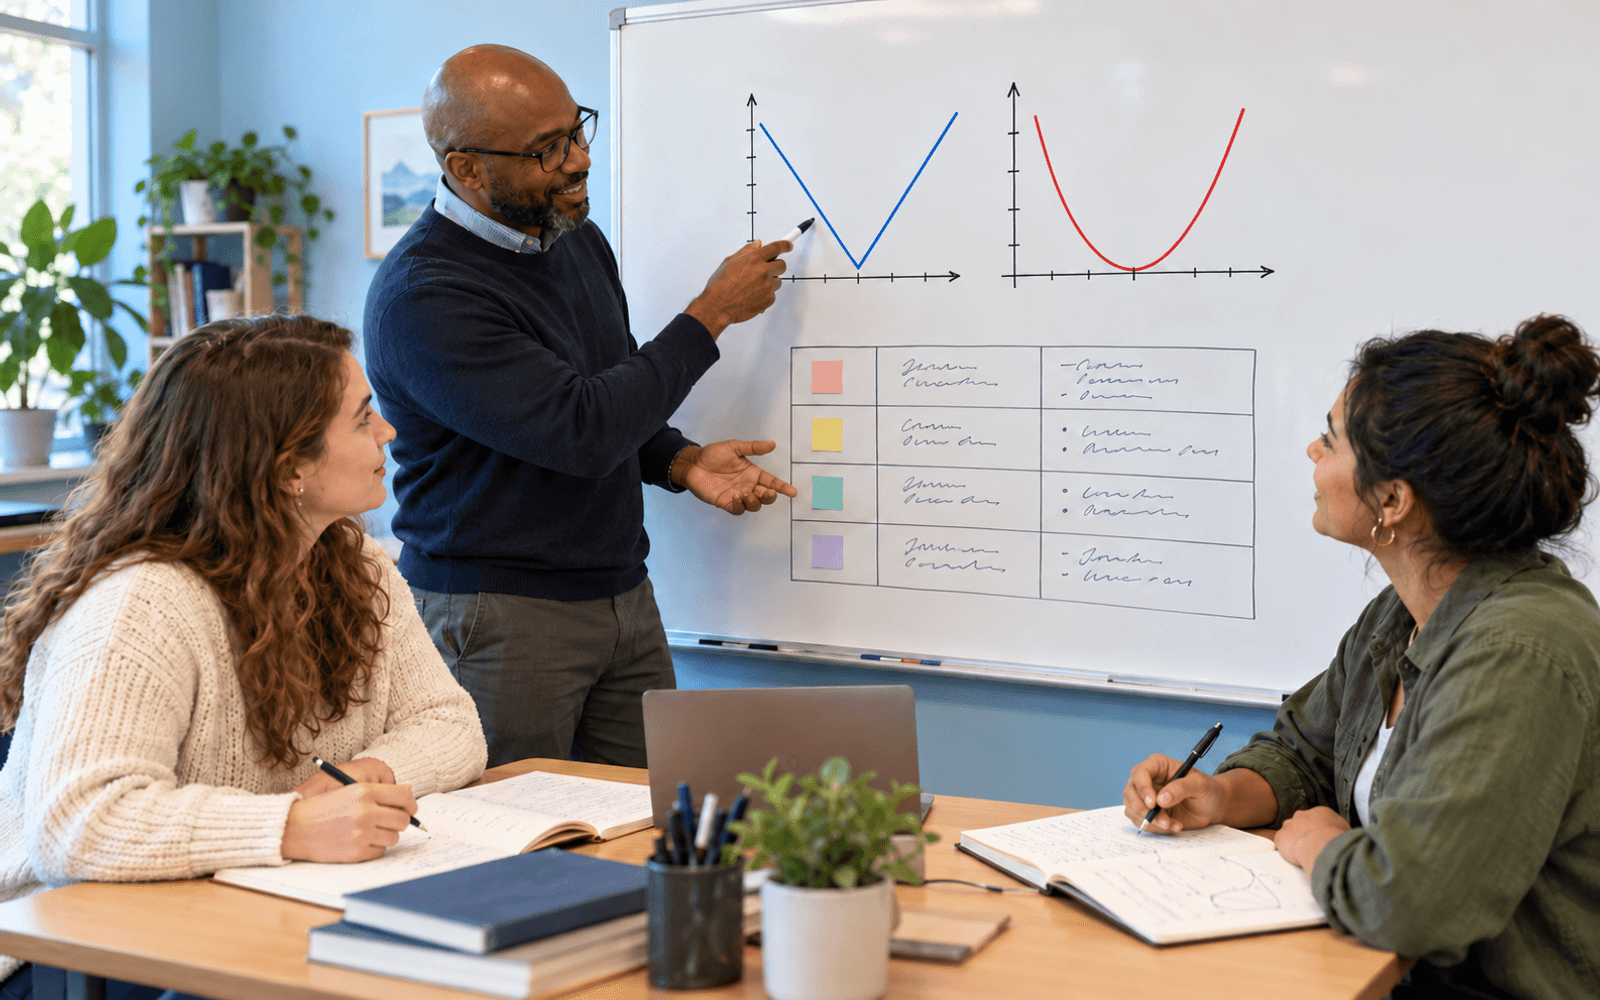
For numerical predictions, absolute error measures the size of a mistake, while squared error penalizes large mistakes more strongly. If two predictions miss by two and ten units, their absolute errors are two and ten, but their squared errors are four and one hundred. This difference can change the fitted model. Neither choice is automatically correct: the decision depends on the meaning of the units, the reliability of unusual observations, and the consequences of large errors.
For classification, cross-entropy penalizes a model for assigning low probability to the observed class. A confidently wrong prediction can receive a much larger penalty than a cautious one. Weighted losses can emphasize selected classes or cases, while additional penalty terms can discourage overly complex solutions. These are mathematical design choices. They do not resolve whether the reference labels are valid, whether some cases deserve greater weight, or whether optimizing the measure improves the actual educational service.
Imagine a model trained to imitate rubric scores on short explanations. Reducing score-prediction loss may improve agreement with the training raters. Yet the model could rely on vocabulary or length instead of the quality of reasoning. If the raters' judgments are inconsistent, the model learns from that uncertainty as well. A system may perform well on its loss while giving unhelpful feedback or disadvantaging a particular writing style. The training target is an operational proxy, and educators need to inspect what it captures and omits.
Evaluation should include outcomes outside the training objective. For the explanation model, examine errors by rubric dimension, inspect feedback usefulness, and test whether learners improve on an independent task. Compare performance on new prompts and relevant learner groups. Keep validation and final evaluation separate from optimization. A lower loss on development data is informative about that objective and dataset; it is not a complete claim about learning, fairness, or suitability for decisions that affect students.
A classroom exercise can ask learners to choose between absolute and squared error for fictional resource-duration estimates, then justify the consequences of each choice. A second exercise asks what would be missed if a writing tutor optimized only rubric-score agreement. These comparisons make the hidden priorities of model training visible. A well-chosen loss is necessary for many successful systems, but it remains one component of a broader design. The people responsible for educational AI must connect the mathematical target to a defensible purpose and verify that important outcomes were not sacrificed along the way.


