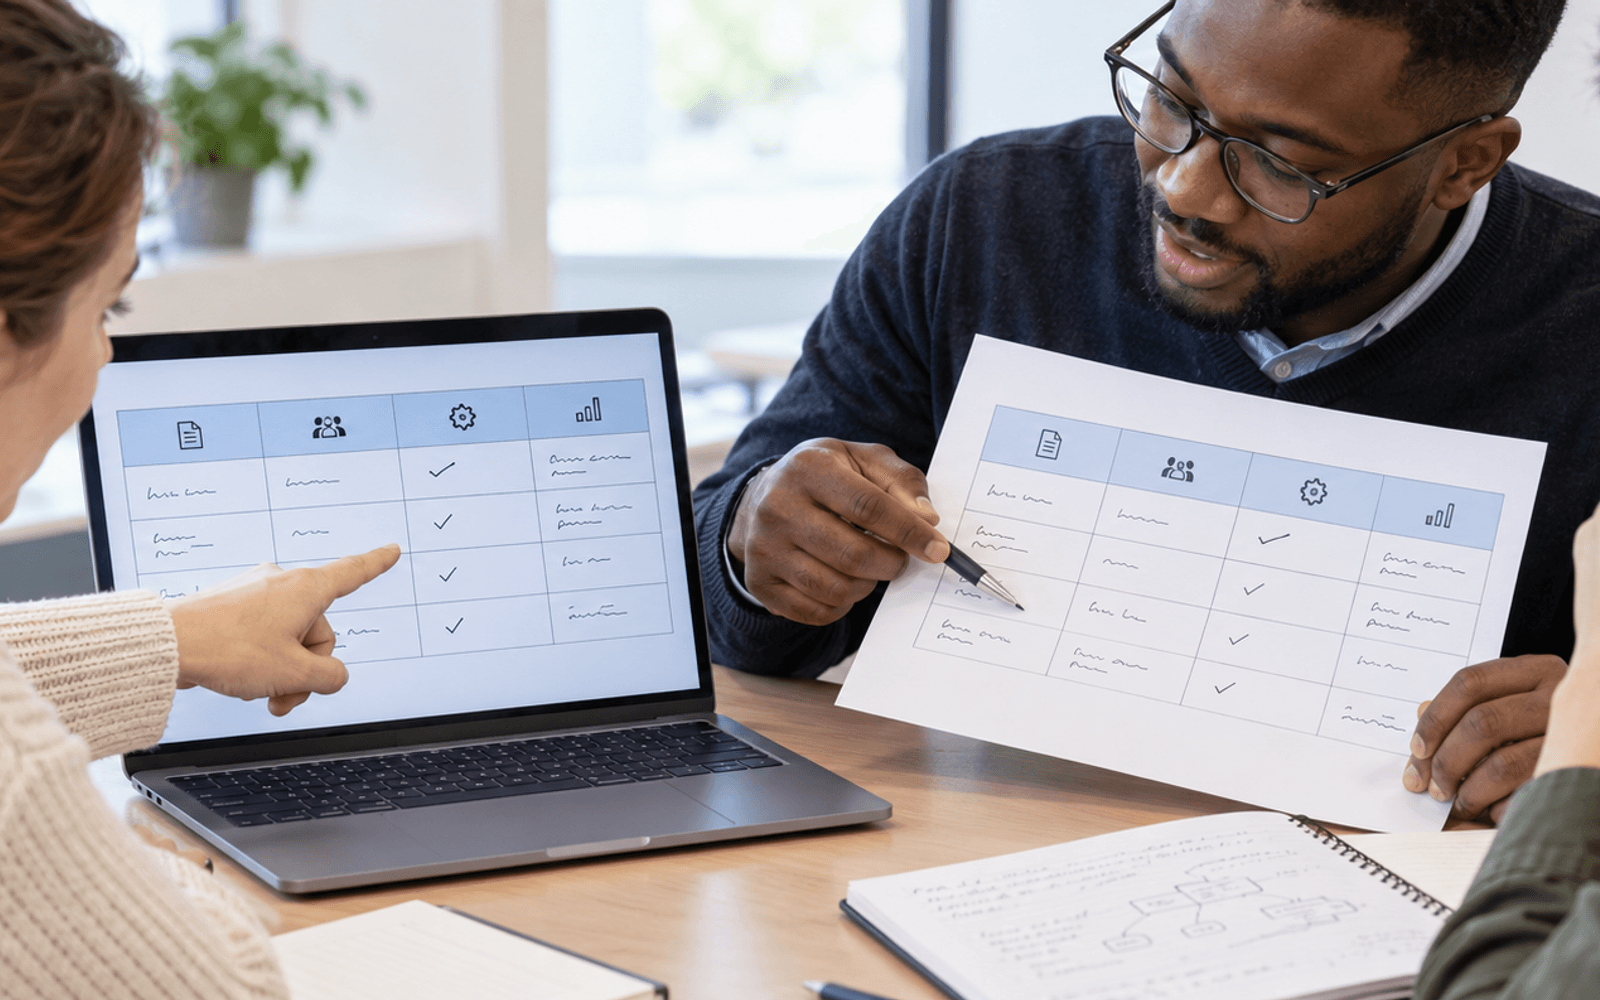
Document Layout and Table Understanding
Document understanding goes beyond recognizing words: it must recover headings, reading order, tables, and relationships that give the text its meaning. Structural errors require their own checks.
Fontes
Resumo completo
A table contains the right words and numbers, yet its extracted version assigns a score to the wrong student group. The characters were recognized, but the structure was misunderstood. Document layout and table understanding concern relationships among text regions: headings, paragraphs, columns, cells, captions, notes, and other elements. These relationships often carry information that cannot be recovered from a flat list of words alone.
A document-analysis pipeline may locate regions, recognize text, infer reading order, classify elements, and reconstruct tables. Models can combine textual, spatial, and visual information. LayoutLM illustrates pretraining that incorporates text and layout for document understanding, while PubTables-1M provides research data and methods for table extraction. These are task-specific contributions, not proof that an arbitrary scanned educational document will be interpreted correctly.
Tables are particularly demanding because their meaning depends on row and column relationships. A value may inherit a heading from a merged cell, rely on a unit printed above the table, or be qualified by a footnote. Empty cells can mean missing, not applicable, or continuation rather than zero. A multi-page table may repeat headings or split a row. Flattening all this into text can preserve every character while changing the information.
Imagine a teacher comparing two course-assessment schemes in a PDF. A table lists components and weights, with one column for each course. The extraction process shifts a percentage into the adjacent column and drops a note about an optional task. An AI summary then confidently describes the wrong assessment balance. The teacher verifies the extracted rows against the original page, checks that each course's intended weights are interpreted consistently, and preserves the qualifying note in the revised representation.
Validation should therefore test structure as well as transcription. Inspect reading order in multi-column pages, correspondence between cells and headers, units, captions, and footnote links. Use representative documents with difficult layouts rather than only clean examples. For downstream calculations, reconcile totals where a valid total is expected, but do not assume that a plausible sum proves every cell is correctly assigned. Keep page coordinates or another traceable link so reviewers can locate the original evidence.
A learning activity can provide the same information as a page image, a flattened text stream, and a reconstructed table. Learners identify which questions each version can answer and which relationships are missing. They then design a structure that preserves meaning and supports accessible use. In educational AI, document understanding is valuable when it makes source material more usable without inventing organization that was never present. A polished spreadsheet or summary should remain a checked interpretation of the original. When a layout is ambiguous, record that uncertainty and seek clarification rather than silently turning a guess into a definitive data field.


