Confidence Intervals for AI Evaluation
Confidence intervals express uncertainty in estimated AI performance under specific assumptions. Useful reporting identifies the sampling unit, method, paired comparisons and sources of variation that remain outside the interval.
Fontes
Resumo completo
A confidence interval describes uncertainty in an estimated quantity, such as an AI system's accuracy or its average response time. Evaluation uses a finite sample, so another comparable sample could give a different result. An interval makes some of that sampling uncertainty visible. It does not automatically include every source of uncertainty, such as biased test data, an unreliable scoring rubric, or changes in the deployed system.
In a frequentist interpretation, a 95 percent confidence procedure would cover the fixed target quantity in about 95 percent of repeated comparable samples, if its assumptions hold. After one interval is calculated, the target is not assigned a 95 percent probability of lying inside it by that statement alone. The distinction matters because confidence describes a procedure's long-run behavior, not a guarantee about an individual prediction or learner.
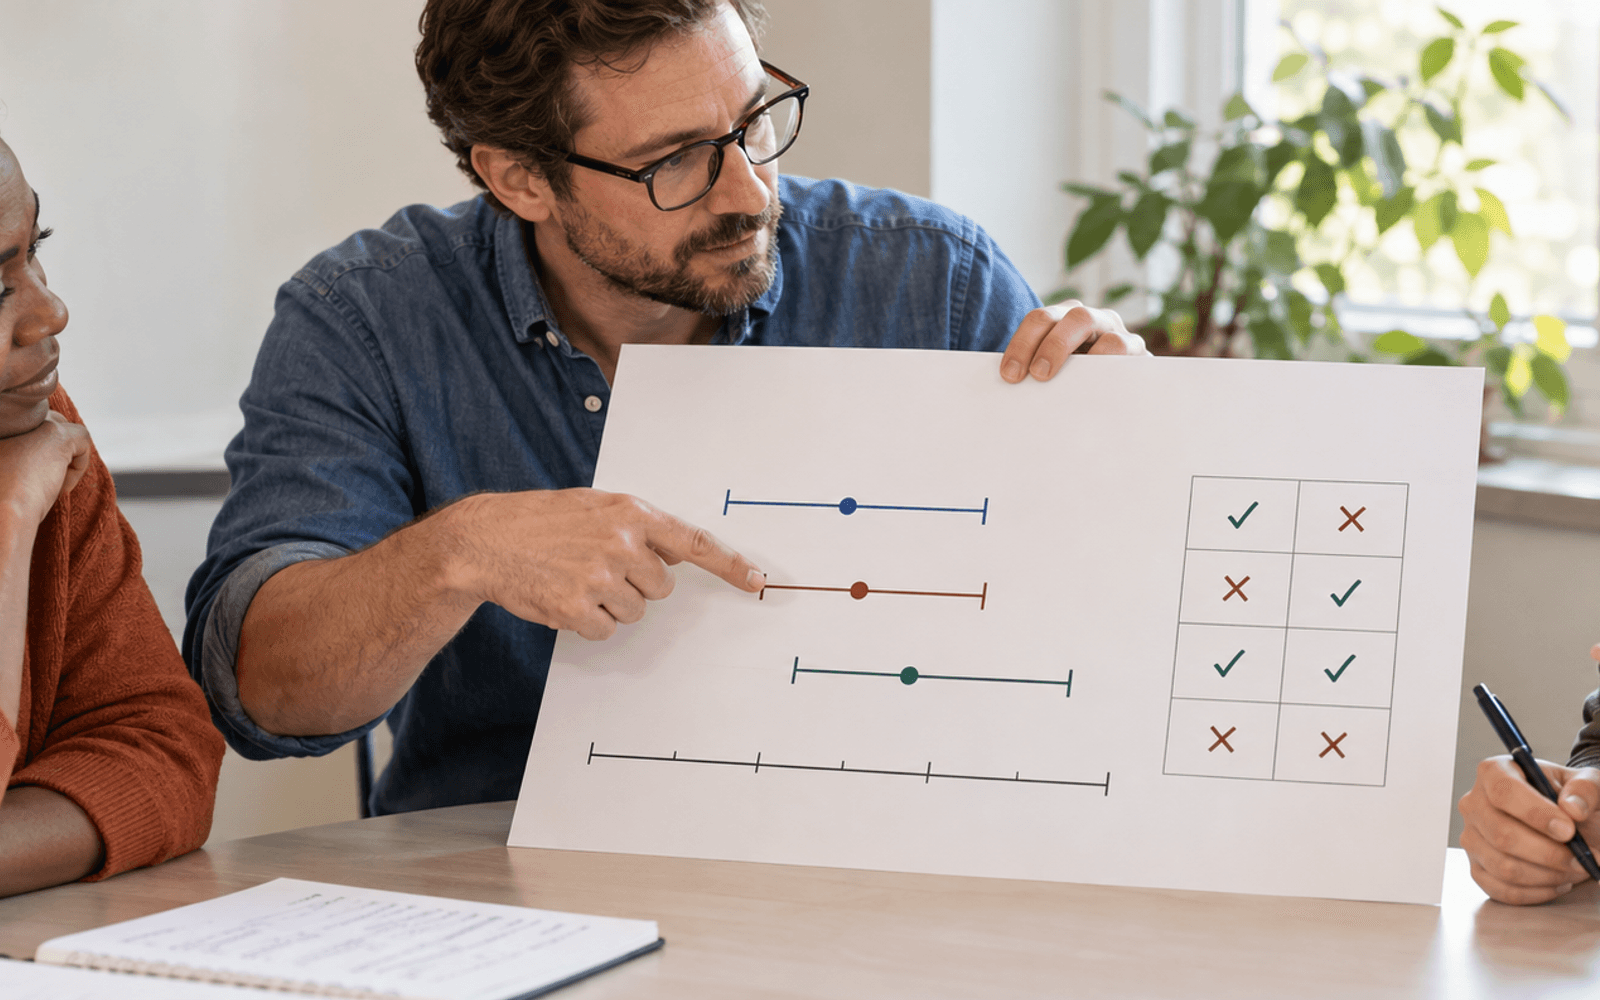
Suppose two fictional tutoring systems answer the same 100 reviewed questions. One answers 92 correctly and the other 94. Reporting only those percentages can make the second appear decisively better. A careful comparison examines uncertainty in the difference and which questions each system missed. Because both systems answered the same items, the data are paired. The pattern of shared and different errors contains information that two separate headline intervals do not capture.
The interval method should fit the metric and design. Accuracy is a proportion, while response time is often skewed and may require a different approach. Bootstrap methods repeatedly resample the observed data to estimate variability, but their usefulness depends on how resampling is performed. If many questions come from the same student, classroom, or source document, treating them as independent can understate uncertainty. Resampling meaningful clusters may better reflect the evaluation design.
Educational evaluations can have several sources of variation. Sampling different learners differs from generating multiple responses to the same prompt. Repeated model runs can reveal generation variability, but they do not replace a representative set of tasks. Human raters introduce another source of uncertainty. State which quantity the interval targets and which sources of variation the analysis includes. A very narrow interval around a biased estimate can create false reassurance.
Teachers can explore the idea using a jar of labeled fictional outcomes and repeated samples. Each group estimates an accuracy rate from its draw, then compares estimates and intervals across groups. The exercise can be extended by making outcomes cluster by classroom to show why the sampling unit matters. Keep this as a statistical illustration, not evidence about any real product. The goal is to see that uncertainty follows the design of data collection and analysis.
Report the estimate, interval, sample size, sampling unit, and method alongside practical consequences. Overlapping intervals do not by themselves settle a formal comparison, and a statistically detectable difference may be educationally trivial. Predefine important comparisons to reduce selective reporting. Confidence intervals improve AI evaluation when they make the limits of an estimate intelligible and help people decide what further evidence would materially change a decision.