← 연구 뉴스로 돌아가기

#learning analytics

learning analytics

11 논문

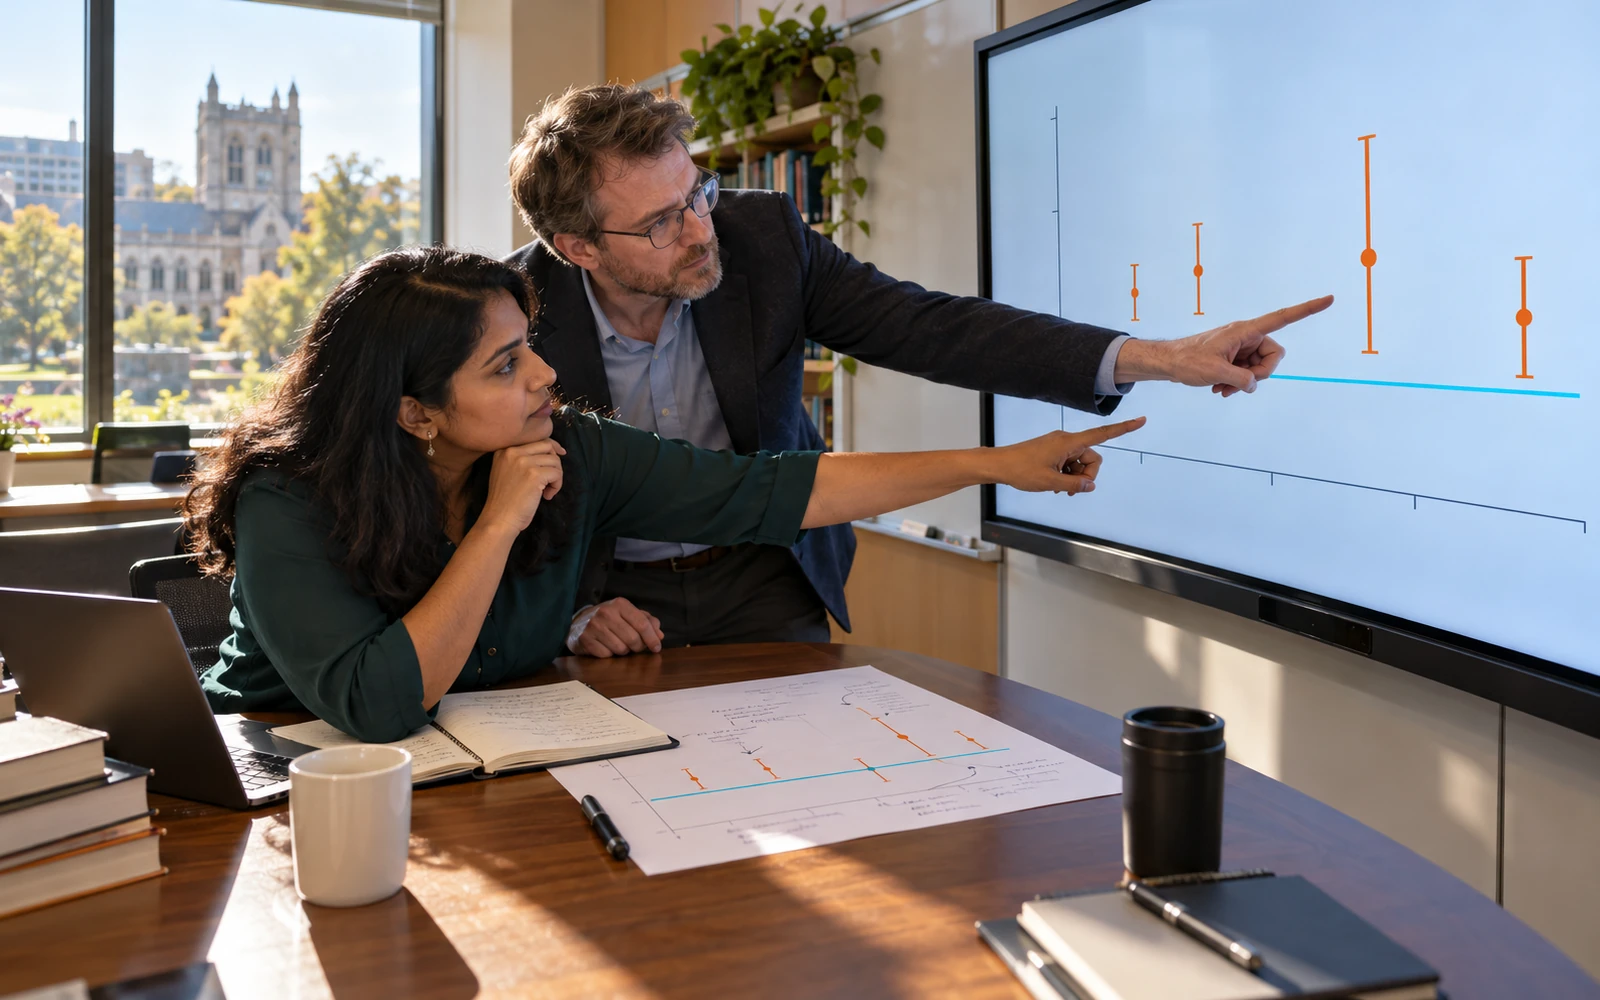
Illustrative photograph of two educators examining a simple prediction baseline and uneven error bars on a seminar-room display.
도구 / 데이터셋2026
도구 / 데이터셋 245

Preprint: Tutoring logs add little to simple score predictions in one course

Zeyu Dong, Mikael Kwame Kuada, Asa Holley Buchakjian-Tweedy, Ibrahem Aljabea

arXiv preprint

A retrospective analysis compares tutoring-interaction features with constant score predictions. Small overall gains and uneven errors show why a support model needs more than a favorable average accuracy figure.

preprintlearning analyticsprediction baselines
500단어 요약 읽기 →
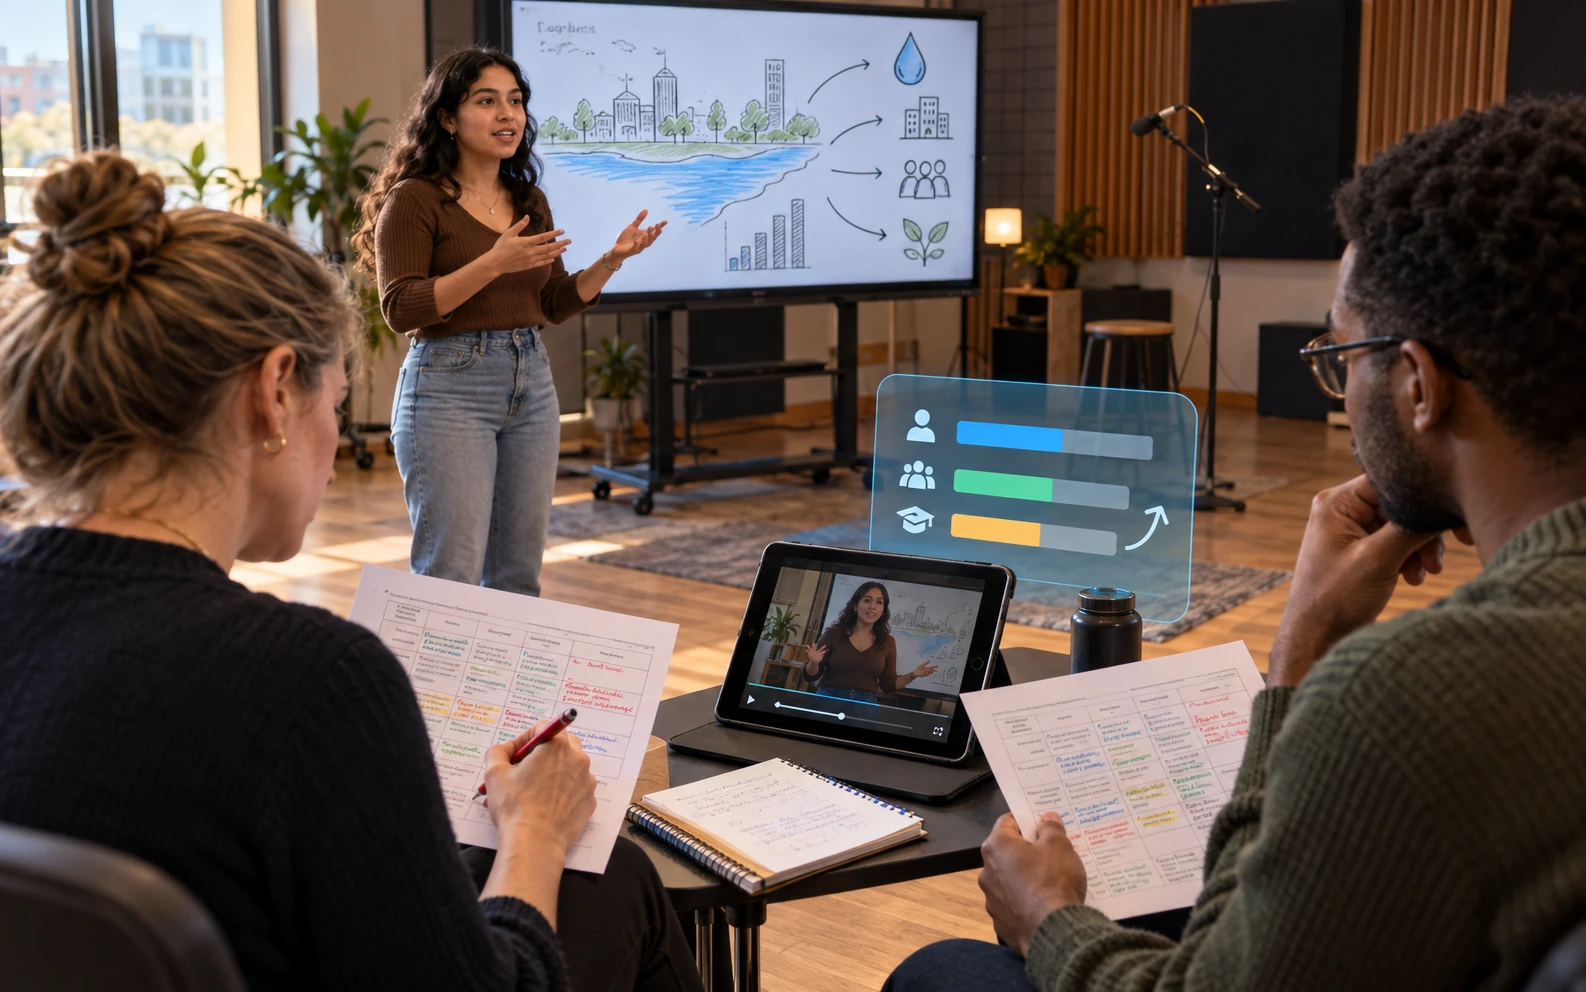
강사와 동료가 루브릭 주석을 태블릿의 녹음 내용과 비교하는 동안 대학생이 물 사용에 대한 프레젠테이션을 연습하고 있습니다.
학회 논문2026
학회 논문 230

학술대회 시연 논문: AICoFe가 동료 평가·자기 평가와 교사가 검토한 AI 피드백을 연결하다

Alvaro Becerra, Alejandra Palma, Ruth Cobos, Julian Fierrez

European Conference on Technology Enhanced Learning (EC-TEL 2026), demonstration paper

AICoFe 데모 문서는 프레젠테이션 녹음, 루브릭 판단, 교사가 선별한 AI 피드백을 연결하는 워크플로를 설명합니다. 대학 배치에는 긍정적인 만족도 평가를 받은 65명의 학생이 참여했습니다. 보고된 증거는 인식된 유용성과 유용성에 관한 것이며, 학습 이득과 장기적인 작업량은 조사 대상으로 남아 있습니다.

동료 평가자기평가교사의 검토
500단어 요약 읽기 →
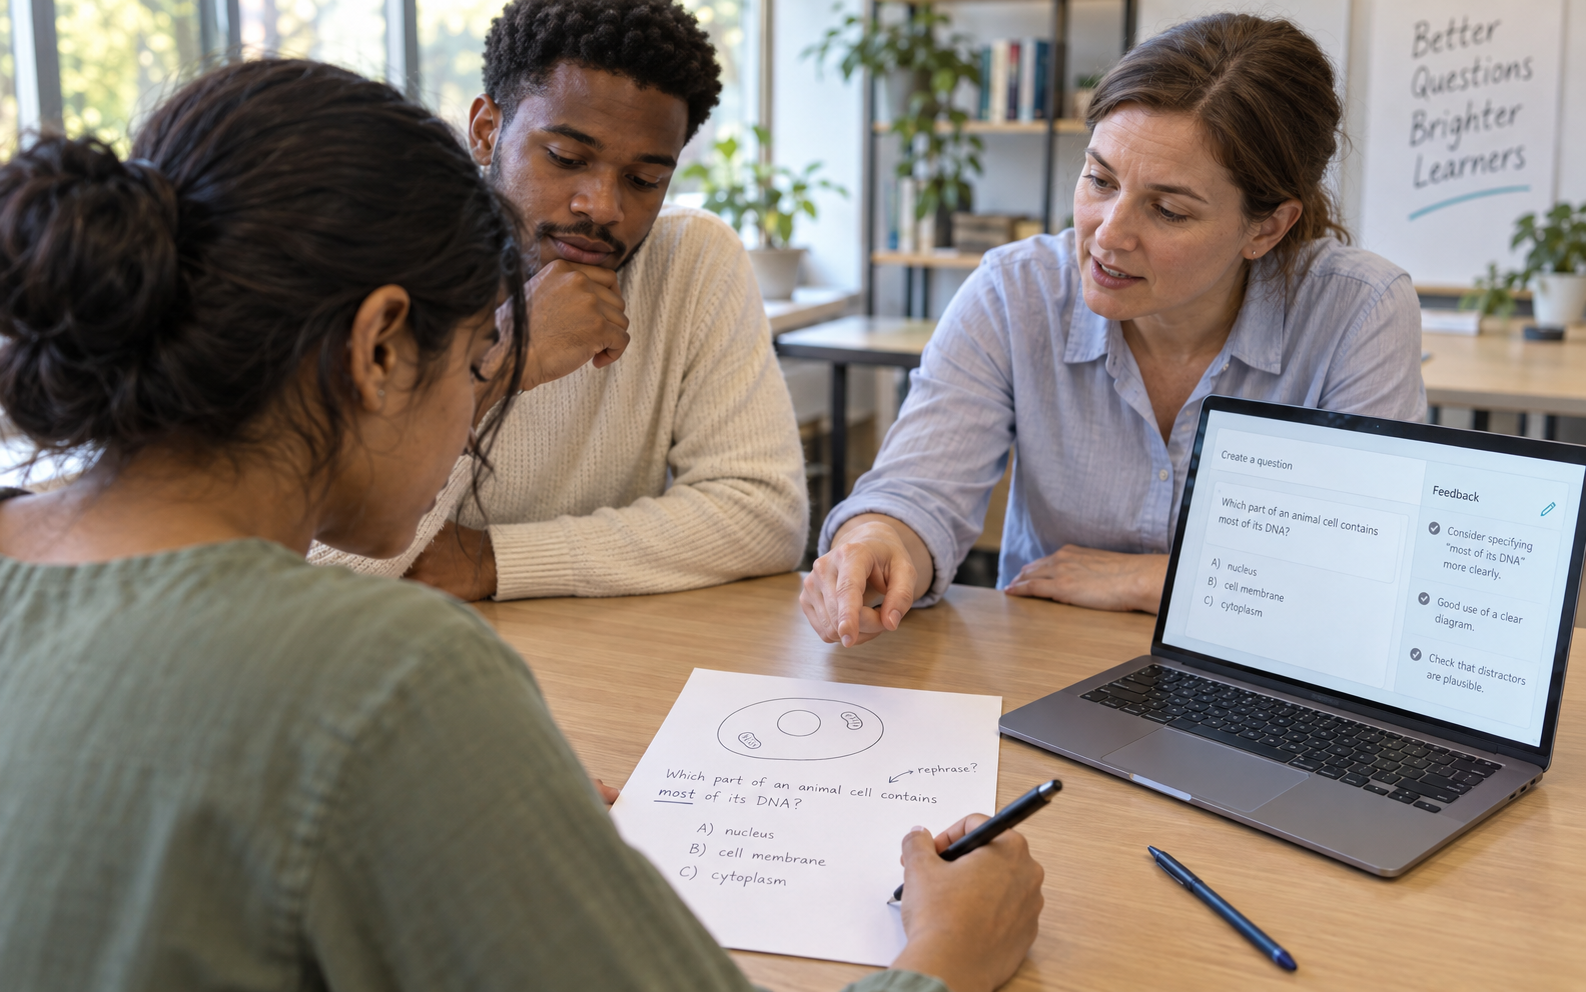
A university student revises a biology multiple-choice question while a classmate and lecturer consider feedback shown beside a simple animal-cell drawing.
저널 논문2025
저널 논문 212

AI-Assisted Co-Creation: Bridging Skill Gaps in Student-Generated Content

Stanislav Pozdniakov, Jonathan Brazil, Mehrnoush Mohammadi, Mollie Dollinger, Shazia Sadiq, Hassan Khosravi

Journal of Learning Analytics

Students often rated AI feedback positively when creating multiple-choice questions in RiPPLE, but visible revision followed in only about 35 percent of editing sessions. The study examined feedback, activity logs, and student comments across introductory university courses. Its findings separate liking a response from using it and from learning through it. They suggest that question-authoring activities need explicit support for evaluating feedback, alongside safeguards against inaccurate or irrelevant suggestions.

Learning AnalyticsStudent AgencyAI Feedback
500단어 요약 읽기 →
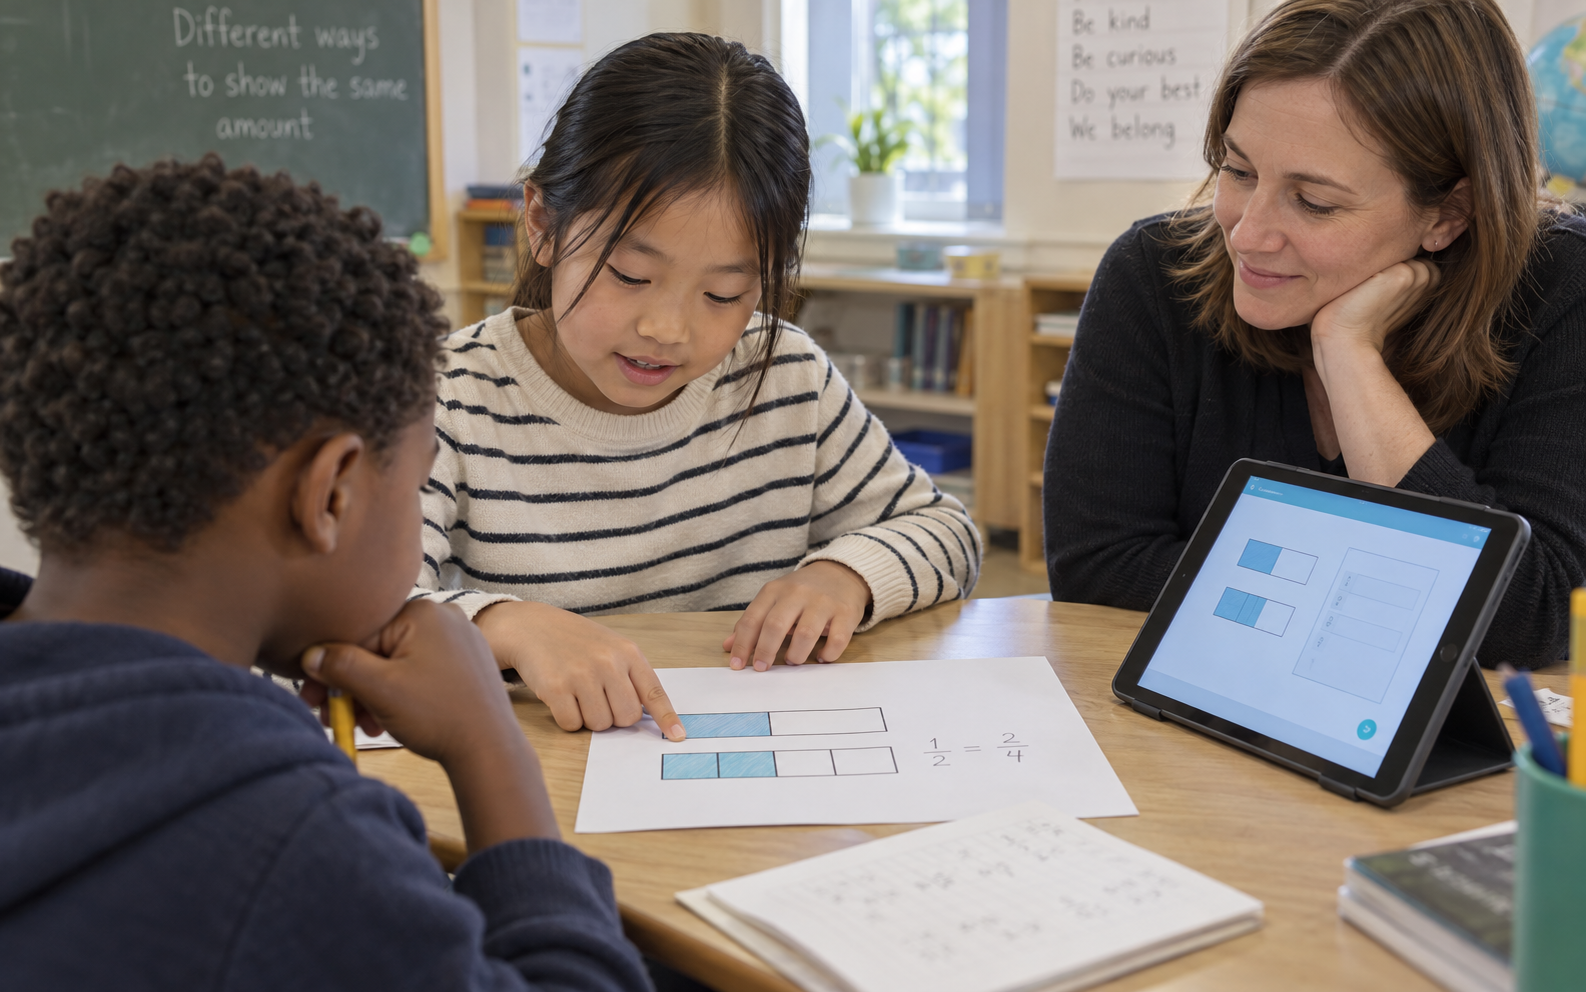
A teacher and two primary pupils compare equivalent fraction bars on a worksheet beside a tablet practice activity.
저널 논문2026
저널 논문 194

Computer-assisted learning in the real world: How Khan Academy influences student math learning

Taryn Eames, Emma Brunskill, Bogdan Yamkovenko, Kodi Weatherholtz, Philip Oreopoulos

Proceedings of the National Academy of Sciences

A large United States study links Khan Academy use with mathematics progress across roughly 214,000 students. Its observational design uses changes in classmates’ usage and extensive statistical controls, rather than random assignment. Average exposure was modest, and higher prior achievers appeared to benefit more. The findings highlight implementation and access to practice, while leaving uncertainty about causation. They concern established computer-assisted learning and should not be read as evidence for generative-AI chatbots.

Mathematics EducationAdaptive LearningLearning Analytics
500단어 요약 읽기 →
A student adviser and two adult learners review a feasible intervention timeline, a resource budget, and a learner-support dashboard in a university advising room
도구 / 데이터셋2026
도구 / 데이터셋 106

SC2R made student-risk recommendations machine-checkable without claiming causal improvement

Ngoc Luyen Le, Marie-Hélène Abel, Bertrand Laforge

arXiv preprint

Le, Abel and Laforge introduce SC2R, a counterfactual-recourse pipeline that combines calibrated risk prediction, integer programming, an RDF intervention vocabulary, and SHACL validation. Offline OULAD experiments show that semantic checks can reject plans that ignore timing, budget, immutability, or availability. The authors explicitly avoid causal outcome claims, so the contribution is operational feasibility rather than proof that an intervention helps students.

learning analyticscounterfactual recoursesemantic constraints
500단어 요약 읽기 →
A programming lecturer and two university students review an educator-verified lecture clip timeline, code diagrams and study notes in a bright computing studio
도구 / 데이터셋2026
도구 / 데이터셋 96

Lecture-video curation grounded AI help in course material, but the pilot measured engagement rather than learning

Owen Tang, Alexandra Vassar, Jake Renzella

arXiv preprint

Tang, Vassar and Renzella tested an alternative to open-ended AI answers: use LLMs to retrieve short, educator-delivered lecture clips for novice programming questions. Proprietary models produced relevant and sufficient selections across five benchmark queries, and a 903-student pilot showed repeat use and positive voluntary ratings. However, low overlap with one lecturer, LLM-only quality judgments and no learning-outcome measure mean the study demonstrates retrieval feasibility and engagement, not safer or better learning.

lecture video curationCS1retrieval-augmented generation
500단어 요약 읽기 →
A diverse group of university students and a lecturer examine clustered dialogue cards, a ten-trait matrix and an exam-progress chart in a bright learning analytics studio
도구 / 데이터셋2026
도구 / 데이터셋 94

Principal Trait Analysis linked AI-tutor dialogue patterns to outcomes, but not yet to transferable skills

Hunter McNichols, Kai Du, Andrew Lan

arXiv preprint

McNichols, Du and Lan introduce Principal Trait Analysis, an LLM-assisted pipeline that turns human-AI conversation traces into interpretable behavioral traits. On 1,540 university AI-tutor sessions and 2,774 professional coding-agent sessions, selected traits added explanatory or predictive signal beyond prior performance. Conceptual questioning aligned positively with some exam outcomes, but cross-semester inconsistency, contradictory coefficients and mostly flat temporal patterns mean the traits cannot yet be treated as transferable AI collaboration skills.

Principal Trait AnalysisAI tutoring dialoguehuman-AI collaboration
500단어 요약 읽기 →
An academic adviser and two university students compare concurrent course schedules, predicted grade ranges, and an advising decision map
도구 / 데이터셋2026
도구 / 데이터셋 100

TRACE predicted courses and grades jointly, cutting grade error without establishing intervention benefit

Paul Savala

arXiv preprint

Savala introduces TRACE, a transformer that represents courses by semester and jointly predicts a student's next course set and corresponding grades. On ten years of institutional data, joint training reduced mean absolute grade error by nearly 50 percent compared with the same architecture predicting grades alone and outperformed LSTM and graph baselines. External validity, fairness, calibration, and intervention effects remain open.

course predictiongrade predictiontransformer
500단어 요약 읽기 →
A diverse computer science class uses a learning dashboard to record self-assessments and discuss algorithms with a teacher and an AI dialogue panel
저널 논문2026
저널 논문 76

An eliciting LLM dashboard prompted more reflective dialogue and showed a trend toward stronger learning-judgment calibration

Laura Graf, Patrick Bassner, Maximilian Anzinger, Felix Dietrich, Stephan Krusche, Oleksandra Poquet

Education and Information Technologies

A five-week exploratory study with 30 computer-science students compared no agent, a telling LLM agent and an eliciting agent inside a learning dashboard. The eliciting condition produced more reflective messages and showed descriptive trends toward clearer relationships between self-judgments and mastery estimates, but the study did not test achievement gains.

learning analyticsLLM pedagogical agentlearning dashboard
500단어 요약 읽기 →