How Adding Metacognitive Requirements in Support of AI Feedback in Practice Exams Transforms Student Learning Behaviors
Mak Ahmad, Prerna Ravi, David Karger, Marc Facciotti
Proceedings of the Twelfth ACM Conference on Learning @ Scale
500단어 요약
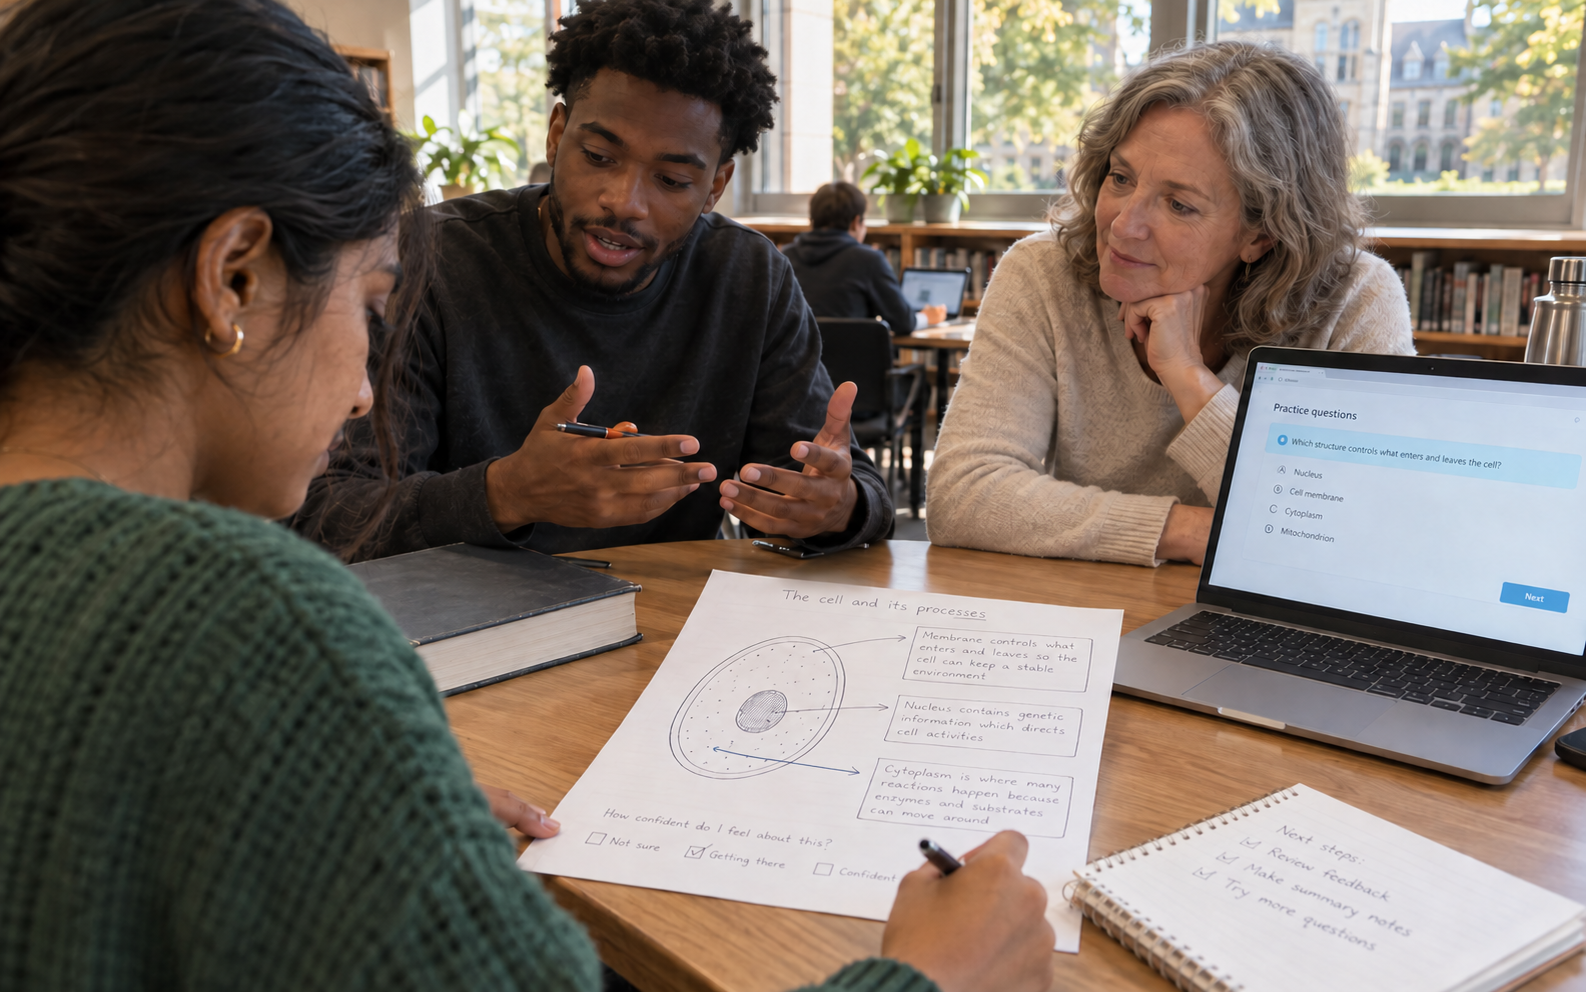
Asking students to explain an answer and judge their confidence may change how they approach practice. Adding a generative-AI explanation is a separate instructional decision. A Learning @ Scale study in a large introductory biology course brings those choices into the same platform, while showing why favorable learner accounts should be interpreted separately from evidence of improved examination performance.
Mak Ahmad and colleagues investigated practice exams in a University of California, Davis course enrolling 1,002 first-year biology students. Across three midterms, the consenting participant counts were 541, 342, and 413; these are overlapping exam-specific groups, not three independent samples to add together. The study analyzed 28,313 student-question interactions. This setting gives the work practical relevance: feedback was embedded in preparation for real course assessments, rather than evaluated only through an isolated demonstration.
The platform offered four feedback conditions: correctness information alone, correctness with relevant textbook links, personalized GPT-4o feedback, and the combination of AI feedback with textbook links. Assignment varied within students across questions. A consistent allocation procedure connected students, questions, and exams, allowing learners to encounter the different forms of feedback. Actual midterm questions were linked to practice opportunities through their learning objectives, providing an outcome beyond whether students appreciated the interface.
Every condition also required students to explain their answer and report confidence. That common feature is central to interpreting the results. The comparison can address differences between the feedback packages on top of those requirements. It cannot establish what would have happened without the explanation and confidence prompts, because a corresponding condition was not included. Descriptions of greater reflection are therefore informative about learner experience, but they do not identify an experimentally isolated metacognitive effect.
On the main performance comparison, the researchers did not find a statistically significant overall effect of feedback condition on subsequent exam performance. The reported test had a p value of .093. Suggestive numerical patterns should not be promoted into a demonstrated achievement advantage for AI feedback. The absence of a significant result also does not prove that all packages are equivalent; uncertainty, implementation, exposure, and assessment alignment remain relevant to interpreting that finding.
The qualitative evidence was more encouraging about study behavior. A survey collected 279 responses, and 23 interviews involved 19 students, with four interviewed twice. Students described changes in reasoning, awareness of uncertain knowledge, preparation strategies, and engagement with explanatory resources. These accounts help explain which parts of the experience learners noticed. They provide plausible design ideas for future studies, while retaining the limitations of self-report and voluntary participation.
For course teams, the study suggests separating two evaluation questions: does a practice system elicit the thinking that instructors want, and does a particular feedback addition improve independent performance? A useful classroom pilot would preserve explanation and confidence data, examine how learners respond to corrections, and include an appropriate comparison for any claimed mechanism. Evidence from this single course, without a baseline biology assessment, cannot establish broad achievement gains or long-term retention. Its contribution is a realistic view of promising learning behaviors alongside a non-significant overall performance comparison.