AI-assisted short-answer grading broadly resembled instructor grading, without testing learning gains
Tobias Heinrich, Spencer Baily, Kuan-Wu Chen, Jack DeOliveira, Sanghoon Park, Navida Chun-Han Wang
PLOS ONE
500語要約
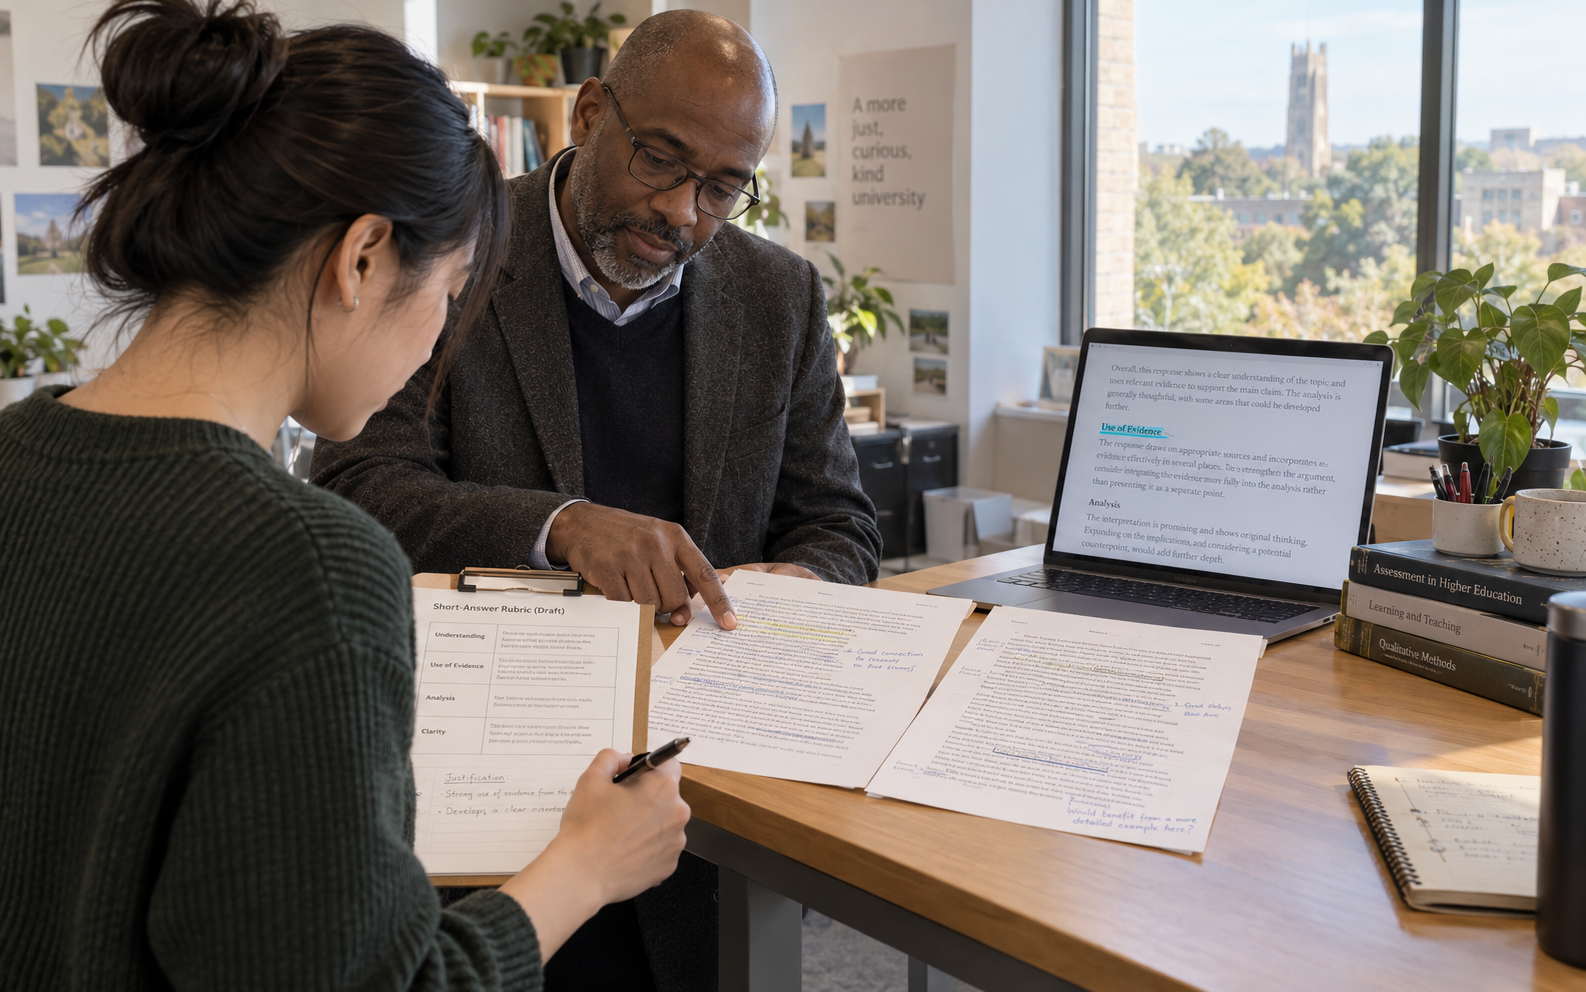
Detailed comments on short answers are valuable but difficult to provide repeatedly in a large class. Tobias Heinrich and colleagues tested whether a language model could extend an instructor's grading approach by using explicit criteria and examples. Their political-science study evaluated the resulting scores, student requests for regrading and perceptions of feedback. The relevant question was whether an AI-assisted workflow could approximate selected aspects of instructor grading at scale, not whether automated scoring should become the final authority over an academic judgment.
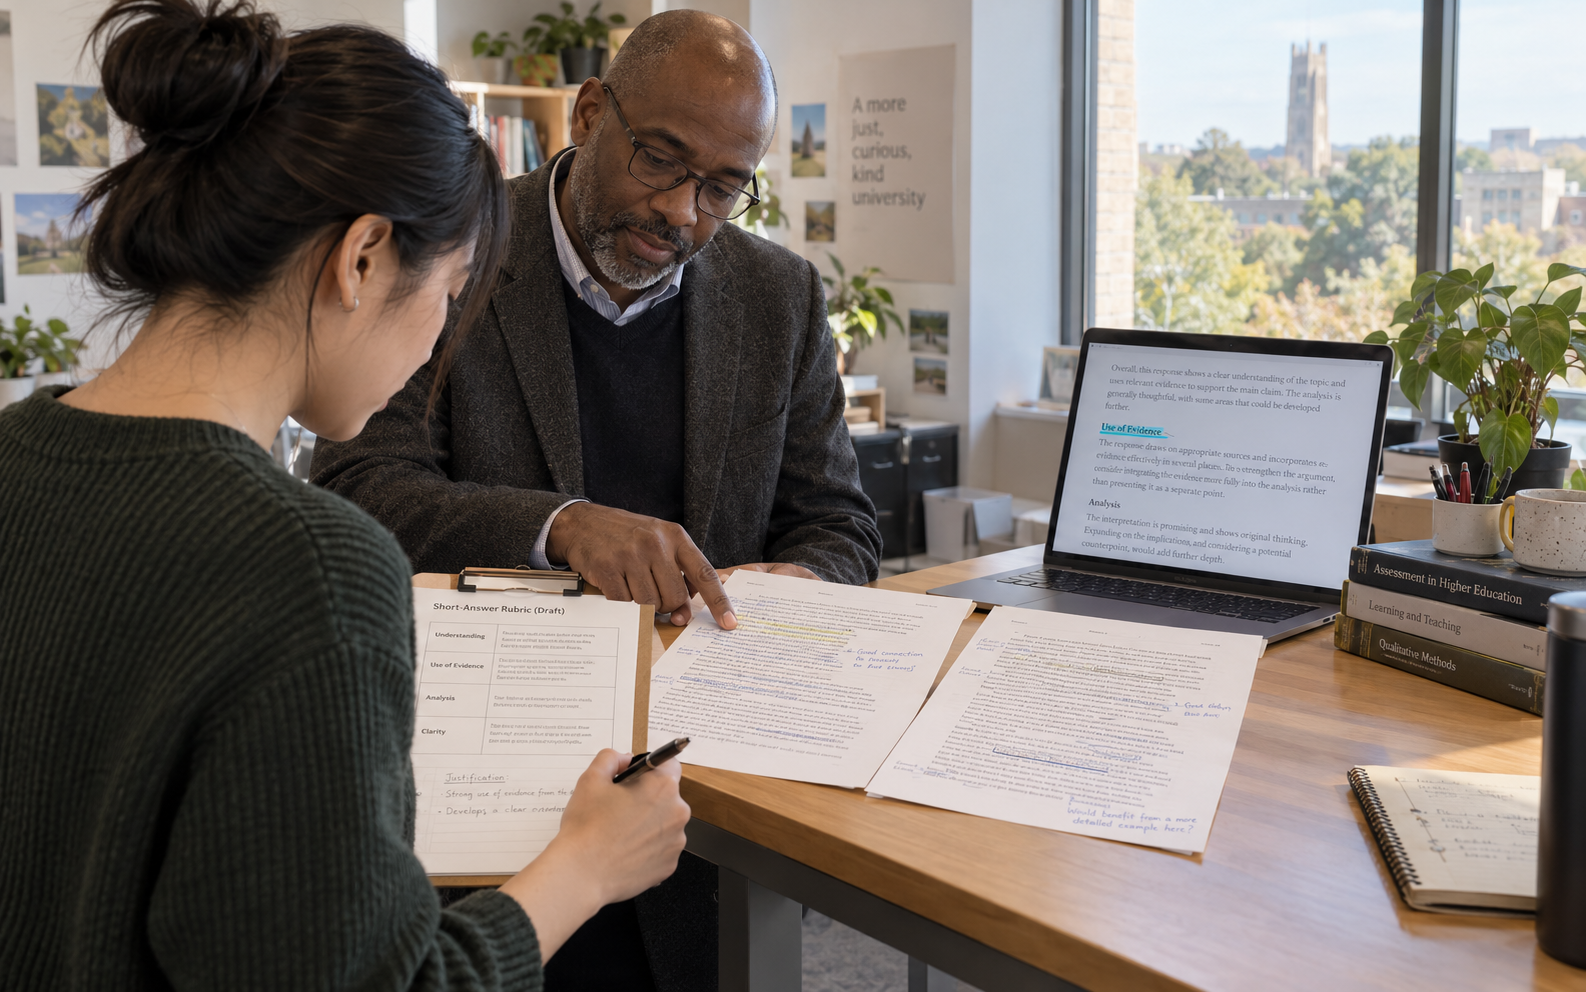
The analysis covered 271 students, twenty-six tests and 3,080 short-answer responses across undergraduate courses in the 2023–2024 academic year. About 88 percent of responses received AI-assisted grading. For each question, randomly selected responses were graded intensively by instructors and used as examples in a prompt that also contained the question, rubric and a new response. GPT-4 then produced a score and written feedback for the remaining answers. Students were informed of the approach and could request human regrading under the course policy.
The researchers examined three outcomes. First, they tested how closely a short-answer score tracked performance on other assessment items. Second, they analyzed requests for human regrading as a practical signal of grading problems students considered worth contesting. Third, they asked students how helpful they found prior feedback. Random assignment of responses supported comparison of grading methods, but these outcomes capture different aspects of assessment quality. None is a direct test of whether reading the feedback caused subsequent learning or improved critical thinking.
Average differences between grading methods were generally small, with variation across courses and student subgroups. The pooled difference in score discrimination was not significant. Human-graded responses attracted slightly more regrade requests, while human feedback was modestly more likely to be rated helpful overall. The study therefore supports further investigation of instructor-guided AI grading without establishing that one method is uniformly superior. Similarity on these measures also does not mean that every individual score was correct or that students received equally useful advice in every case.
The boundaries are especially important because grading affects students. Regrade requests were uncommon and could miss errors that students did not recognize or were reluctant to challenge; the policy also allowed a regrade to lower a score. The trial did not examine ideological bias, favoritism or long-term learning effects. One course contributed almost half the pooled sample, and the proprietary model may be difficult to reproduce after retirement. The experiment evaluated a particular prompt-and-example workflow rather than all forms of automated assessment or high-stakes examination scoring.
For AIEDHK, a cautious pilot could begin with low-stakes formative responses, explicit rubrics and a human appeal route. Instructors could audit both accepted grades and unchallenged responses, examine subgroup patterns and check whether feedback supports better work on a later task. Learners should understand how the judgment was produced and how to contest it. These are proposed evaluation steps beyond the paper. The useful contribution is evidence about a scalable feedback workflow, with responsibility for assessment quality and evidence of learning still requiring separate human judgment and measurement.