Abstention and Selective Prediction
How an AI system can answer only selected cases, and how to evaluate the tradeoff between fewer automated decisions and the errors that remain.
出典
完全なレッスン要約
An AI system need not make an automated prediction for every input. Selective prediction adds a choice: answer when a selection rule permits it, and abstain otherwise. An abstention can route the case to a teacher, request more information, or explain that the available evidence is insufficient. This differs from simply adding cautious wording to every answer. The system changes which cases it is willing to handle automatically.
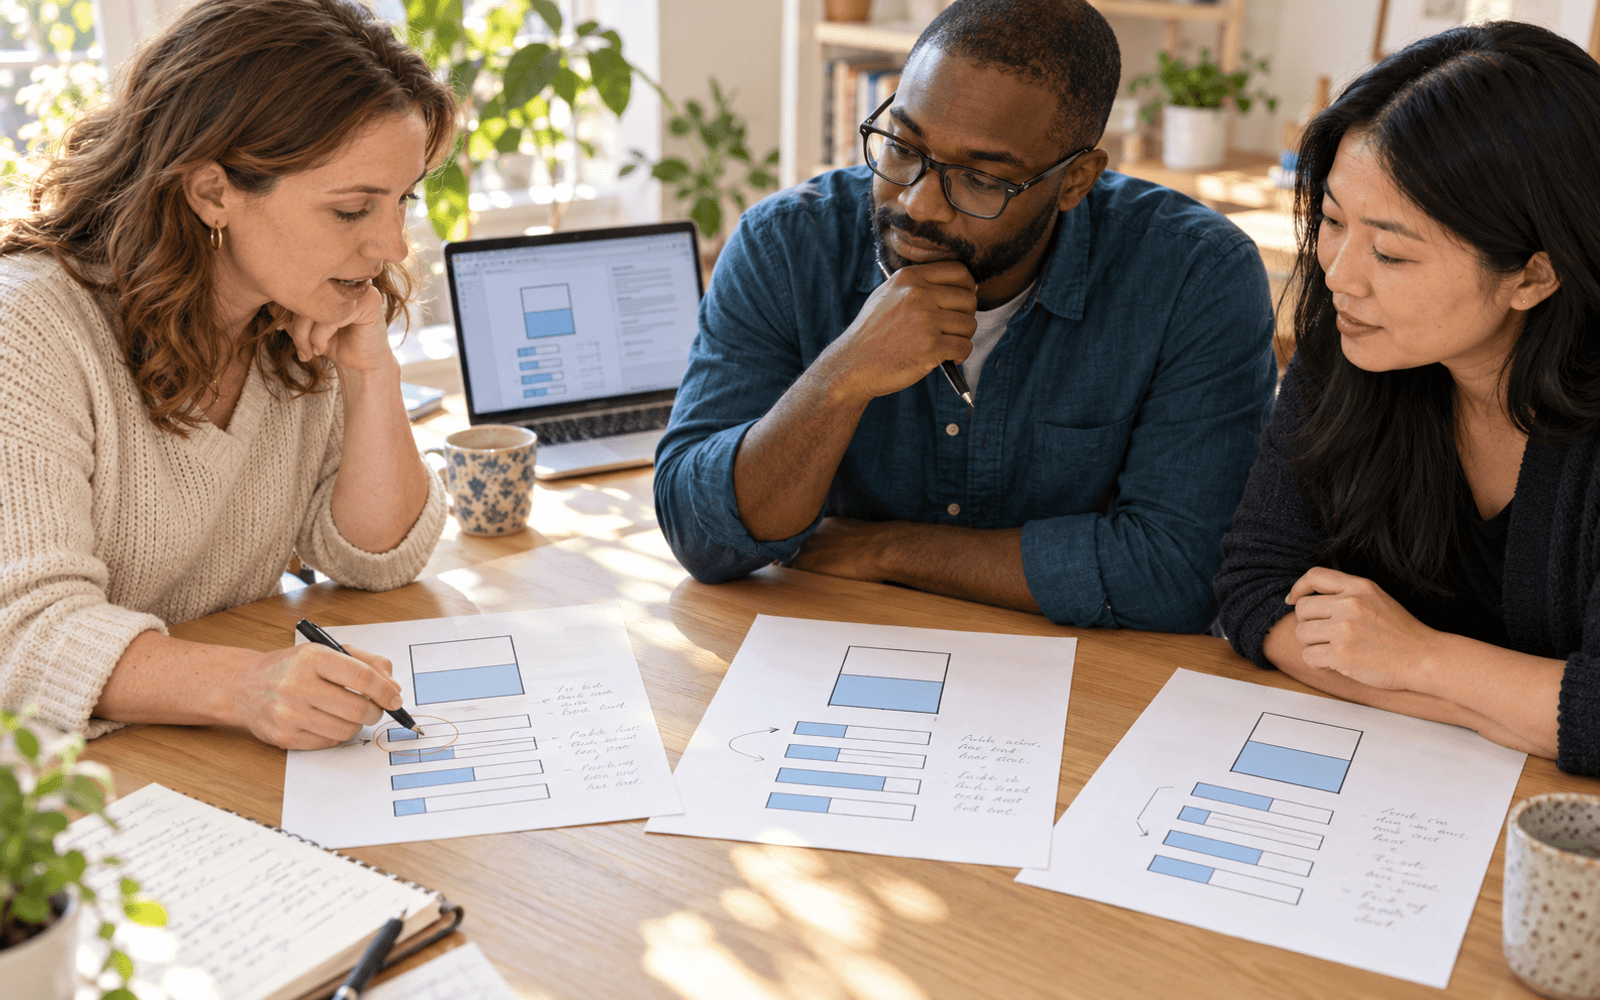
Two quantities describe the tradeoff. Coverage is the proportion of cases accepted for prediction. Selective risk is the error or loss among those accepted cases. Reducing coverage may reduce error among the remaining predictions if the selection rule successfully identifies difficult cases. Research on selective classification and SelectiveNet studies this relationship. A system that abstains on everything has low exposure to automated errors, but it also provides no automated service. Coverage and risk must therefore be reported together.
Suppose a teacher evaluates a fictional classifier on 100 independently labeled science explanations. When required to classify every explanation, it makes ten errors. With an abstention rule, it accepts 70 explanations and makes three errors among those accepted. Coverage is 70 percent and accepted-case error is approximately 4.3 percent. The other 30 explanations still need attention. These illustrative numbers do not establish that the policy is useful: the teacher must also consider which cases were deferred, how long review takes, and what happens if review is unavailable.
The selection signal can come from predicted confidence, agreement among models, distance from familiar data, or a separately learned selection function. None should be assumed reliable without evaluation. A model can be confidently wrong, especially on unfamiliar inputs. A language model saying "I am uncertain" is not equivalent to a validated error estimate. Thresholds should be chosen on suitable development data and evaluated on separate cases that reflect the intended users and tasks.
Abstention also has distributional consequences. A system may defer disproportionately often for learners who use a particular language or write in an unfamiliar style. Even if average accepted-case accuracy rises, those learners may experience delays or receive less support. Educators should examine both error and coverage across relevant groups, alongside the quality of human review. A deferred case must remain visible in the workflow; it should not disappear from a dashboard or be counted as a successful prediction.
A practical classroom activity asks learners to design a review policy for fictional homework feedback. They compare several thresholds, estimate review workload, and decide which kinds of mistakes require immediate human attention. They should also define a message that tells the learner what happens next. Selective prediction is valuable when uncertainty leads to a better allocation of responsibility. Its success depends on the whole service, including timely follow-up, rather than on a flattering accuracy figure calculated only after difficult cases have been removed.