Project scores improved with teacher and AI feedback in a structured university course
Valentina Grion, Beatrice Doria, Daniele Agostini, Giorgia Slaviero
Assessment & Evaluation in Higher Education
Ringkasan 500 kata
Valentina Grion and colleagues compared teacher feedback with two AI systems in a University of Padua assessment course involving 238 students. Forty-seven project groups entered the analysis. The course used explicit assessment criteria, and students were unaware of their feedback source. The paper labels the systems GPT-o4-mini and DeepSeek R1. Two instructors jointly supplied human feedback and scored projects while blinded to condition and stage.
Average project scores increased from 23.81 to 27.70 on a 30-point scale. Within a predefined one-point margin, the GPT-o4-mini comparison met equivalence criteria; DeepSeek R1 met non-inferiority criteria without establishing equivalence. The authors emphasize that 91% of groups scored at least 27 after feedback, leaving limited headroom for detecting differences.
The small group-level sample and ceiling effect constrain interpretation. Prior AI experience was not collected, and the design could not isolate the contribution of individual teaching components. Improvement on revised projects does not establish the same improvement on later independent tasks. These results concern the studied assessment arrangement, not a general finding that any AI output can replace a teacher’s feedback.
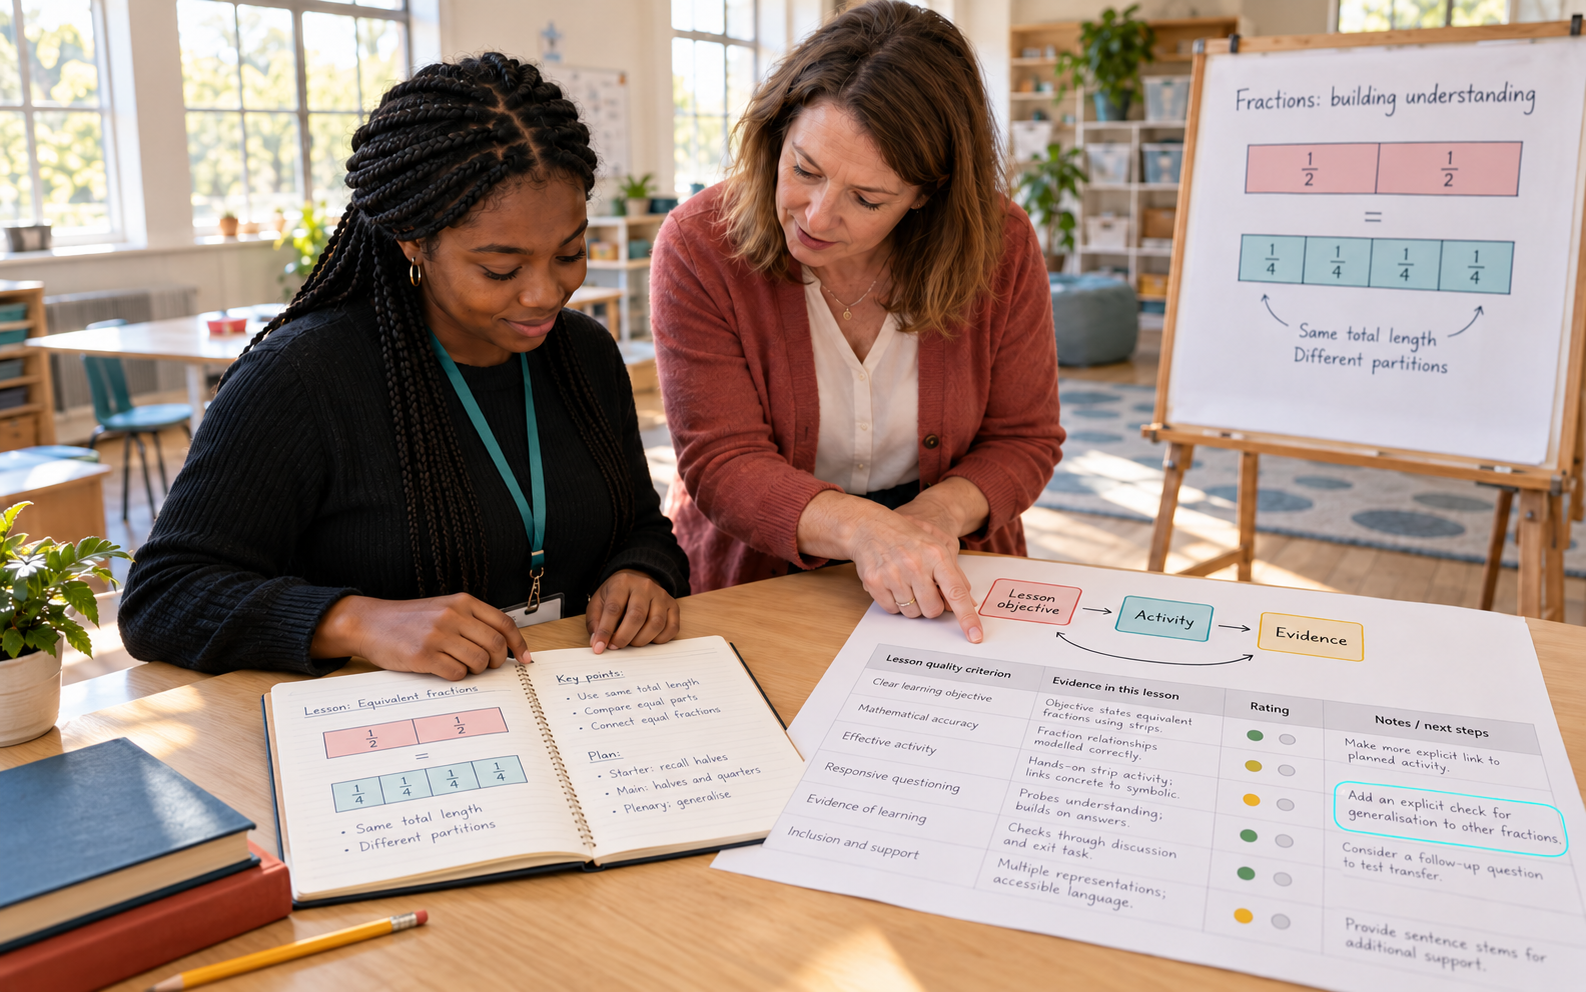
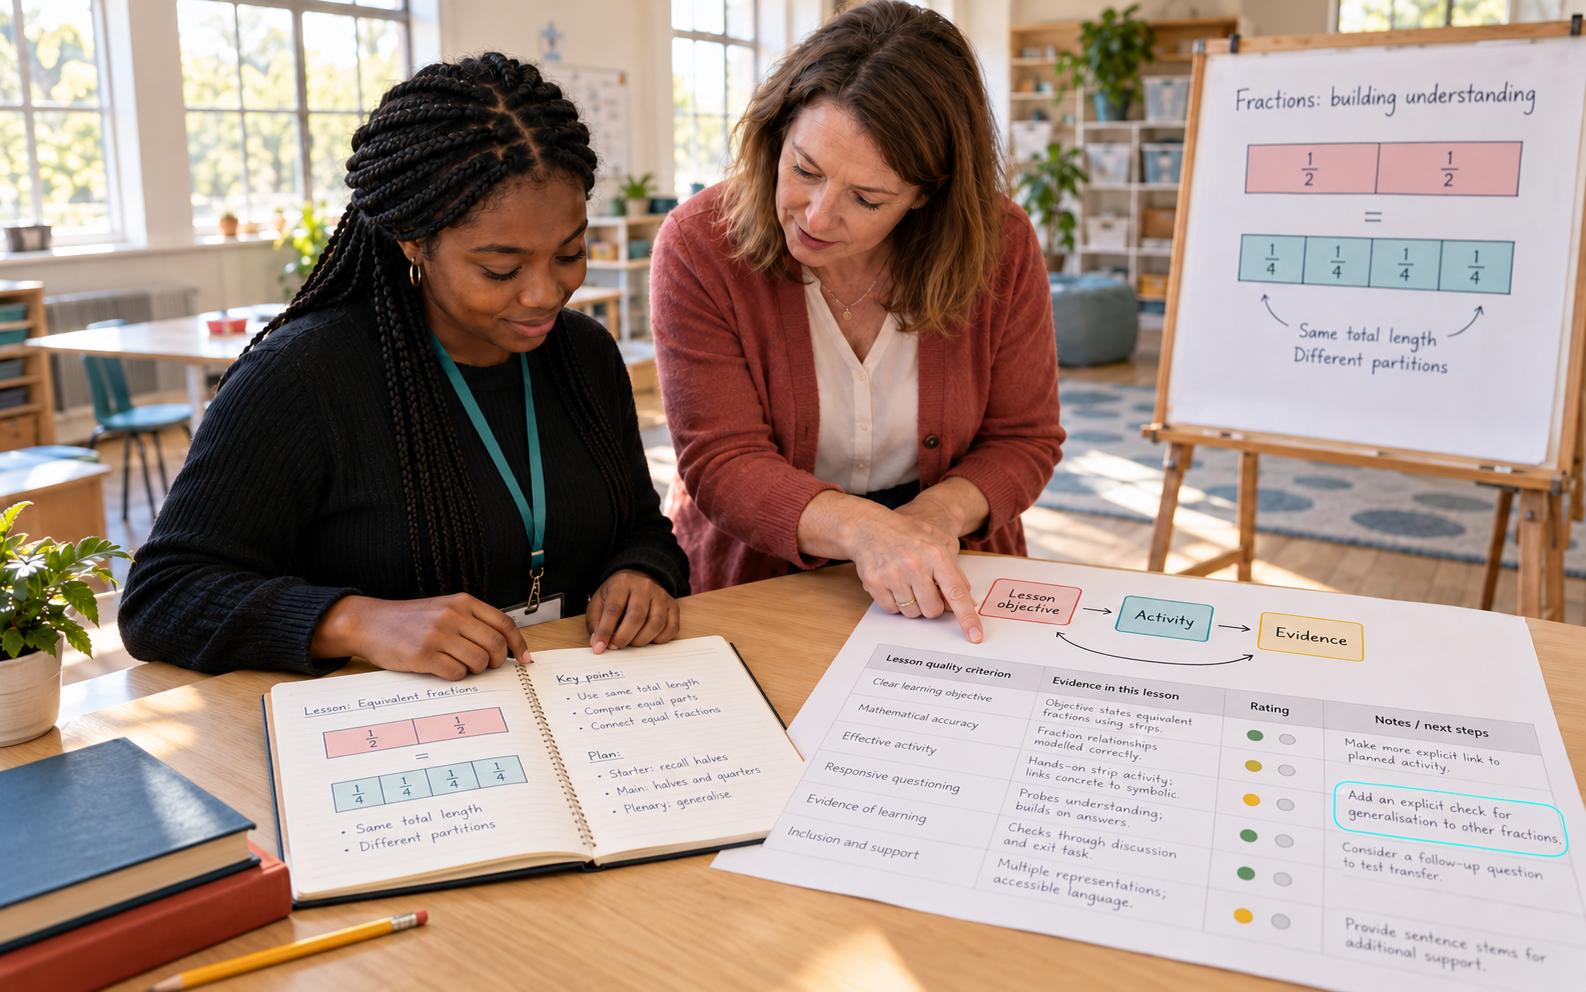
For AIEDHK, the editorial implication is to make the assessment arrangement concrete before testing a feedback provider. A teacher education team could first agree on what a strong lesson plan must demonstrate: alignment between objectives and activities, credible evidence of pupil understanding, and a workable response when learners struggle. They could then select examples illustrating different quality levels. This proposed preparation would provide a shared basis for examining generated comments; it has not been separately validated by the reported comparison.
A possible pilot would ask groups to design a lesson about comparing fractions. Feedback might identify a mismatch between a visual model and the intended concept. Reviewers would check whether the comment correctly locates the mismatch and suggests something the group can implement. Students would retain their original plan and explain how the revision changes the learning opportunity. A discussion about the exact teaching decision could reveal more than a generic judgment that the feedback was fluent, friendly, or sufficiently detailed.
Evaluation should also leave room for differences to appear. If almost every project receives a score near the top, a team could add a separate transfer task or a more discriminating criterion while preserving a fair grading process. It should decide in advance what difference would matter educationally, rather than treating an inconclusive statistical comparison as equivalence. Time spent checking comments, errors requiring correction, and students’ ability to justify their lesson choices would be useful additional observations in such a local pilot.
The teacher’s role in this proposal includes setting the standard, examining difficult cases, and deciding when a student needs dialogue beyond a written comment. An AI system could be evaluated as one contributor within that arrangement. Its usefulness would depend on how reliably it supports the intended task under local conditions. The published comparison gives institutions a reason to investigate this possibility carefully, while the next independent performance and the quality of human oversight remain questions for local evidence.