Overfitting and Regularization
Why a model can fit its training examples too closely, and how constraints and independent validation can support performance on new cases.
Sumber
Ringkasan pelajaran lengkap
Overfitting occurs when a model learns patterns that help explain its training data but do not transfer reliably to new data. These patterns may include noise, accidental associations, or details specific to a small sample. A model can therefore become more accurate on the examples it has seen while becoming less useful for future cases. The target of learning is generalization, not a perfect recollection of the development dataset.
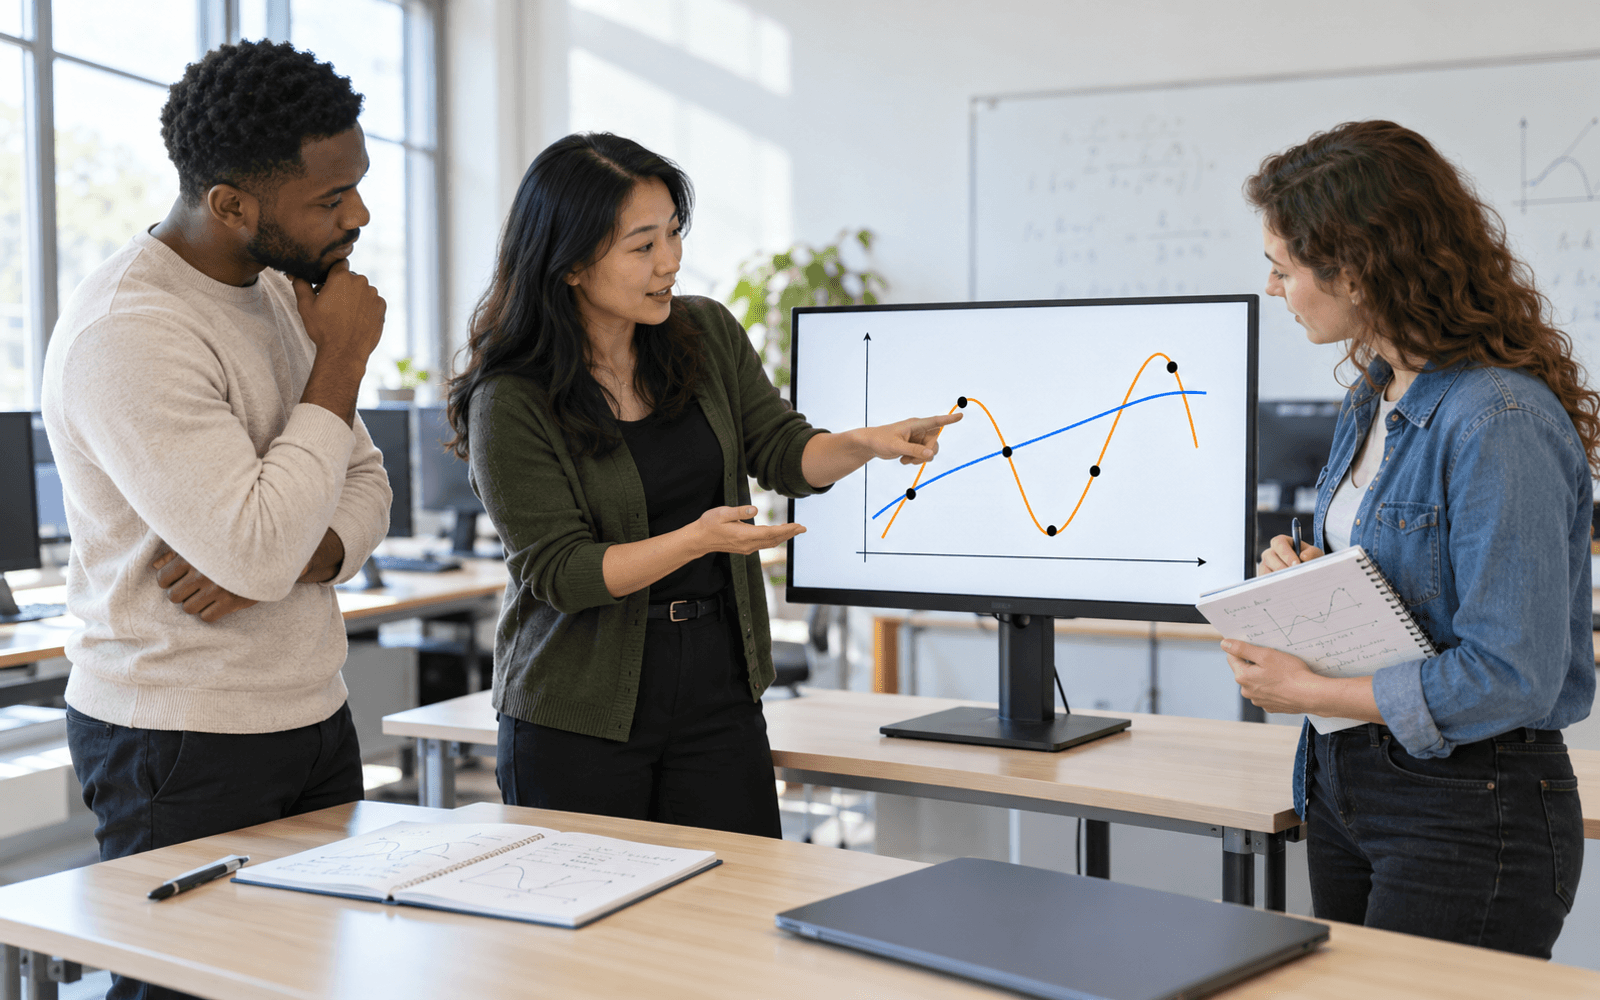
Imagine estimating the relationship between practice time and performance using a small fictional class dataset. A very flexible curve can weave through almost every recorded point, including unusual observations caused by measurement error or an interrupted lesson. A simpler curve may miss some training points yet predict a new learner's result more accurately. Neither curve establishes that practice time causes the result. The example illustrates fitting and prediction, while causal interpretation requires additional assumptions and study design.
Regularization introduces preferences or constraints that discourage some kinds of overly complex fit. In a linear model, an L2 penalty discourages large coefficients, while an L1 penalty can set some coefficients to zero. Other approaches restrict tree depth or stop training before the model increasingly fits idiosyncratic detail. These methods encode assumptions about what solutions are likely to generalize. They are not magic corrections, and stronger regularization is not always better.
Too little flexibility can produce underfitting: the model misses an important relationship even in the training data. The practical task is to find an appropriate balance for the problem and evidence available. Compare training and validation performance as a relevant setting changes. A large training advantage can suggest overfitting, while poor performance on both may suggest insufficient model capacity, weak features, label problems, or a task that the available data cannot support. These patterns are diagnostic clues rather than automatic diagnoses.
For an educational resource classifier, a developer might compare several tree depths using separate development folds. The simplest tree may miss meaningful combinations of features; the deepest may memorize rare formatting details. Select a setting based on suitable validation evidence and then evaluate the chosen workflow on untouched cases. Fitting preprocessing and selecting features must occur within the training portion as well. Regularization cannot compensate for test leakage, a misleading target label, or an evaluation that ignores new schools or later terms.
Educators can explore the idea by fitting simple and flexible curves to a small synthetic dataset, revealing new points only after predictions are recorded. Ask which model appeared best before the reveal and what changed afterward. Discuss the uncertainty that remains when data are scarce. Regularization is a disciplined way of limiting what a model can infer from finite evidence. Its value must be demonstrated on relevant new cases, with attention to subgroup errors and the consequences of using predictions. A lower training score can be acceptable when it accompanies more dependable performance where the model will actually be used.