Model Quantization
Quantization represents model values with fewer bits. It can reduce memory and improve deployment efficiency, but the effects on accuracy and speed depend on the method, hardware, and task.
Sumber
Ringkasan pelajaran lengkap
A neural network contains many numerical values. Storing and manipulating those values uses memory, computing time, and energy. Model quantization reduces the precision used to represent some of them. A system might replace higher-precision values with eight-bit or four-bit representations, together with the information needed to interpret those representations. This changes numerical storage and computation; it does not necessarily reduce the number of model parameters.
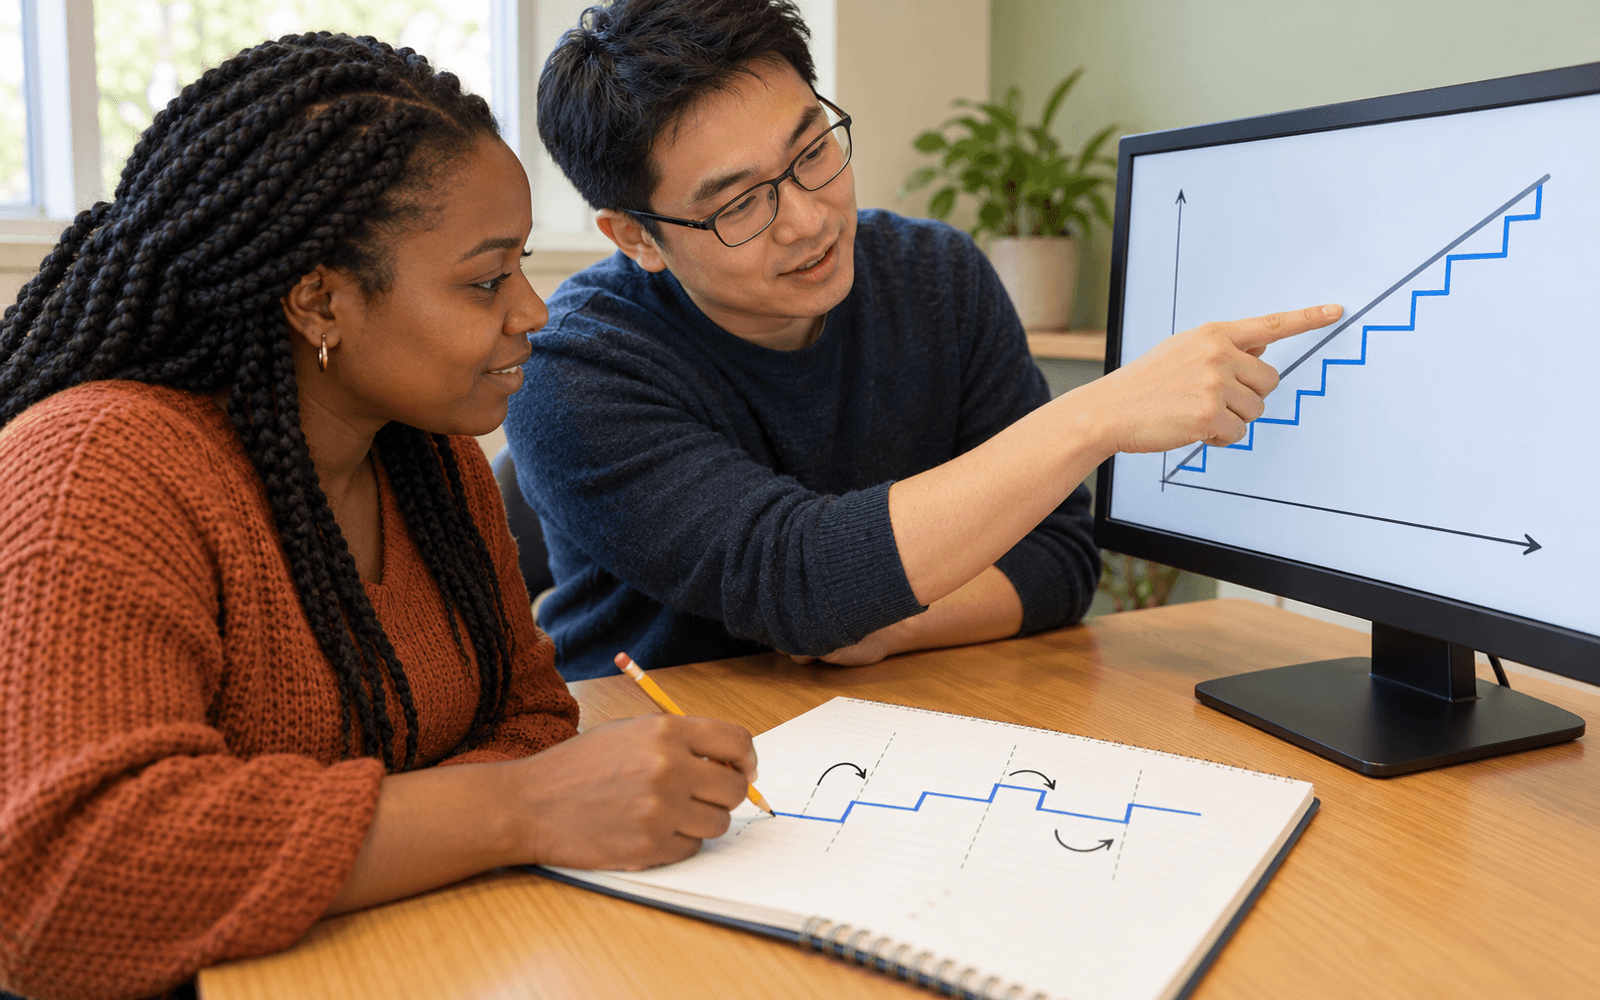
A simple analogy is recording a measured length to the nearest centimetre instead of the nearest millimetre. The record becomes less precise, and some different measurements now share a value. Neural-network quantization similarly maps a range of values onto a smaller set of representable levels. Scale factors, and sometimes zero points, connect the stored values with their approximate numerical meaning. Real methods can be more sophisticated than uniform rounding, particularly when important values have unusual distributions.
There are two broad routes. Post-training quantization transforms an already trained model, often using representative examples to determine suitable ranges. Quantization-aware training exposes a model to the effects of reduced precision during training so it can adapt. Research on integer-only inference and on LLM.int8 shows why both numerical design and hardware implementation matter. Some methods retain higher precision for selected values or operations. A label such as eight-bit therefore does not fully describe the computation.
Suppose a college wants a local language assistant on a classroom computer with limited memory. Staff compare a reference model with a quantized version using the same prompts and controlled settings. Their test includes short explanations, numerical comparisons, multilingual instructions, refusal behaviour, and longer conversations. They record whether each version fits in memory, how quickly it responds, and whether the answers satisfy a teacher-written rubric. The comparison should use the actual computer because an optimization that helps one processor may offer little advantage on another.
Memory savings for model weights do not imply identical savings for the entire application. Activations, temporary buffers, stored conversation information, and other software still consume resources. Conversion overhead or unsupported operations can reduce a hoped-for speed improvement. More aggressive compression may alter difficult or rare behaviours even when an average benchmark changes little. Neither smaller storage nor a familiar benchmark establishes suitability for feedback, assessment, or other consequential educational uses.
An accessible teaching activity uses a number line to round a small set of values at different resolutions. Learners identify which distinctions disappear and compare the accumulated result of a short calculation. They then connect the exercise to a model evaluation plan, while recognizing that real networks are much more complicated. Quantization is useful when its resource benefits are demonstrated and its errors remain acceptable for a defined purpose. Keep the original model version, conversion method, evaluation examples, and deployment settings recorded so that a later change can be assessed fairly.


