Label Noise and Annotation Agreement
Label noise can reflect mistakes, unclear constructs or legitimate disagreement. Reliable annotation combines explicit guidance, interpreted agreement measures and documented review without treating model disagreement as proof of human error.
Sumber
Ringkasan pelajaran lengkap
Label noise occurs when the recorded labels used to train or evaluate a model do not reliably represent the intended target. Some errors are straightforward: a response is attached to the wrong student or a category is selected accidentally. Others arise because the task is ambiguous, instructions are incomplete, or reasonable annotators interpret evidence differently. Improving labels therefore requires understanding disagreement rather than automatically treating it as careless work.
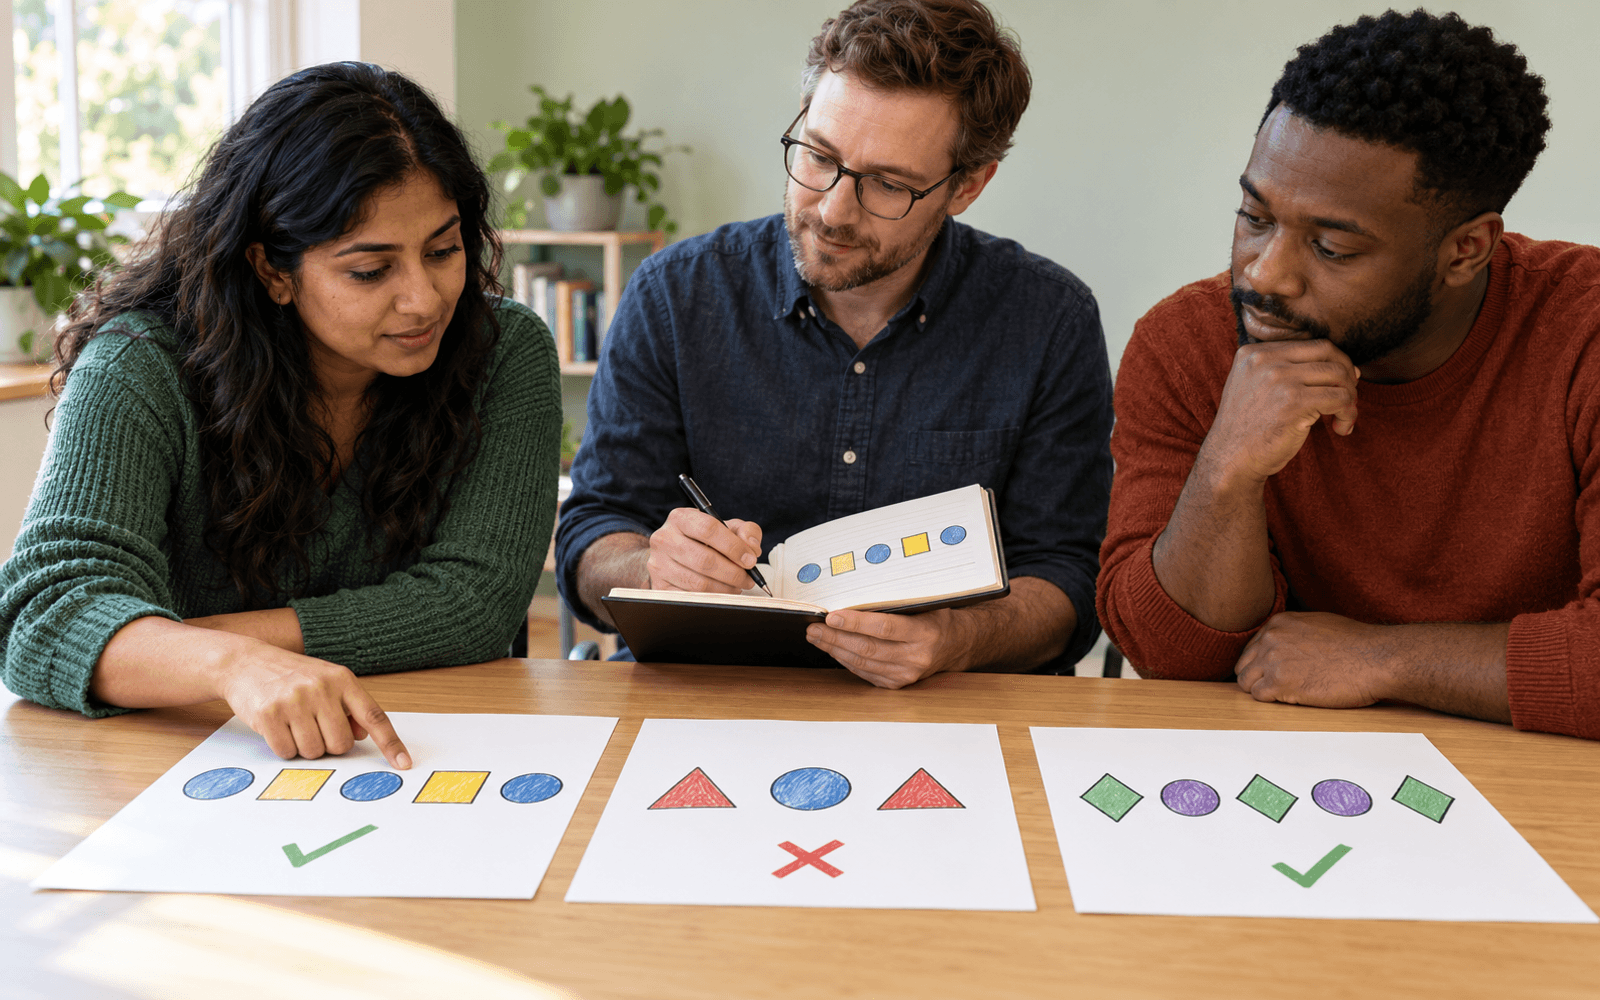
An annotation scheme defines what is being labeled, the available categories, and the evidence needed for each decision. If educators label written explanations as correct, partly correct, or incorrect, they must decide how to treat missing reasoning, contradictory statements, and alternative valid methods. Without shared guidance, annotators may apply different constructs while using the same category names. A model trained on those labels can learn inconsistent or unintended patterns.
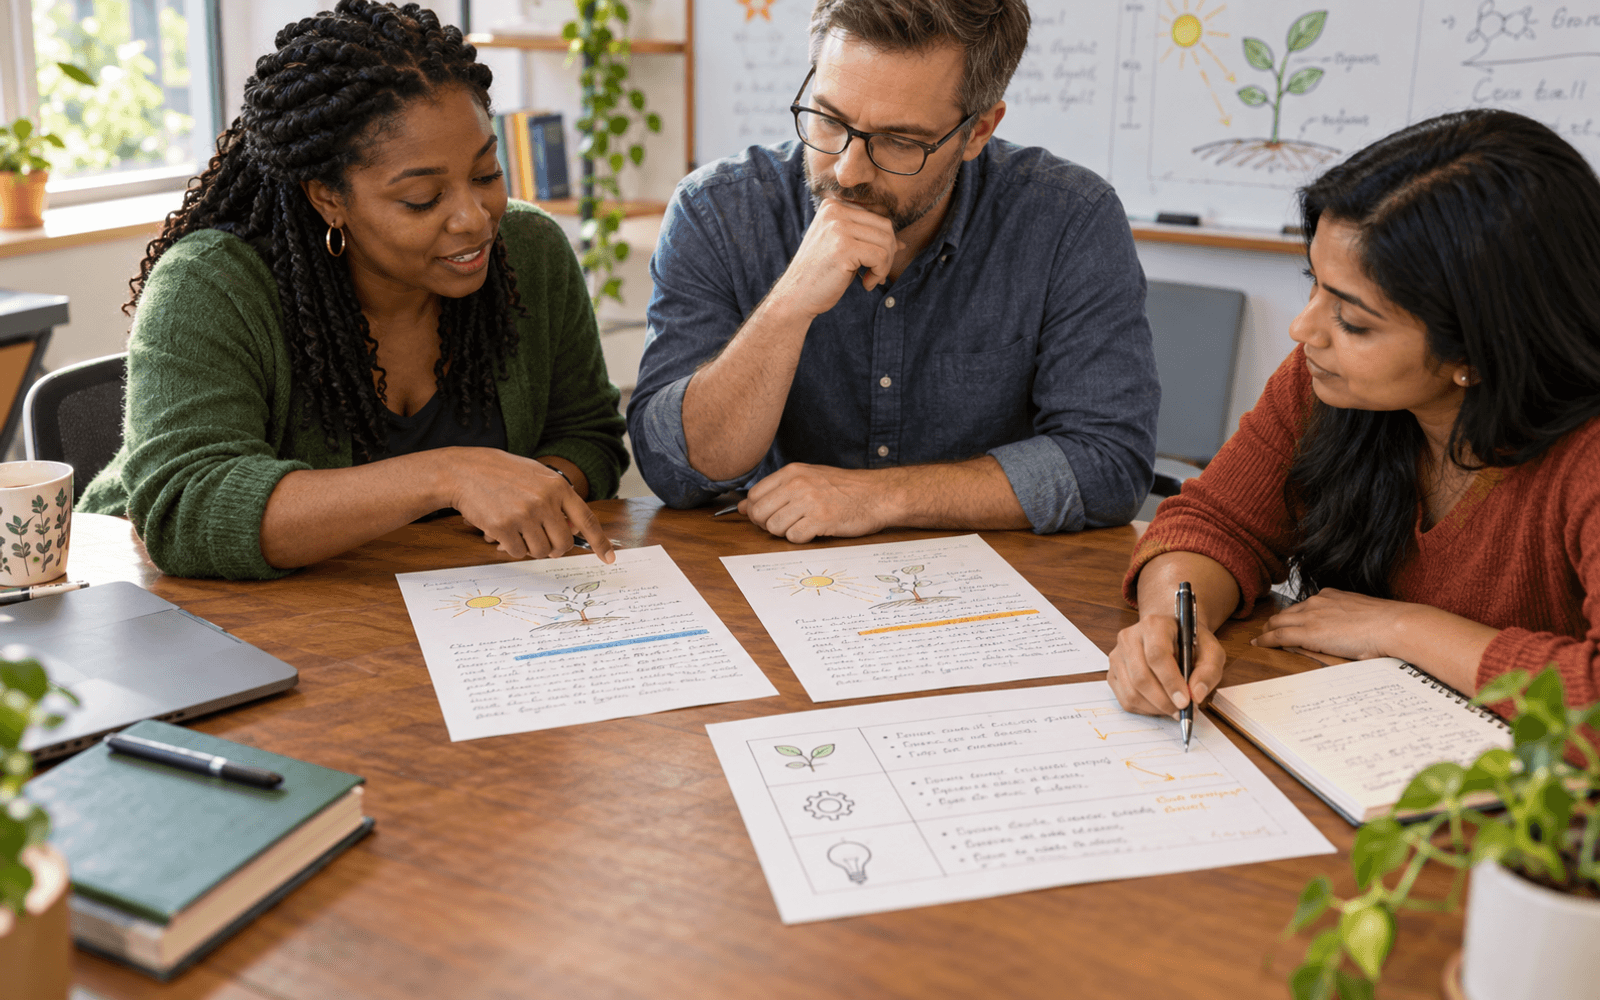
Imagine two teachers judging a science answer that gives the right conclusion but an inaccurate explanation. One selects correct because the final statement matches the answer key. The other selects partly correct because reasoning is central to the task. Their disagreement exposes a problem in the specification. Adjudication should clarify what the assessment intends to measure and record the reason for the final decision. Silently taking a majority vote would hide the unresolved distinction.
Agreement statistics summarize consistency but require interpretation. Raw agreement reports how often annotators match. Cohen's kappa compares two annotators' agreement with an expected level based on their category frequencies. It can change when category prevalence changes, so a single threshold should not determine whether an entire dataset is trustworthy. Examine a confusion table, category definitions, sample composition, and the disagreements that have educational consequences.
Model-assisted methods can help prioritize suspicious labels. Confident learning, developed by Northcutt and colleagues, uses estimated probabilities and assumptions about label noise to identify possible issues. These flags are candidates for review, not proof that a human annotation is wrong. A model may disagree because it has learned a biased shortcut or because the example represents a rare but valid case. Preserve the original label and the rationale for any correction.
Some tasks contain legitimate variation rather than one recoverable hidden truth. Interpretations of tone, relevance, or open-ended quality may depend on context and perspective. Research on CrowdTruth argues for treating disagreement as informative in suitable annotation tasks. Teams can retain multiple judgments, uncertainty, or distributions where these better represent the construct. That decision should be explicit; not every task benefits from collapsing complexity into one hard label.
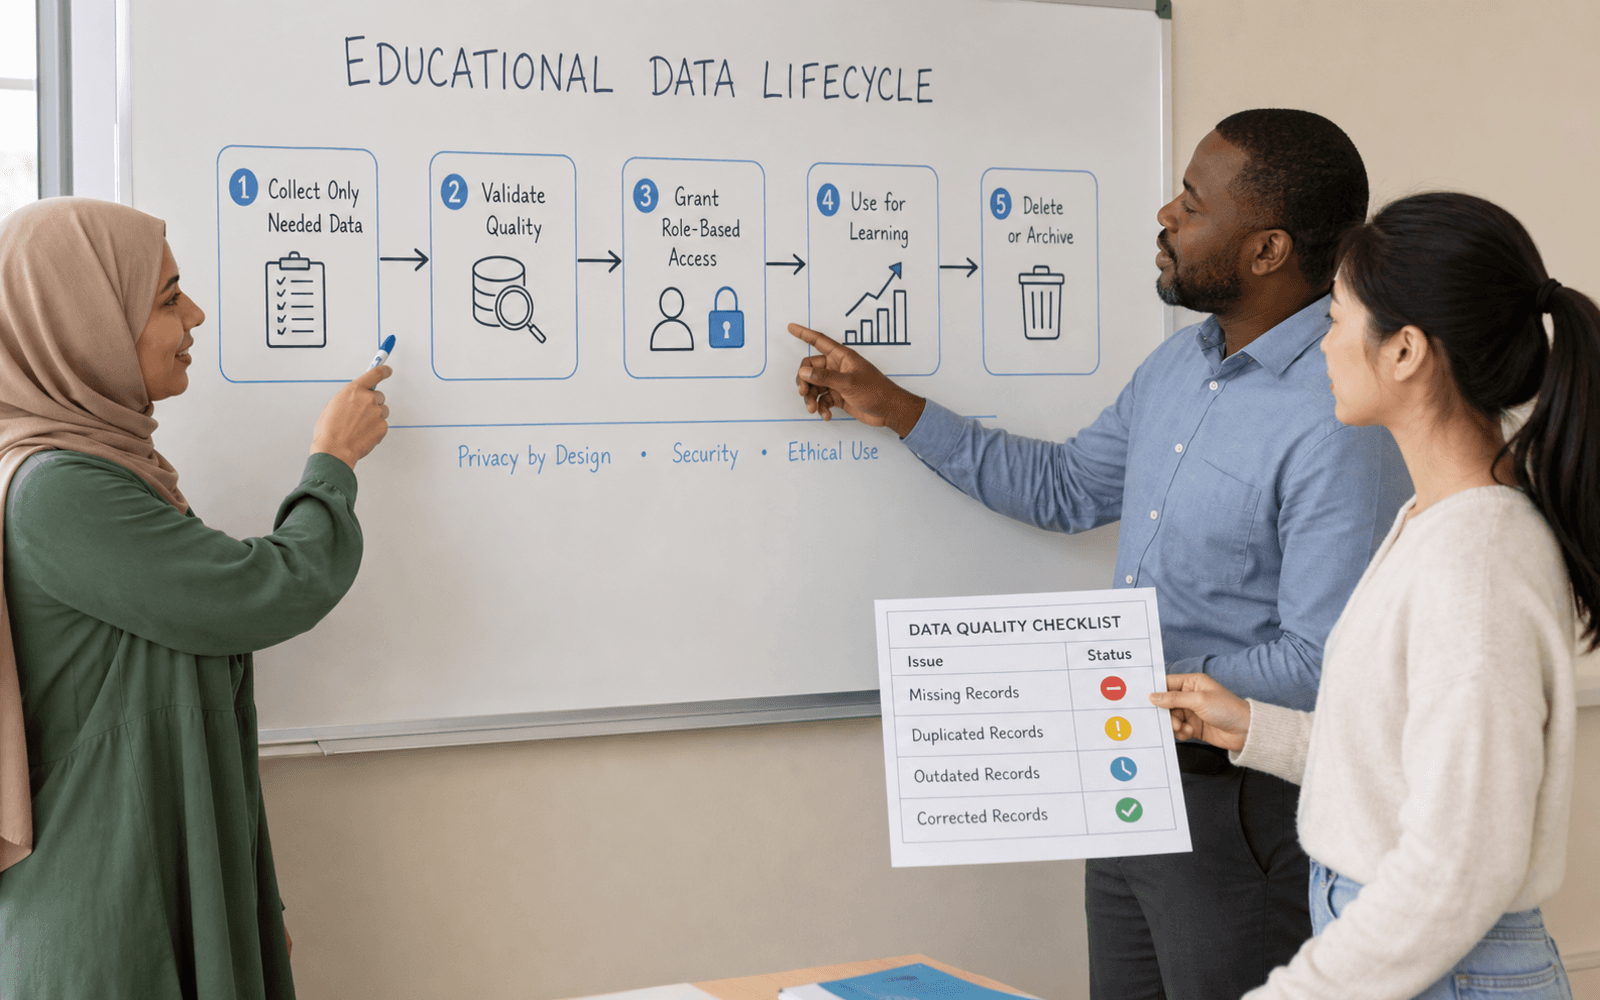
A sound workflow pilots instructions, trains annotators with examples, double-codes a representative subset, reviews disagreements, and versions revisions. Keep evaluation labels independent from model-driven changes that could make the test favor the system under study. Report who annotated, what guidance they used, and what uncertainty remains without exposing sensitive identities. Label quality improves when the dataset reflects a clear educational question and preserves the evidence behind its judgments.