Machine Unlearning
Machine unlearning seeks to remove specified training-data influence from a model. Deleting a record, suppressing an answer, and demonstrating successful unlearning are different operations.
स्रोत
पूरा पाठ सारांश
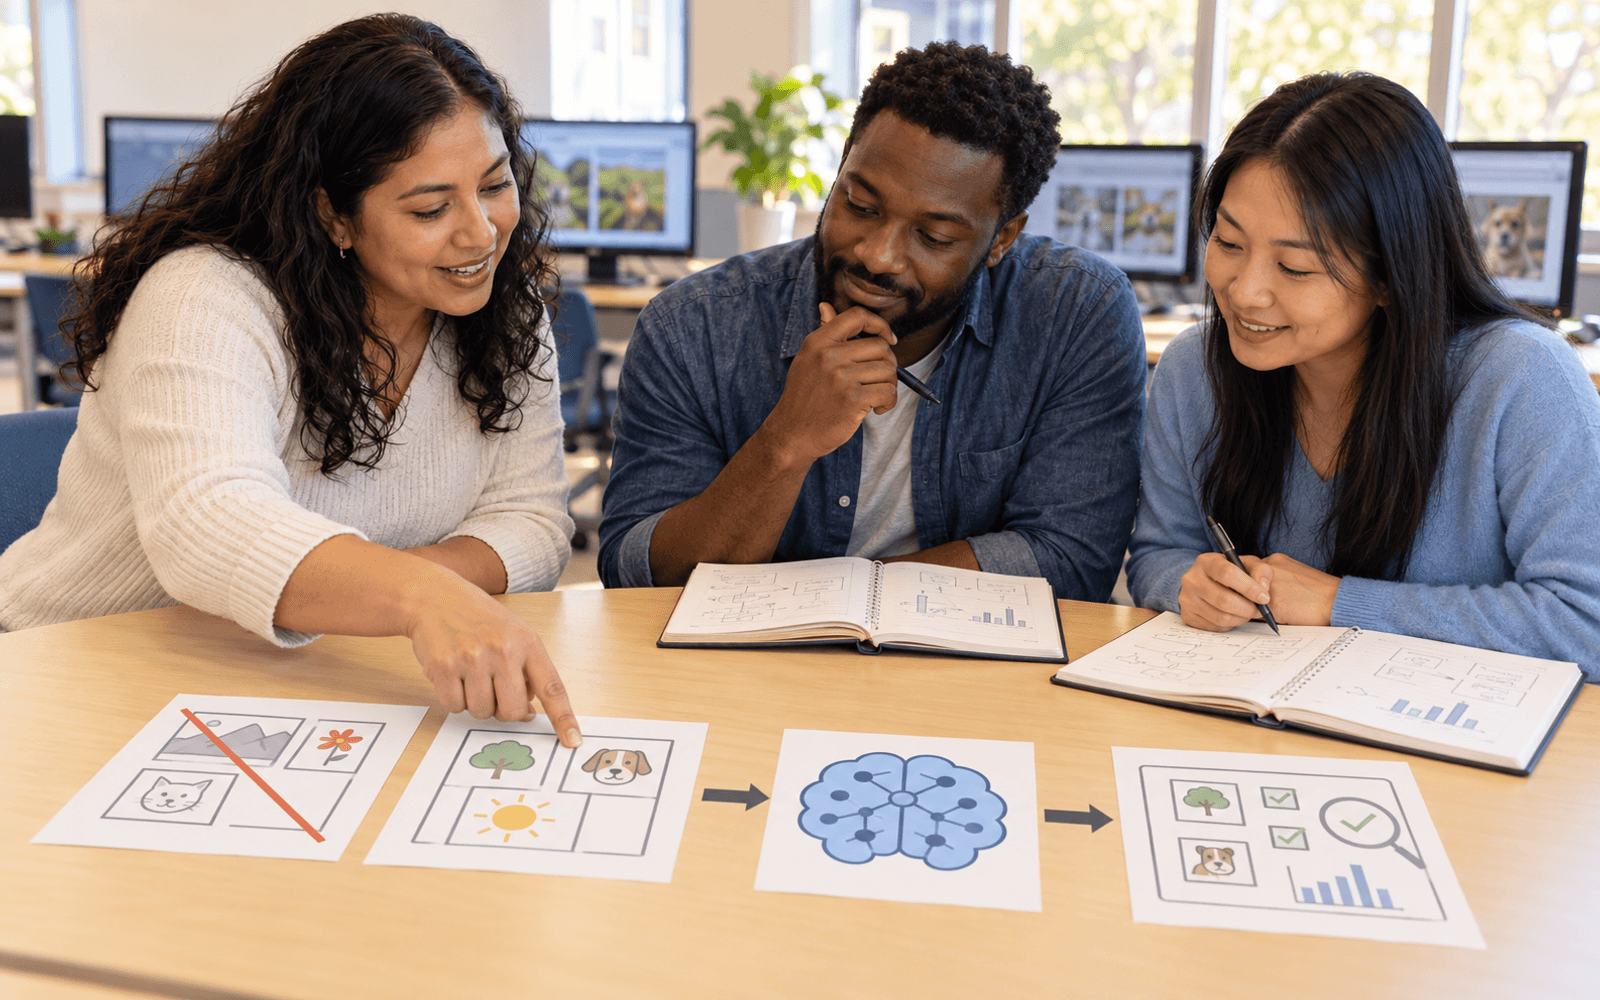
A learner's record is removed from a training database. Does a model previously trained on that record also forget it? Usually, deleting the stored record does not automatically reverse the changes made during training. Machine unlearning studies methods for removing specified training-data influence from an already trained system. The question is technically different from deleting a file, restricting access, or asking a chatbot not to mention a topic.
A natural reference point is retraining the model without the data to be removed. That may be expensive, and randomized training can produce different models even from the same dataset. Unlearning research therefore needs explicit definitions of what it means to match the appropriate retraining outcome. Some methods provide formal guarantees under stated assumptions; others offer approximate empirical changes. These categories should not be presented as equivalent simply because both are called unlearning.
System design can make removal easier. Bourtoule and colleagues proposed a training approach that divides work into shards and slices so that affected portions can be retrained more selectively. Other research examines efficient deletion for particular learning algorithms. Such methods illustrate why preparation and model structure matter. A technique demonstrated for one algorithm or dataset cannot automatically be assumed effective for every large language model.
Imagine a college running a small classifier trained on consented discussion posts. A participant later withdraws a set of contributions under the project's agreed process. The team identifies the original records, derived examples, training versions, and affected model artifacts. It evaluates whether its chosen deletion method is applicable or whether full retraining is needed. A replacement model is then checked for both the intended removal criterion and continued performance on legitimate tasks. Copies, caches, evaluation sets, and backups require their own handling according to the established retention policy.
Evaluation is difficult. A model's failure to reproduce a phrase does not prove that all influence has disappeared. Conversely, a model may still know a fact because it appeared in other legitimate data. Membership tests and extraction attempts can provide useful evidence but are not universal proofs of forgetting. The test must correspond to the claim being made, including whether protection concerns particular examples, a person's contributions, or a broader category of information.
For educators procuring or building AI systems, unlearning should be discussed before sensitive data enter training. Ask which models use the data, how contributions can be located, what removal mechanism exists, and what evidence supports it. Do not treat a chat interface's delete button as proof about model weights. A classroom exercise can trace a fictional record through a training pipeline and mark which artifacts require action after withdrawal. This clarifies the practical lesson: responsible removal combines data lineage, an appropriate technical method, verification, and communication about the limits of the achieved result.