Preprint: TutorCaseBench separates recognizing a strategy from responding to a learner
Yeon Su Park, Chanyoung Park, Tae Soo Kim, Seungju Kim, Hyunwoo Kim, Daho Jung, Jinsung Yoon, Juho Kim
arXiv preprint
Résumé de 500 mots
TutorCaseBench, a preprint submitted on October 22, 2026, evaluates whether language-model tutors can respond appropriately to specific learner challenges. Yeon Su Park and colleagues build scenarios, dialogues and rubrics from qualitative case studies in education and related fields. The benchmark contains 923 constructed dialogues, with separate open-response and multiple-choice tasks. Across eleven models, the authors find a gap between selecting an appropriate strategy and generating a response that satisfies case-specific criteria.
These are benchmark results from constructed cases, not observations of the evaluated tutors helping actual students. The construction and scoring pipeline also uses language models, with human validation of components. Such checks support scrutiny of the benchmark but do not turn its scores into evidence of classroom effectiveness or suitability for a particular learner. The work is useful as a preprint about evaluation design, with that boundary kept explicit.
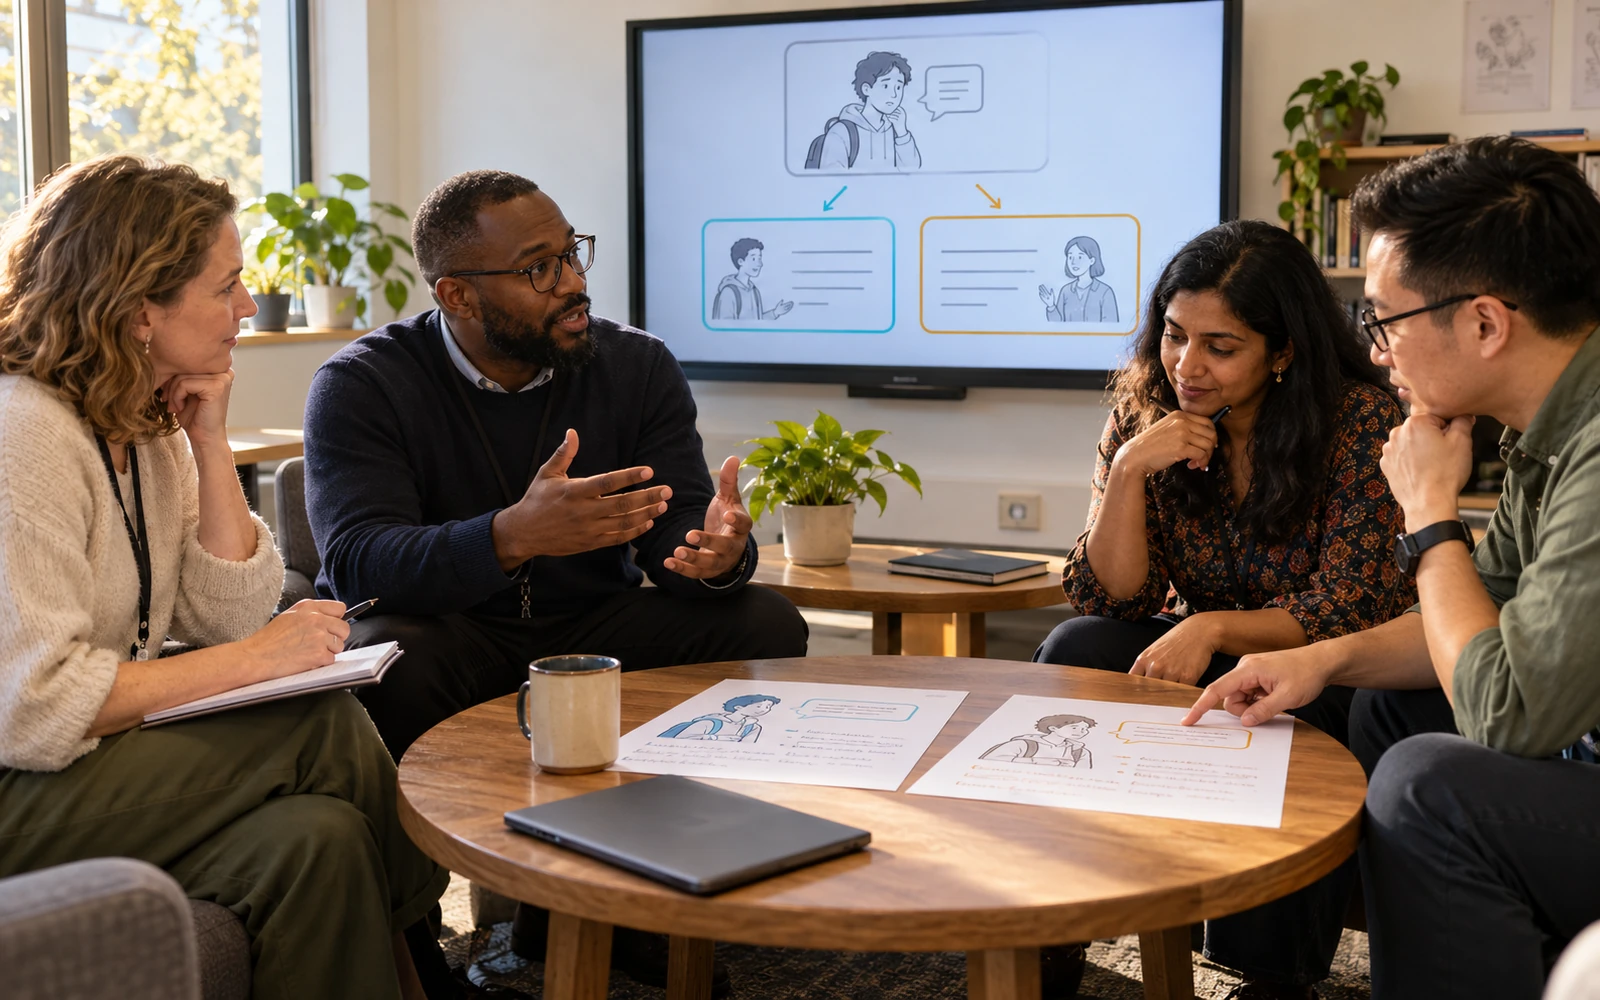
For teacher education, the distinction between naming a strategy and using it well is immediately recognizable. The following review exercise is an AIEDHK proposal. A group could begin with a fictional learner who stops participating during a difficult problem. Participants would list several possible explanations, including unclear instructions, uncertainty about the concept or an unhelpful interaction. They would avoid deciding what the behavior means before asking for more evidence.
Next, each participant would write the tutor's actual next sentence. A general recommendation such as encourage the learner would not be sufficient. The sentence would need to fit what is known, invite a useful response and preserve the learner's dignity. Peers could compare the drafts and explain which details of the case informed their wording. This makes it easier to see when a supposedly supportive response introduces an assumption that the case does not justify.
The group could then inspect an AI-generated reply using the same criteria. Does it respond to the learner's question? Does it offer an appropriate choice or a manageable next step? Does it promise something the tutor cannot provide? Reviewers would identify the relevant words in the response and describe what they would change. An attractive tone would be one consideration, while the fit between evidence and action would remain central.
A further exercise could change one important detail in the case and ask whether the response should change. For example, a learner might already understand the procedure but be unsure what the task is asking them to explain. A tutor that repeats the same instructional move across both versions may be following a general script rather than adapting to the available evidence. The comparison creates a specific question for further testing.
Any classroom pilot would require its own review process and appropriate human support. A benchmark can reveal weaknesses and help organize test cases, but it cannot establish that an assistant should independently handle every difficult interaction. The practical contribution is a more demanding standard for evaluation: a tutor needs to show how its chosen words fit the situation, not merely demonstrate that it can recognize the name of a plausible strategy.