Progressive mind maps strengthened programming performance beyond chatbot assistance alone
Xindong Ye, Wenyu Zhang, Yuxin Zhou, Xiaozhi Li, Qiang Zhou
Humanities and Social Sciences Communications
Résumé de 500 mots
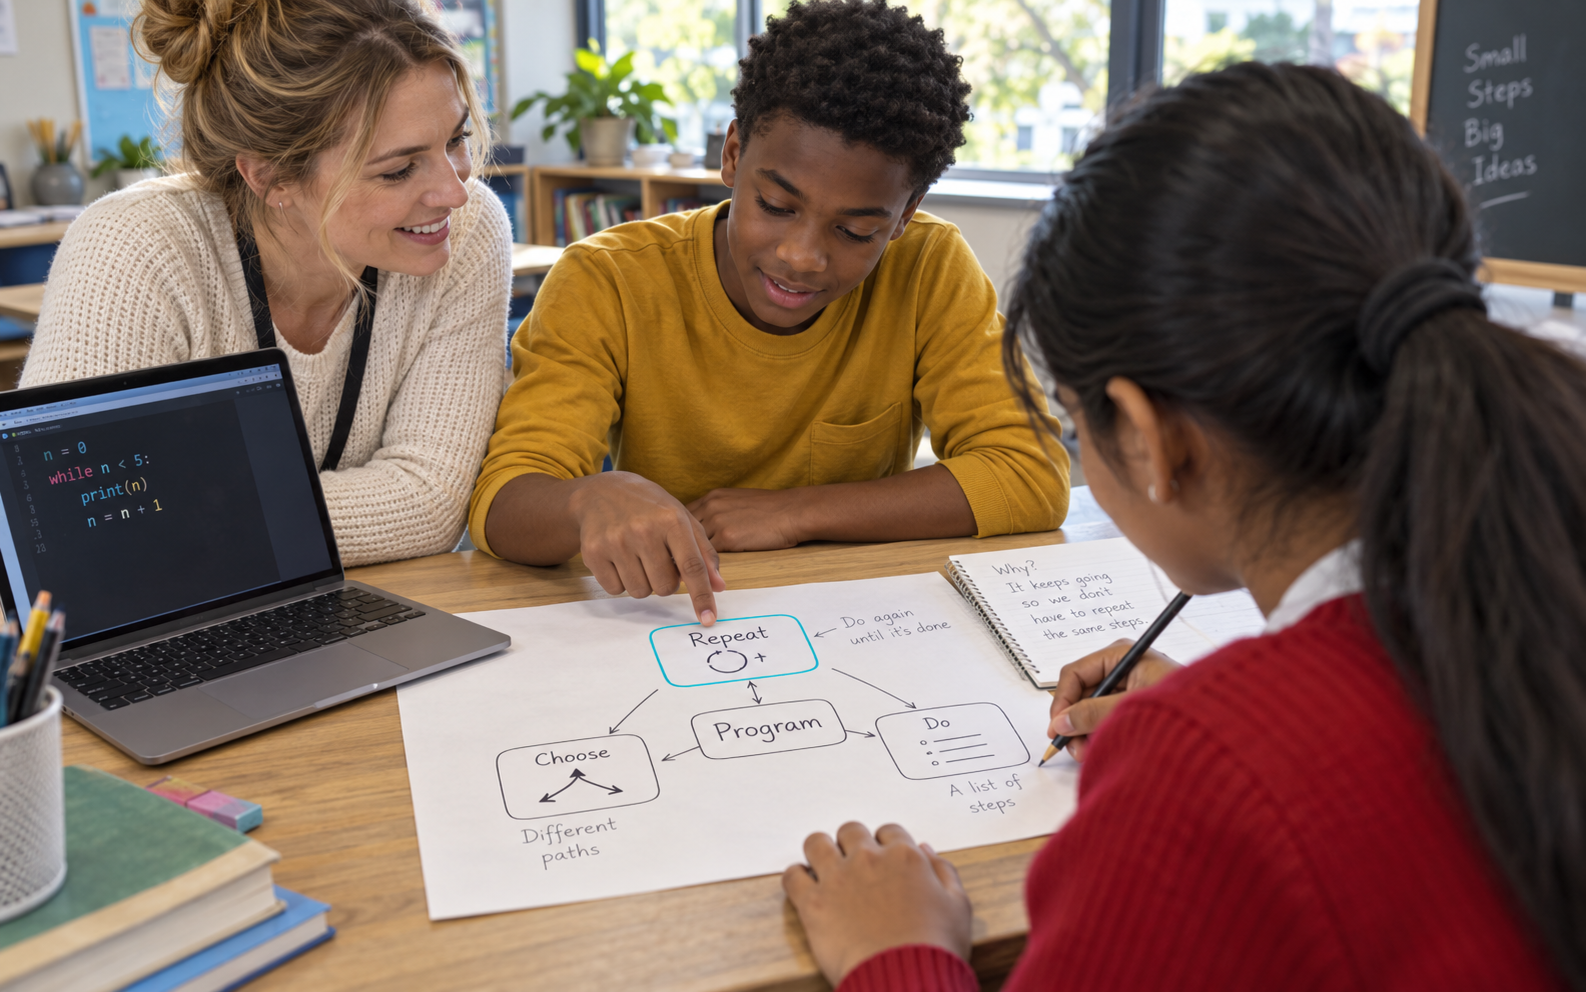
A chatbot can answer a programming question without helping a beginner organize the problem that generated it. Xindong Ye and colleagues investigated whether mind maps could provide that missing structure. Their approach asked learners to make the sequence and relationships in a solution visible before and during coding. The comparison was between different ways of supporting chatbot use, not between access to AI and no access. This makes the study relevant to the instructional design surrounding an assistant rather than a simple technology-adoption decision.
The quasi-experiment involved 111 seventh-grade pupils from three classes at one junior high school in southeastern China. One class of 36 used progressive mind-map scaffolding with a GPT-4-based chatbot. Another class of 36 constructed its own maps with chatbot support. The remaining 39 pupils used chatbot assistance without the mapping scaffold. The same teacher taught Python concepts across an eleven-week course, including preparation and assessment. The differentiated intervention occupied six weeks, so the overall course duration should not be confused with six weeks of identical experimental exposure.
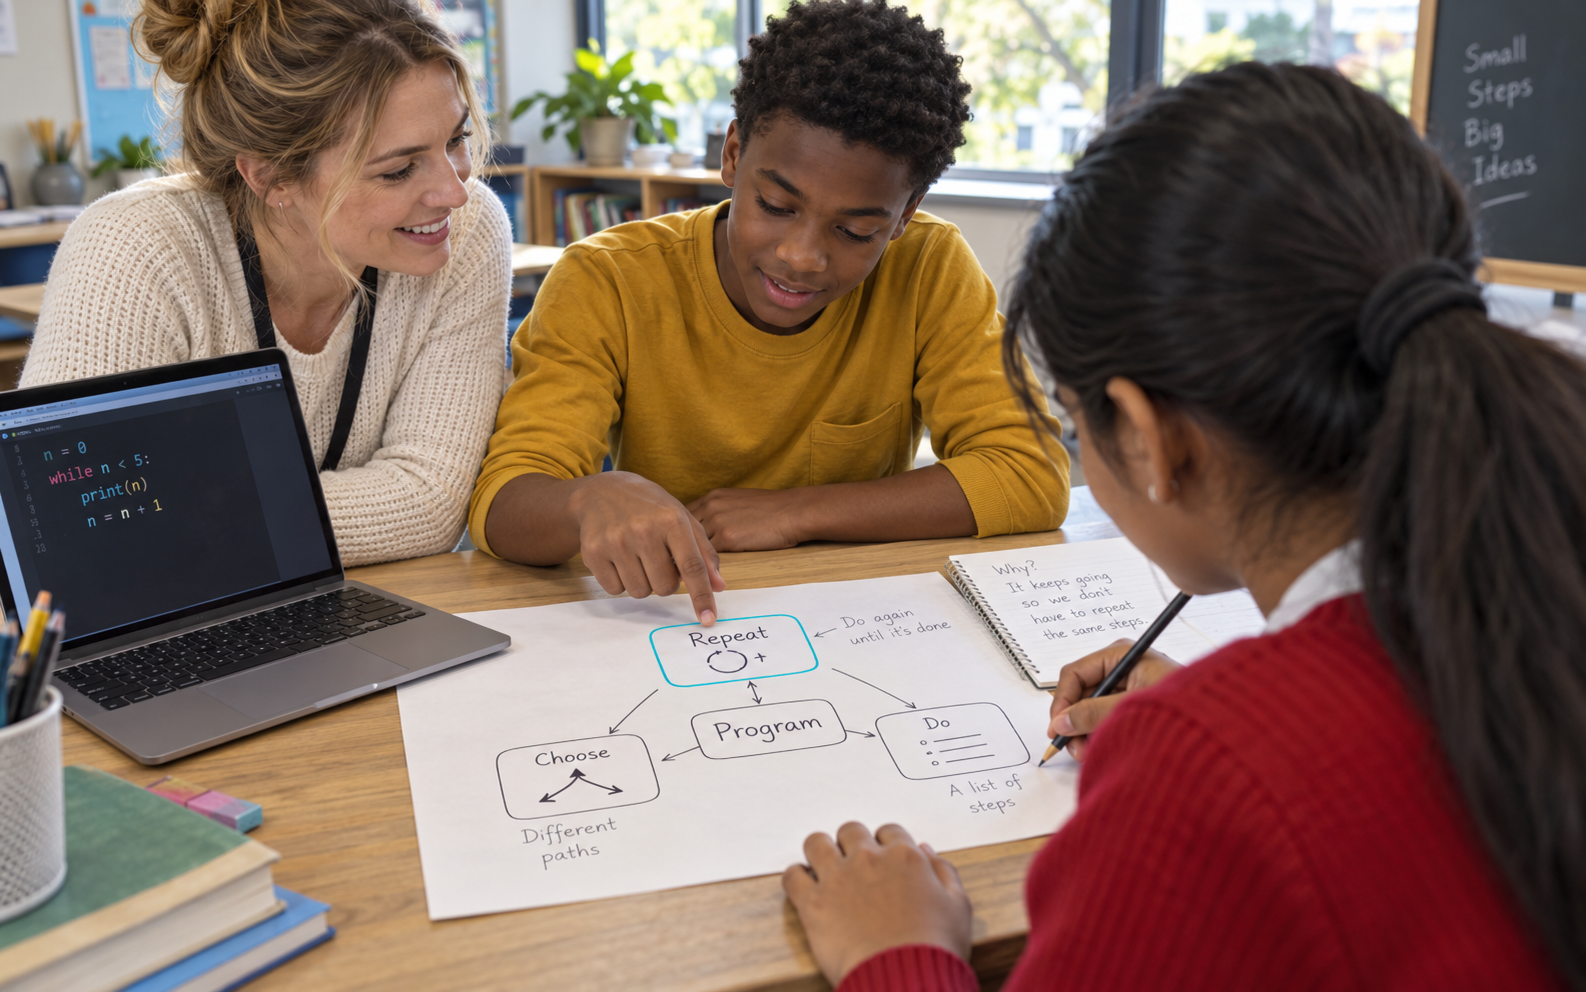
The progressive approach began with teacher-prepared maps containing gaps. Learners then moved to maps supported by prompts before constructing maps independently. Across the lessons, students clarified a problem, analyzed it, planned a solution, wrote and debugged code, and reflected on the result. The teacher monitored the process, including whether pupils simply generated code. The intended relationship was reciprocal: maps helped students formulate more focused requests, and chatbot feedback could help them revise the represented solution.
The progressive-map group had the highest programming post-test score, outperforming the self-constructed-map group by 5.11 points and the chatbot-only group by 9.31 points. The self-constructed-map group also exceeded the chatbot-only group. Overall computational-thinking questionnaire scores favored the mapped conditions, but the pattern was not uniform across subscales. Algorithmic thinking and cooperation did not differ significantly between groups. Programming self-efficacy improved within groups, but its post-test comparison was not significant. Those distinctions prevent a general claim that the scaffold improved every aspect of programming learning.
The study has several limits. Only three intact classes participated, so class differences cannot be ruled out by similar pre-test averages. The computational-thinking measure was a self-report scale rather than a direct demonstration of every named skill. The authors also noted limited assessment of the maps themselves and of students' interactions with the chatbot. Without those process measures, it is difficult to determine which parts of the scaffold mattered most. The study did not establish delayed retention or independent transfer to a substantially different programming problem.
For AIEDHK, the practical opportunity is to make planning a visible part of AI-supported coding. A teacher could ask students to draw a short decision structure, explain a branch and predict a result before requesting help. Support could gradually be reduced as the learner becomes able to plan independently. Evaluation should include unfamiliar code-tracing or debugging tasks without the assistant and should inspect how the map changes. These are proposed extensions beyond the experiment. The useful design principle is structured problem representation with fading support, while keeping tested programming performance distinct from self-reported confidence and broad claims about thinking skills.