Cross-Validation for Small Datasets
How cross-validation reuses limited data for development and evaluation, and why it cannot remove the uncertainty created by a small sample.
Sources
Résumé complet
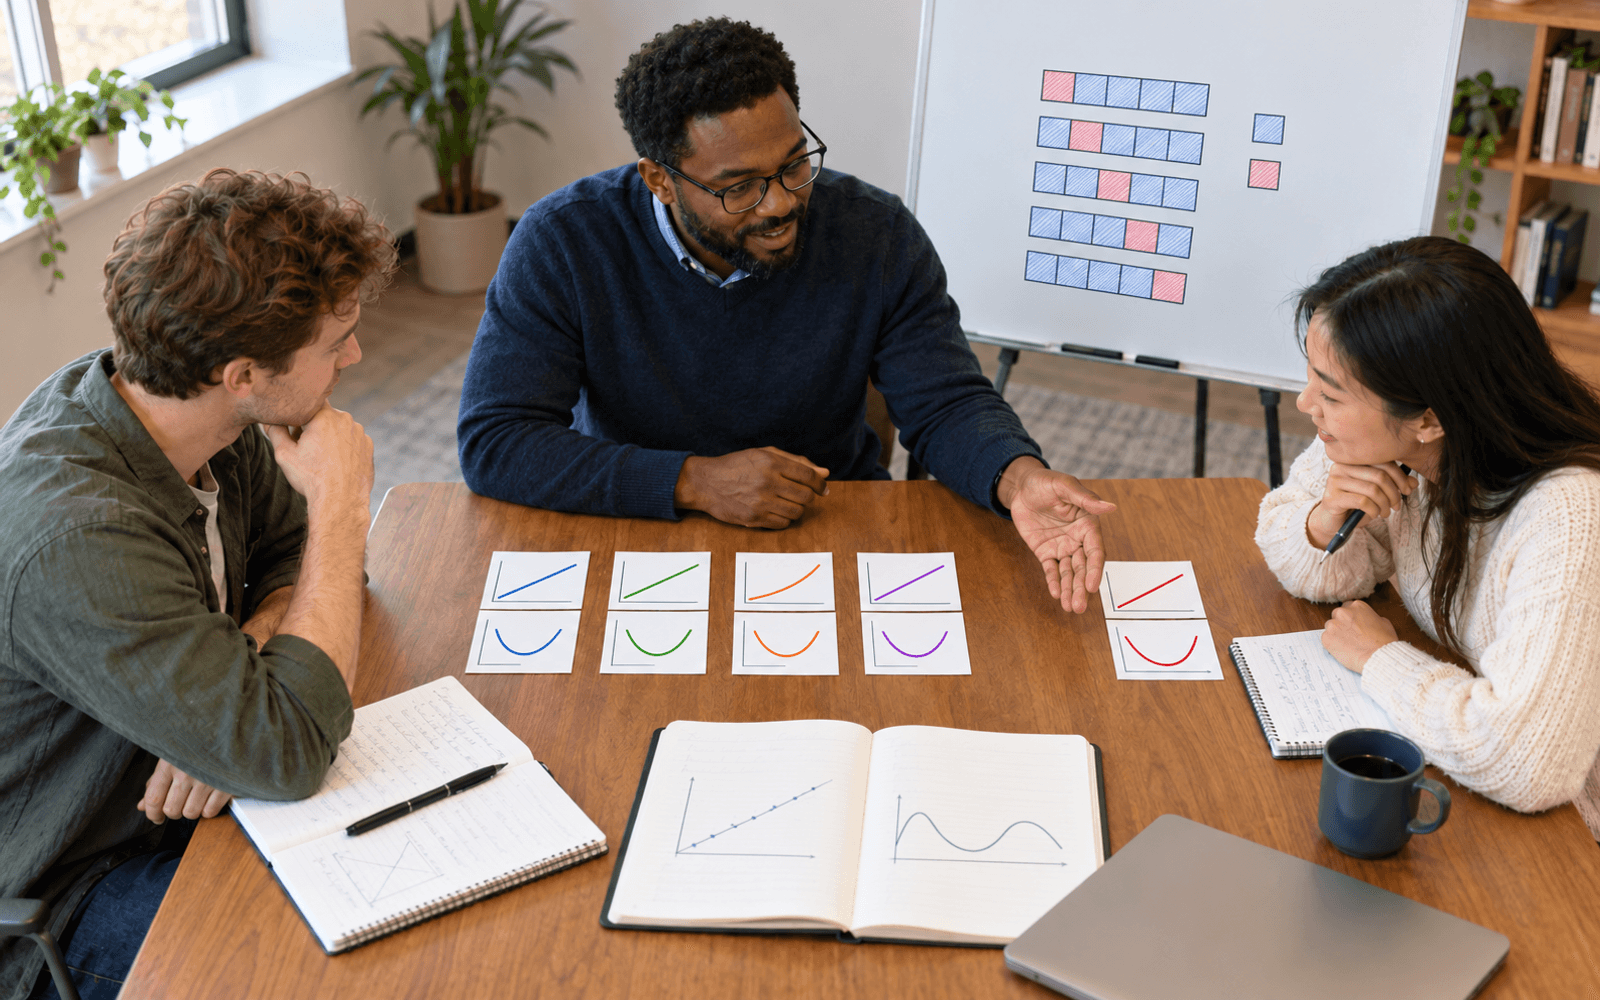
Cross-validation evaluates a learning procedure by repeatedly fitting it on part of a dataset and testing it on held-out observations. In k-fold cross-validation, the data are divided into k parts. Each part takes a turn as the validation set while the remaining parts supply training data. The resulting scores provide evidence about performance across these splits. They do not create new independent observations or turn a small dataset into a large one.
The choice of split must match the intended prediction. Imagine 20 learners each contributing ten short written responses. There are 200 rows, but those rows are not 200 independent learners. If the application will assess responses from new learners, keep each person's responses together. A five-fold design could hold out four learners at a time and train on the other sixteen. Randomly distributing all rows would answer a different and often easier question because the model could encounter the same learner during training and validation.
All data-dependent steps belong inside the training portion of each split. This includes missing-value handling, scaling, feature selection, resampling, and model fitting. The validation portion should undergo the transformations learned from training, without influencing them. Otherwise, information leaks across the boundary. Software pipelines can help enforce this sequence, but they cannot decide whether the original grouping or timing assumptions are appropriate for the educational setting.
Model selection adds another layer. If a team tries many settings and reports the best cross-validation score, that score reflects the search as well as the model. Nested cross-validation separates an inner process for choosing settings from an outer process for evaluating the whole selection procedure. Alternatively, a genuinely untouched final test set can evaluate a selected workflow when enough data are available. The important distinction is between evidence used to make development choices and evidence used to judge those choices.
Small samples remain uncertain. Different partitions can produce different scores, especially when classes are rare or individual learners vary substantially. Research by Varoquaux highlights that cross-validation error bars can be underestimated in small-sample settings. Fold scores are not fully independent because their training sets overlap, so their simple standard deviation should not be casually presented as a confidence interval. Repeated cross-validation can reveal sensitivity to splits, but repeated reuse of the same learners does not supply a new population.
Educators reviewing a small pilot should request the number of independent learners and institutions, split rules, model-selection process, and uncertainty—not just an average accuracy. A classroom exercise can compare row-level and learner-level splits in a fictional response dataset and explain why the results answer different questions. Cross-validation is a disciplined way to use limited evidence, not a substitute for representative data or later external validation. When uncertainty remains too large for a consequential decision, the appropriate conclusion may be that the pilot supports further investigation rather than routine deployment.