← Volver a noticias de investigación

#LLM evaluation

LLM evaluation

2 artículos

A learning scientist and two diverse student researchers compare coded learner actions with a structured reasoning map in a university lab
Artículo de congreso2026
Artículo de congreso 98

INSIDE aligned simulated student actions with internal dialogue, but reasoning fidelity remained partial

Rose Niousha, Minwoo Kang, Narges Norouzi

Conference on Language Modeling 2026

Niousha, Kang and Norouzi introduce INSIDE, a framework that fine-tunes LLM student simulators on paired internal-dialogue traces and observable actions across cognitive, affective, and action dimensions. It improved action fidelity and achieved reasoning alignment up to 57.9 percent across evaluated models. The result advances simulator evaluation but leaves substantial mismatch and does not justify replacing trials with real learners.

student simulationinternal dialogueBloom's taxonomy
Leer resumen de 500 palabras →
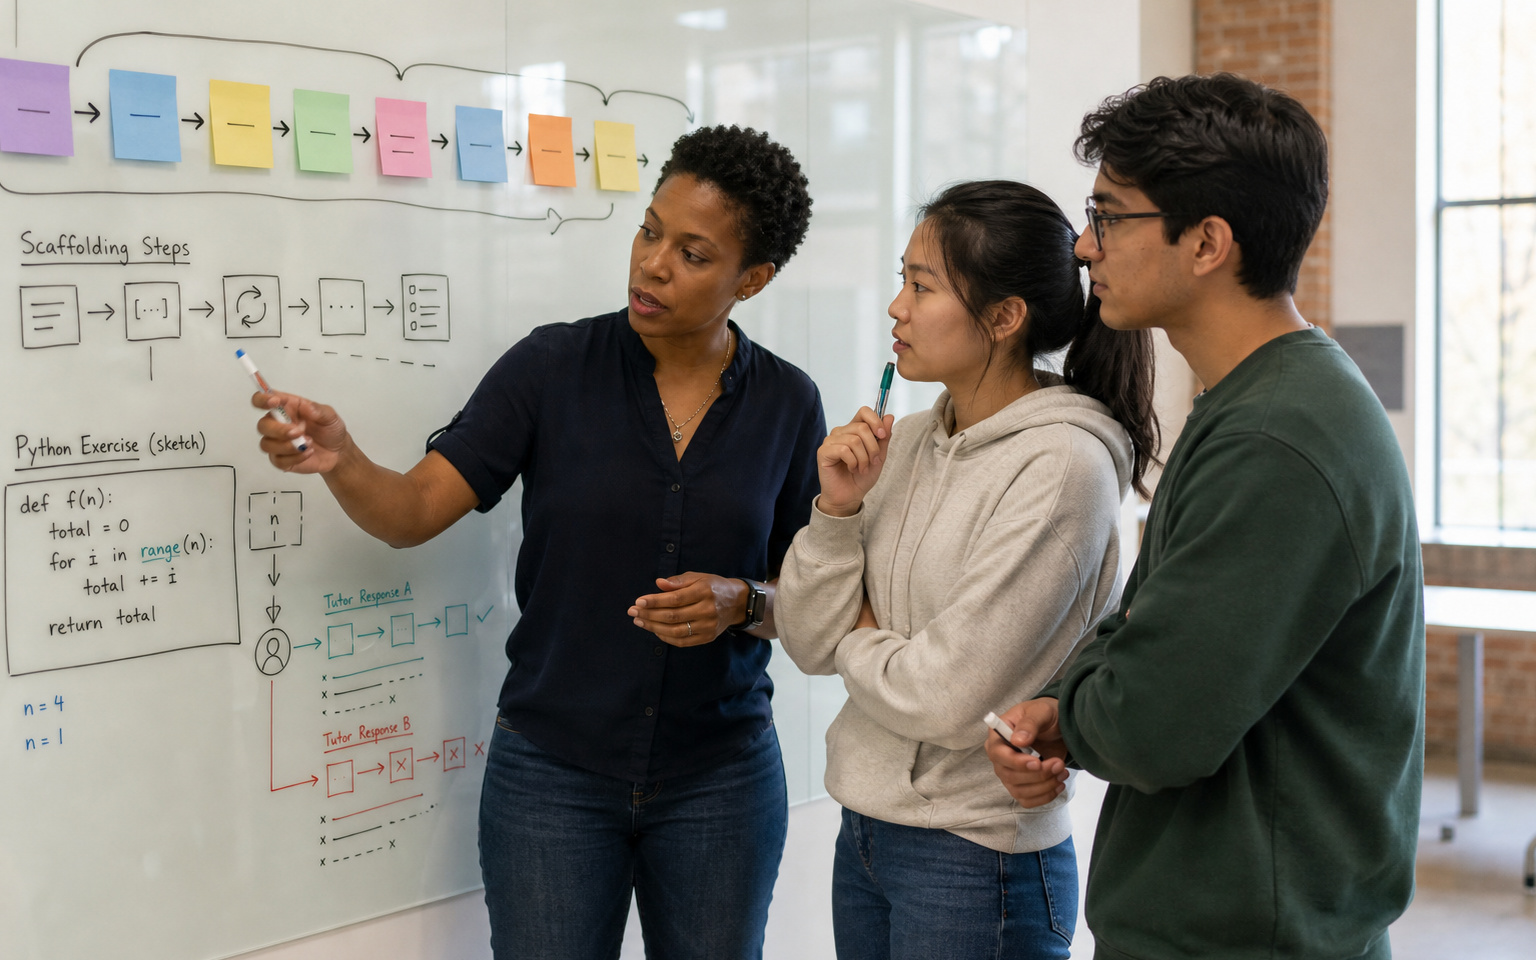
A diverse group of computing students and an instructor compare AI tutoring responses with a prerequisite map and scaffolded Python exercises
Artículo de congreso2026
Artículo de congreso 86

Pedagogical-fit feedback improved 51 of 62 weak AI-tutor responses, but scaffolding gains created trade-offs

Benjamin Barlog, Hudson Craig, Zedong Peng

IEEE 27th International Conference on Information Reuse and Integration for Data Science (IRI 2026)

Barlog, Craig and Peng evaluated ChatGPT, Gemini, Gemma 4 and Qwen 3 across 240 introductory-programming tutoring scenarios with a six-part Pedagogical Suitability Index. Baseline scores differed modestly, while targeted feedback improved 51 of 62 weak cases. The largest gain was scaffolding, but prerequisite ordering and Bloom-level alignment sometimes declined, showing why tutoring quality needs multiple measures rather than one composite score.

AI tutorspedagogical fitscaffolding
Leer resumen de 500 palabras →