AI scribes produced fuller educational feedback notes, but human editing did not remove every error
Jaideep S. Talwalkar, David Chartash, Lisa Zhang, Michael Makutonin, Conrad W. Safranek, Anne Elizabeth Sidamon-Eristoff, Lee H. Schwamm, Donald S. Wright
JMIR Medical Education
Resumen de 500 palabras
Good verbal feedback can lose detail when an educator later turns it into a written note. Jaideep Talwalkar and colleagues tested whether an ambient AI scribe could preserve more of that educational conversation. Their study took place in a medical interviewing workshop using standardized patients. The AI was asked to summarize feedback that had actually been spoken, not to invent a new assessment of the learner. That distinction makes factual fidelity to the source conversation central to evaluating the workflow.
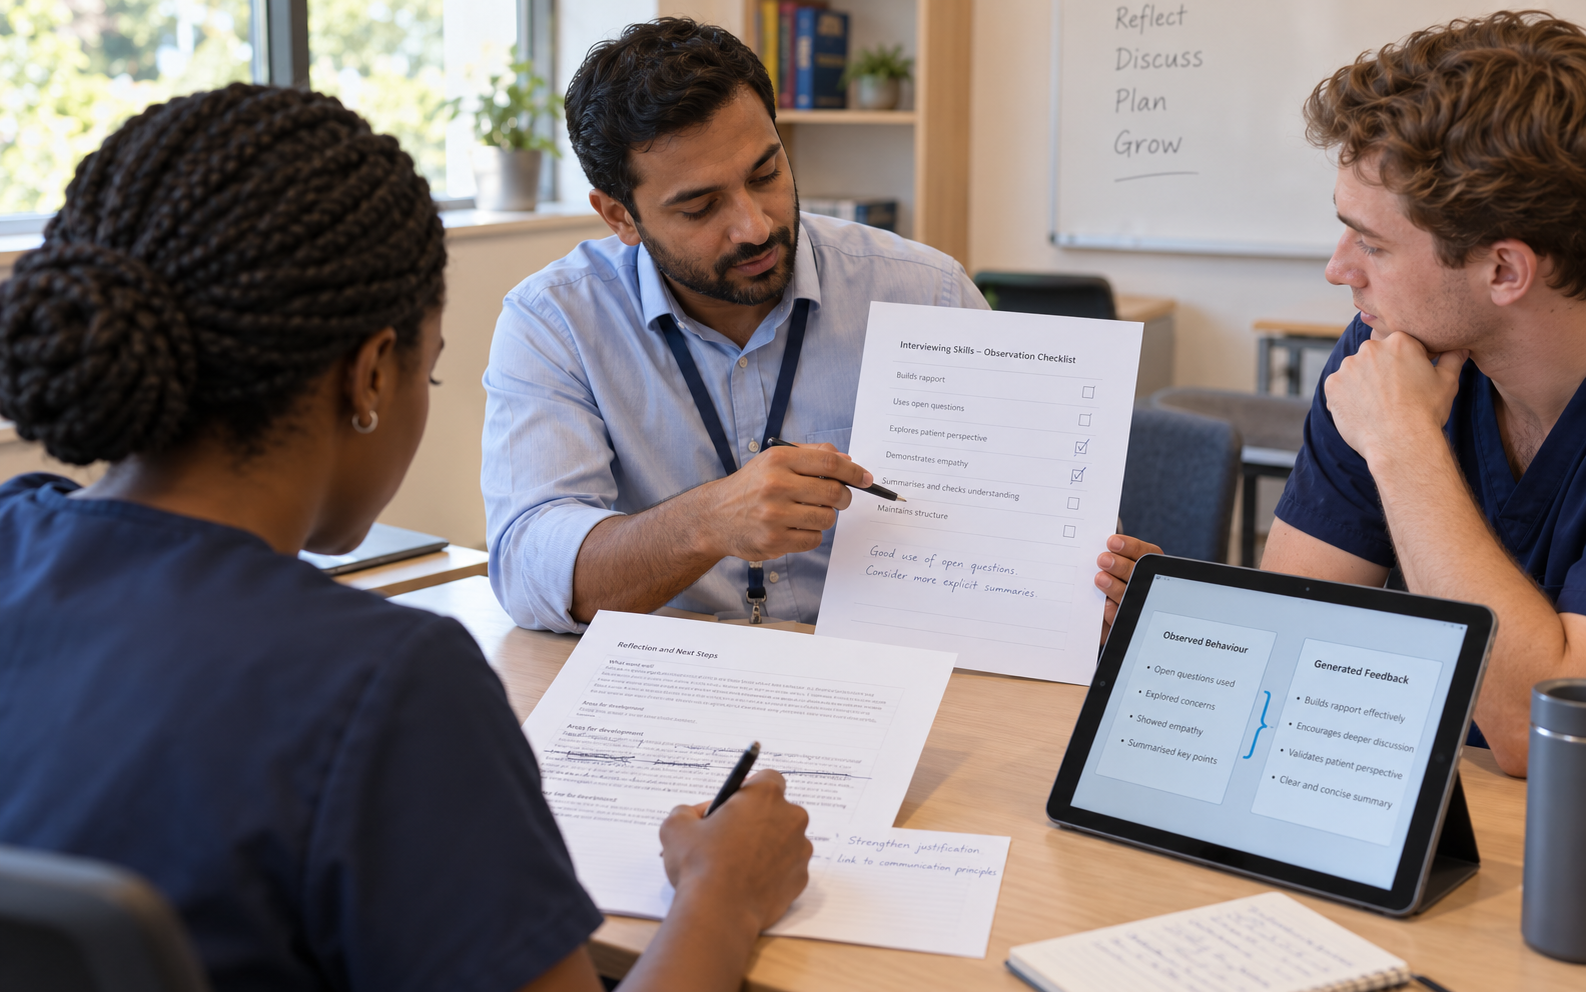
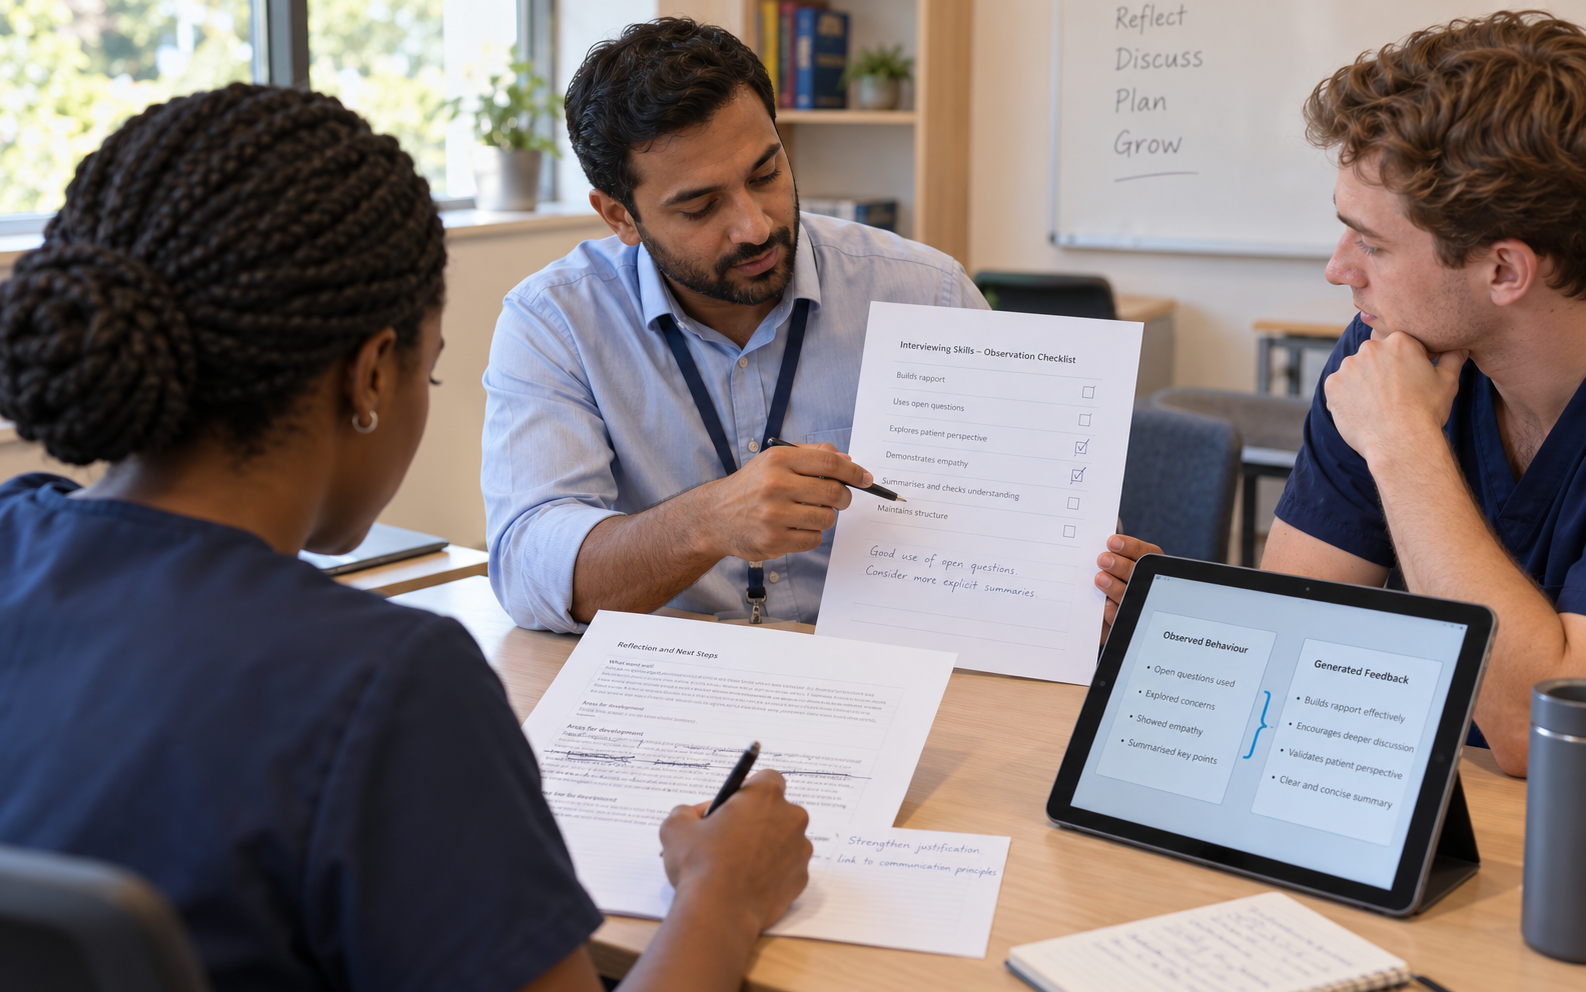
Thirteen clinician educators were randomized to human-only or AI-assisted documentation. The workshop involved 102 first-year medical students who attended, and feedback forms were submitted for 94 of them. In the AI condition, a scribe generated a transcript of the interview and feedback exchange. A private GPT-4o instance within the university's infrastructure then extracted educational feedback, which instructors reviewed and edited before submission. The comparison instructors wrote their narratives without AI assistance. The intervention therefore combined recording, summarization and human editing rather than replacing the educator's observation.
Researchers rated human-only, unedited AI and human-edited AI narratives using a five-point feedback-quality instrument. Median scores were two for human-only notes and three for both AI-assisted forms. AI-assisted notes were also substantially longer. Their higher scores indicate that more of the instrument's feedback elements were explicitly documented, but do not establish that the additional detail was always accurate, necessary or useful to the student. A well-structured narrative and a faithful account of what happened are related but separate qualities.
A factuality review of 117 generated feedback elements found eight mischaracterizations and two hallucinations. Editing reduced the mischaracterizations to one, but the two hallucinations remained in the reviewed sample. This is a concrete reason not to treat a human-editing step as an automatic guarantee of accuracy. Task-load and usability scores did not differ significantly between conditions, with wide uncertainty and challenging ratings in both groups. The study does not establish a time-saving benefit merely because it found no statistically significant workload difference.
The trial was small and limited to one institution and workshop format. Instructors were the randomized units, and a modest number of educators produced many individual notes. Raters were formally blinded, but could usually identify whether a narrative had AI assistance, partly because the writing differed markedly. Only a subsample received detailed factuality review. The research did not measure whether students understood, used or benefited from the notes on a later encounter. It therefore supports evaluating a documentation workflow, not claims about improved clinical competence or patient outcomes.
For AIEDHK, the broader application is preserving feedback in supervised practice settings without losing its evidential basis. A pilot could require each substantive comment to be traceable to an observed action or recorded exchange, and ask the educator to correct unsupported interpretations before sharing the note. A later learner task could establish whether the feedback changed performance. These are proposed steps beyond the trial. The useful opportunity is better capture of educational detail, with source fidelity, review burden and learner benefit assessed separately rather than assumed from the length or polish of the generated document.