Synthetic Training Data
Synthetic training data are generated examples used to train models. Their value depends on correctness, diversity, provenance, and evaluation against independent human or real-world data.
Fuentes
Resumen completo
Synthetic training data are examples produced through a generating process rather than collected directly as ordinary observations. A simulator can generate sensor readings, a rule system can construct mathematics problems, and a language model can produce instructions and responses. Synthetic describes the origin of the data. It does not tell us whether the examples are correct, diverse, representative, private, or suitable for training.
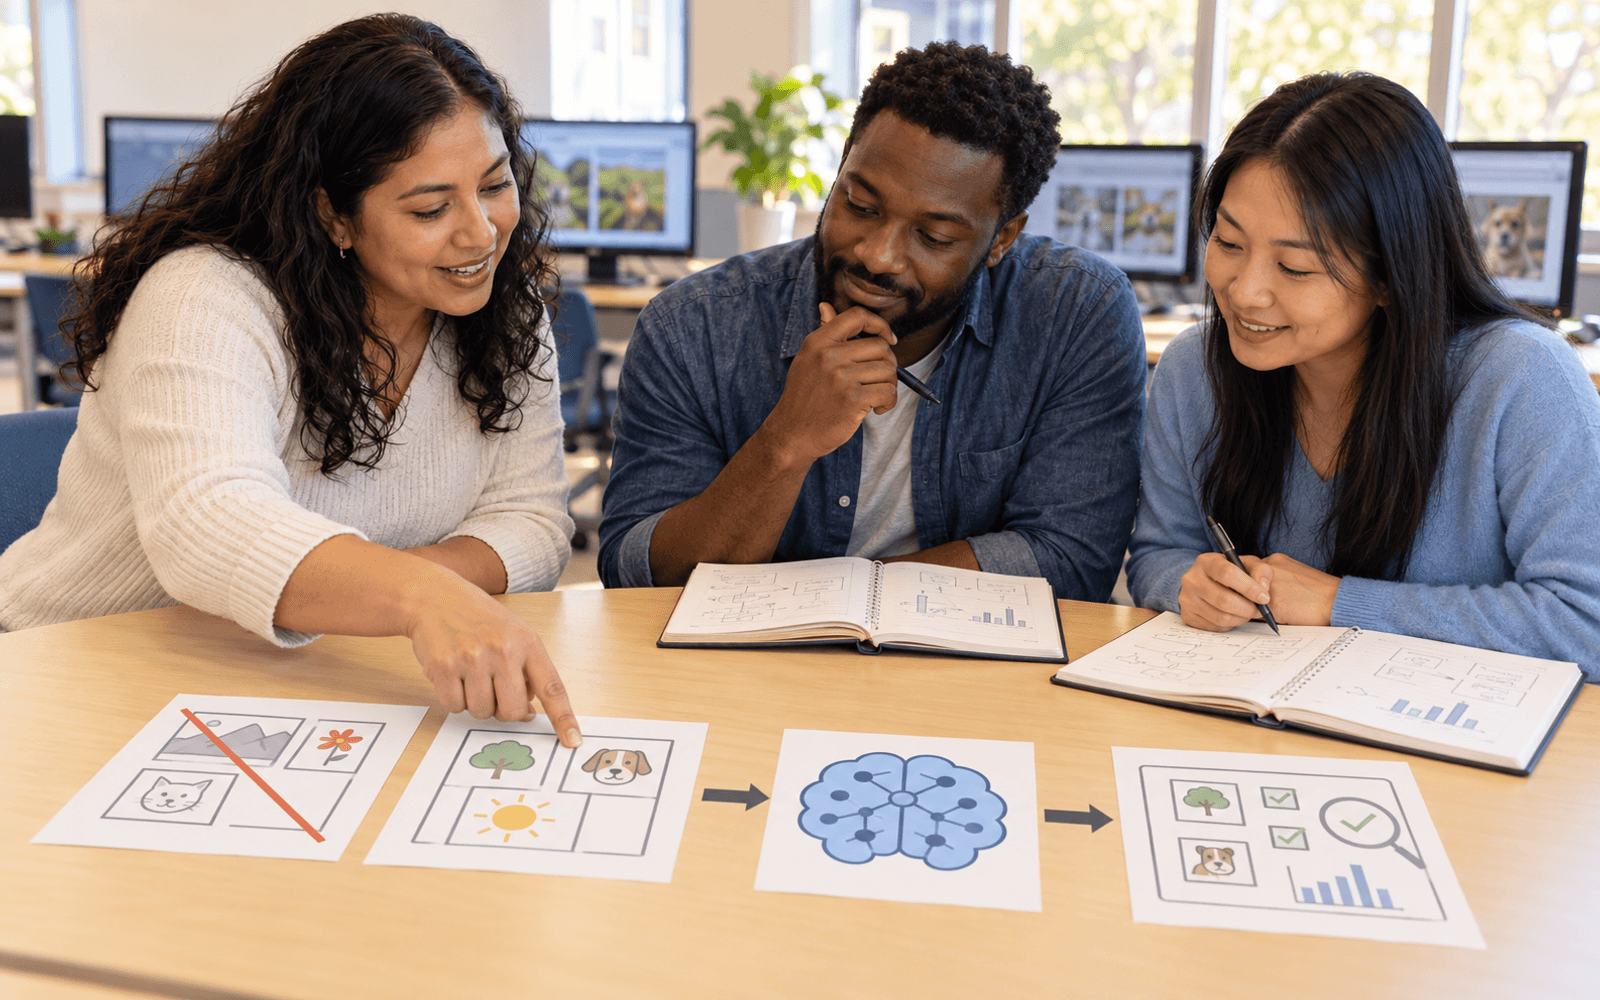
One attraction is control. Developers can deliberately vary a feature, create a rare scenario, or generate additional examples for a narrowly defined task. Self-Instruct demonstrated a pipeline that generated instruction data and filtered invalid or overly similar examples before using them for training. That result shows a possible method, not a general guarantee that a model improves by consuming its own outputs. Filtering criteria and an independent evaluation set remain essential.
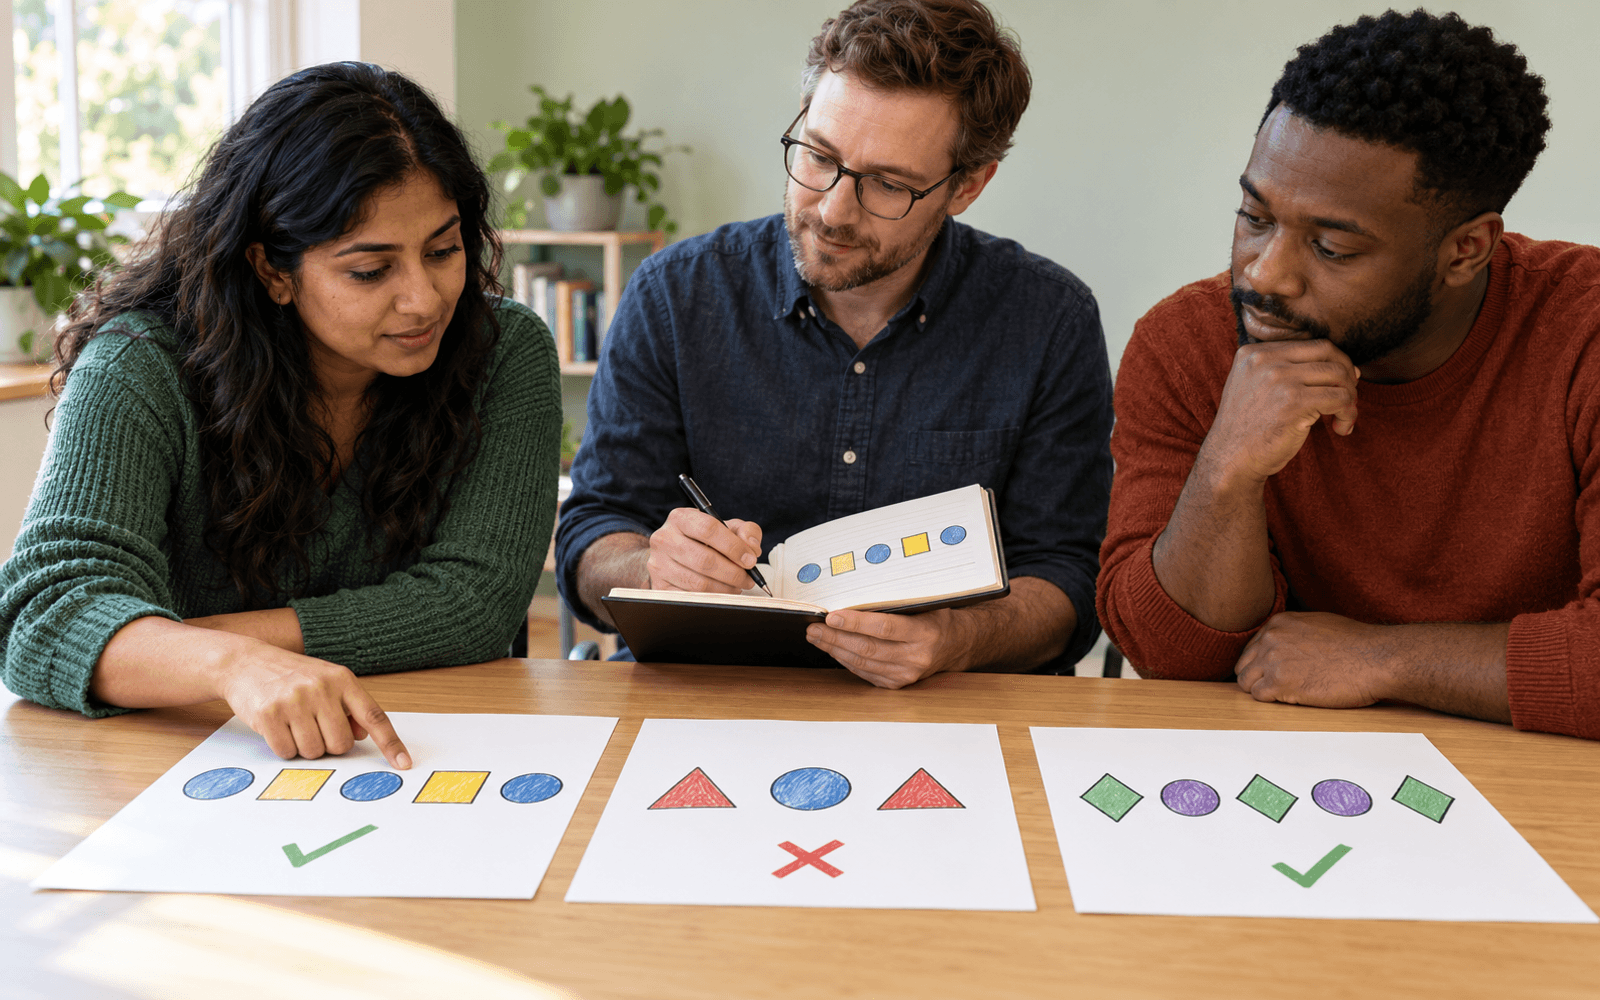
Consider a hypothetical assistant that classifies errors in equivalent-fraction exercises. Teachers define several error types and construct examples using exact arithmetic rules. A generator produces candidate responses for each type, including correct answers. Educators verify that the intended error is actually present, check ambiguous cases, and remove unrealistic language. The final evaluation uses separately collected, appropriately consented learner responses because success on the generator's patterns alone would be weak evidence of classroom usefulness.
Generation can amplify the assumptions of its source. A language model may produce plausible but incorrect explanations or make student writing unnaturally tidy. Repeated sampling does not ensure new information: many examples may differ superficially while expressing the same pattern. A dataset can also omit uncommon perspectives or language forms. Teachers should inspect coverage across meaningful dimensions and keep records of the generating model or rules, prompts, filtering decisions, and human corrections.
Research on recursive training has shown that replacing data with model-generated outputs across generations can cause distributions to deteriorate under studied conditions, sometimes called model collapse. This is a warning about particular feedback processes, not proof that every use of synthetic data is harmful. Retaining appropriate real data, checking rare cases, and independently measuring performance are different from repeatedly treating generated outputs as ground truth. The balance must be evaluated for the actual task rather than inferred from the word synthetic.
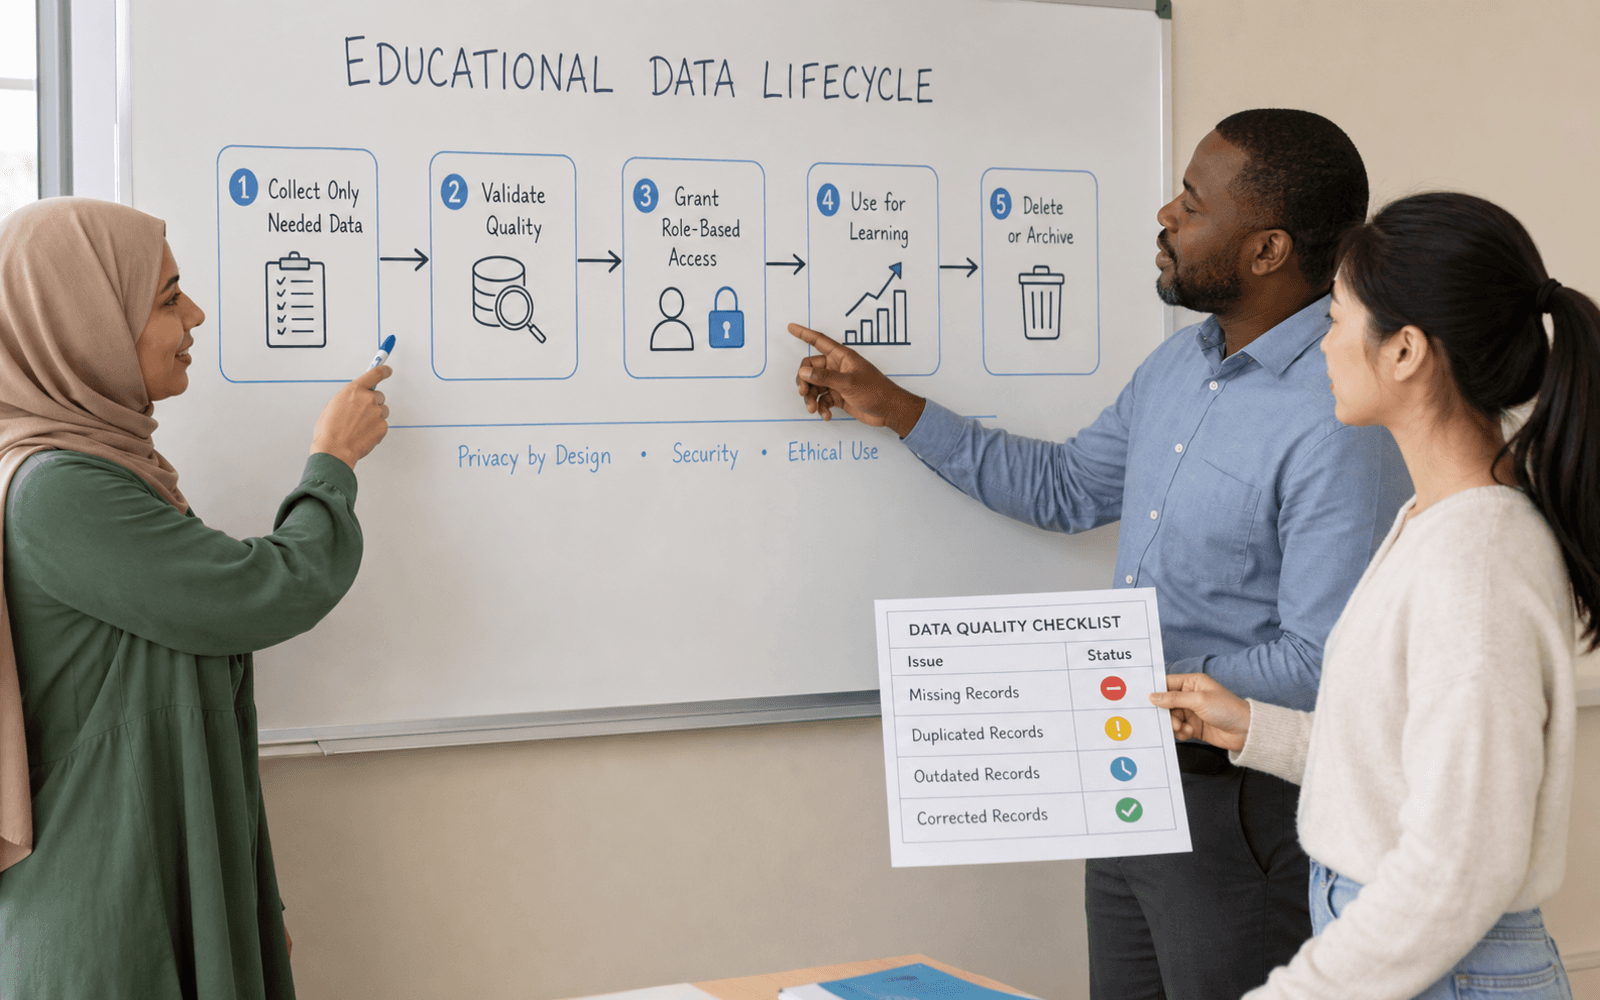
Synthetic examples are not automatically anonymous. A generator trained on sensitive records may reproduce details, and a realistic record can still create privacy concerns. For educational work, fictional identities and deliberately designed scenarios are preferable when authentic personal data are unnecessary. A useful class activity compares a small synthetic dataset with independent examples, asking which variation is missing and which errors the generator repeats. Before training, learners write acceptance rules for correctness, diversity, and provenance. After training, they test on a different source. This turns synthetic data into a transparent engineering choice whose usefulness can be checked, rather than an inexpensive substitute for all evidence from actual learning situations.