Gradient Descent and Optimization
How a model’s parameters are adjusted to reduce a chosen loss, and why successful optimization is only one part of building useful educational AI.
Fuentes
Resumen completo
Gradient descent is an optimization method that repeatedly adjusts parameters in a direction expected to reduce a function. In machine learning, that function is often a loss measuring how poorly the model's predictions match a training objective. The gradient describes how the loss changes with small changes in each parameter. Moving a suitable distance in the opposite direction can reduce the loss locally. This is a numerical procedure, not evidence that the model understands the educational task.
A one-parameter example makes the update visible. Suppose the loss is the square of the difference between a parameter w and the target value three. Starting at w equal to zero, the loss is nine and the gradient is minus six. With a learning rate of 0.1, subtracting the learning rate times the gradient moves w to 0.6. The new loss is 5.76. This toy calculation illustrates one step toward a minimum; real models may have millions or billions of interacting parameters.
The learning rate controls step size. Very small steps can make progress slow, while overly large steps can overshoot or make the loss increase. The local direction is useful only together with an appropriate step. Training procedures may change the rate over time or use optimizers that adapt updates based on previous gradients. Momentum, for example, uses accumulated directional information. These choices affect numerical behavior, and no setting is best for every model and dataset.
Computing a gradient over all training examples can be expensive. Stochastic and mini-batch methods estimate updates using one example or a subset at a time. Their losses may fluctuate even while the overall training process improves. A teacher viewing a training chart should therefore distinguish an individual noisy step from a persistent problem. Data order, initialization, batch size, and optimizer settings can all influence the path. Reproducibility requires recording those choices alongside the model and data version.
Optimization and generalization are different goals. A model can keep reducing its training loss while becoming less reliable on new examples. Validation data help decide when additional fitting is no longer useful. The chosen loss also matters: an optimizer can become excellent at the wrong target, such as reproducing biased labels or rewarding a superficial feature of student writing. It does not decide whether the training objective represents worthwhile learning or whether its predictions should guide a consequential action.
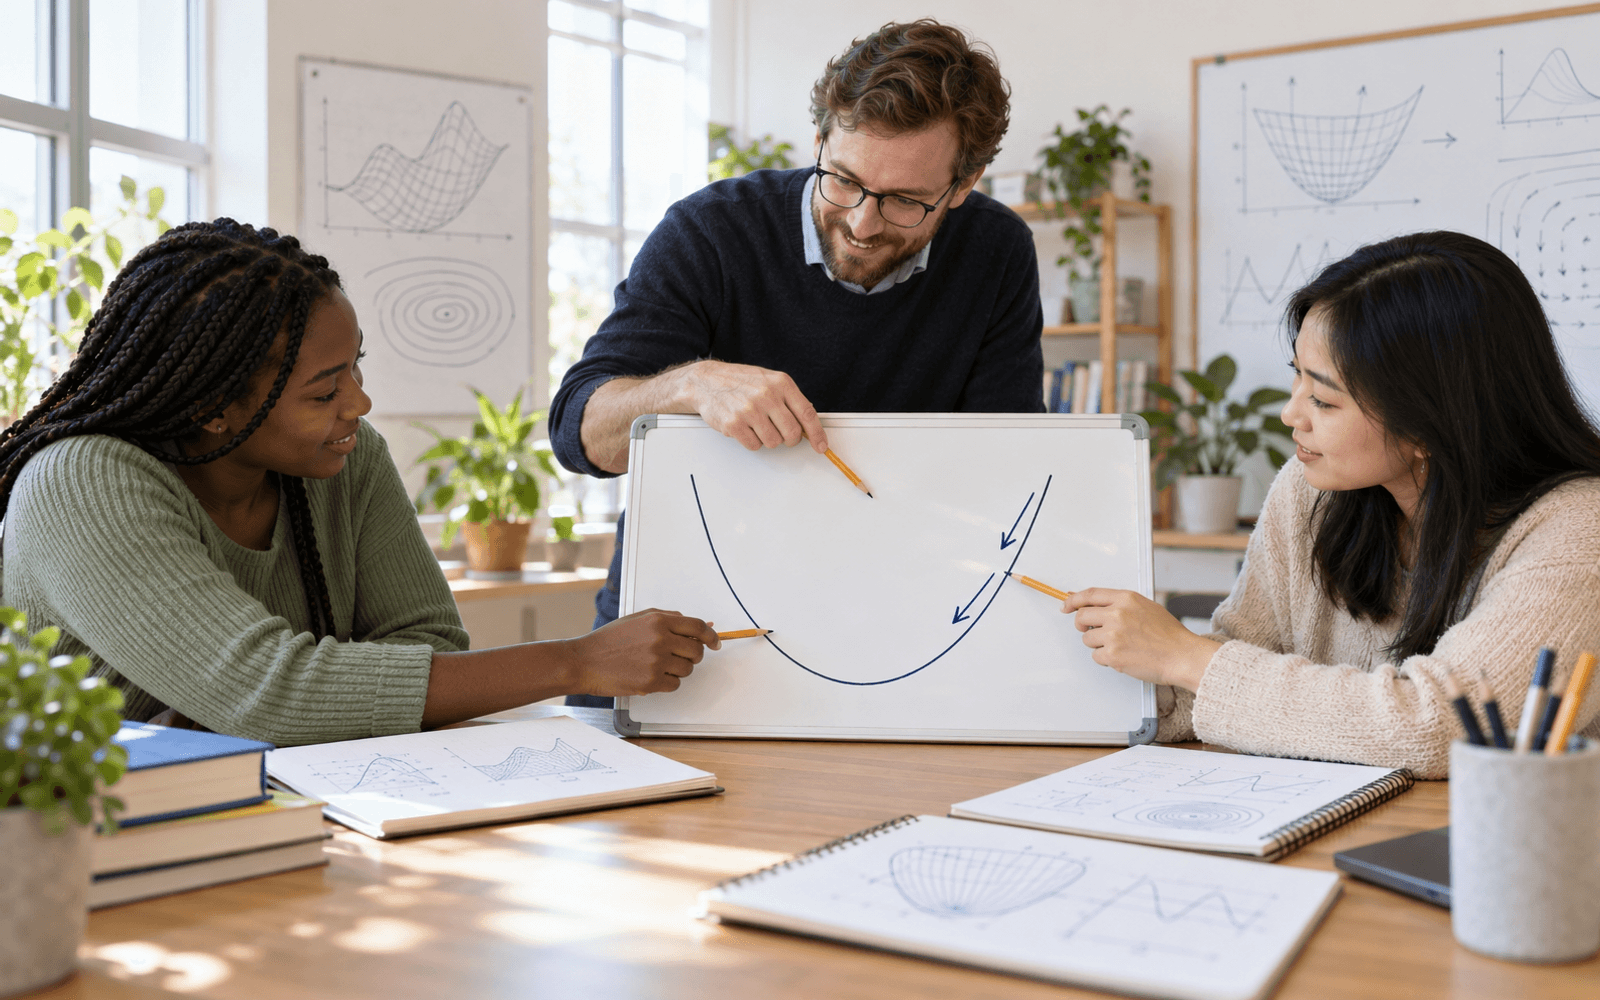
Learners can explore the toy function by calculating several updates with different learning rates and plotting their paths on a simple curve. Ask when the loss falls, when it overshoots, and what information the gradient supplies. Then connect the exercise to a model-training report that includes both training and validation results. Gradient descent explains how parameter adjustment can occur, while leaving separate questions about data quality, task validity, fairness, and educational benefit. Understanding those boundaries helps educators interpret technical progress without mistaking lower loss for a complete evaluation.