Federated Learning
Federated learning coordinates model training across separate data holders. Local data can remain in place, but shared updates, unequal datasets, and coordination still require careful design.
Fuentes
Resumen completo
Several colleges want to improve a model without pooling their learner records in one central database. Federated learning is a family of approaches that coordinates training across separate data holders. Each participant performs some computation locally, and the system combines information from those computations to update a shared model. Keeping raw records local changes the data flow, but does not by itself make the overall process private or fair.
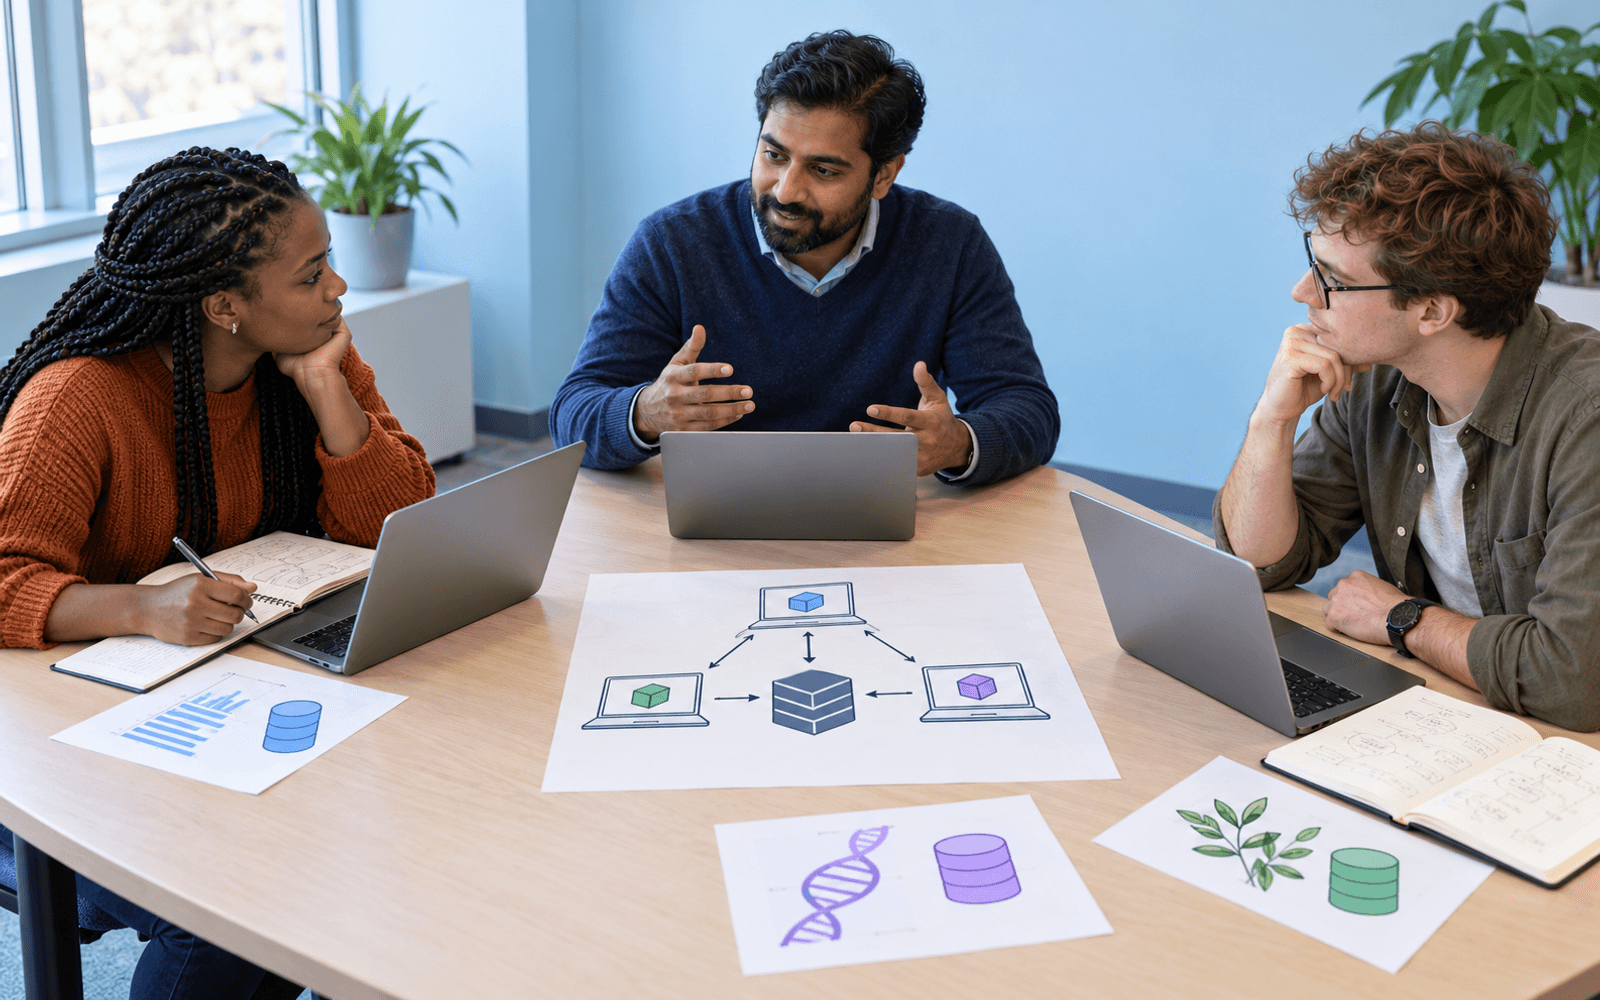
In a common approach, a coordinator distributes current model parameters. Participating clients train on local examples and send model updates back. The coordinator aggregates those updates, sometimes weighting them by local sample size, and starts another round. The original Federated Averaging research explored how multiple local training steps can reduce communication demands. A client may be an individual device or an institution; those settings differ substantially in reliability, scale, and governance.
Education creates distinctive coordination problems. Colleges may teach different curricula, use different assessment conventions, or serve different populations. Their data are therefore unlikely to be interchangeable samples from one uniform distribution. Larger participants can dominate an average, while small or intermittently connected sites contribute less. A shared model can perform well overall yet fail at a particular institution. Evaluation needs both collective results and results for each intended setting.
Consider an illustrative consortium developing a model that predicts whether a practice response concerns a particular science topic. Each college checks that labels have the same meaning before training begins. The consortium creates a shared protocol, reserves local test sets, and compares the federated model with models trained only within each college. Teachers examine errors across language varieties and curricula. If one site benefits while another loses useful distinctions, the decision should reflect that difference rather than hiding it behind a pooled accuracy score.
Model updates can reveal information about training data. Secure aggregation can limit what a coordinator sees from individual participants, while differential privacy can provide a different kind of protection under stated assumptions. Neither technique follows automatically from the word federated. The system also needs authentication, authorization, protection against malicious updates, retention rules, and a response to participant withdrawal. Institutions should know who controls the coordinator and how updates and model versions are recorded.
A classroom demonstration can use fictional datasets held by different groups. Each group fits a small model or computes a permitted summary, then compares locally trained and combined results. Introduce one group with a different data pattern to make the challenge visible. Ask learners to draw exactly what leaves each group and what an observer could infer. The lesson is that distributed training redistributes computation and information flows; it does not eliminate the need for data quality, meaningful consent, security, or educational judgment. A consortium should proceed only when this more complex arrangement serves a clear purpose better than available alternatives.


