Conference paper: FeedType tests whether AI feedback changes its focus as student writing develops
Norah Almousa, Shayan Peyghambari Oskoui, Raquel Coelho, Gayle Rogers, Xiang Lorraine Li, Diane Litman
Proceedings of the Artificial Intelligence in Measurement and Education Conference (AIME-Con): Full Papers
500-word summary
Listen to the summary
Audio summary
Norah Almousa and colleagues present FeedType in the October 5–7 AIME-Con proceedings. The benchmark draws on 1,966 paragraphs from three university writing courses and compares teacher feedback with six language models under three prompting strategies. Seven categories describe what feedback addresses. Automated annotations were checked against human judgments. Although models covered most categories, none fully reproduced teachers’ adaptive patterns. Analyses of draft stages and performance were limited to the composition course. The paper studies feedback behaviour, without testing an intervention’s effect on learning.
Its contribution is a way to ask what a comment focuses on and whether that focus changes appropriately. A system may repeatedly ask for elaboration even when another response would be more useful. Matching a teacher’s category distribution would not itself prove that every comment is accurate or helpful. The benchmark’s courses, annotation choices and tested model versions also constrain how far the results can travel beyond the reported setting.
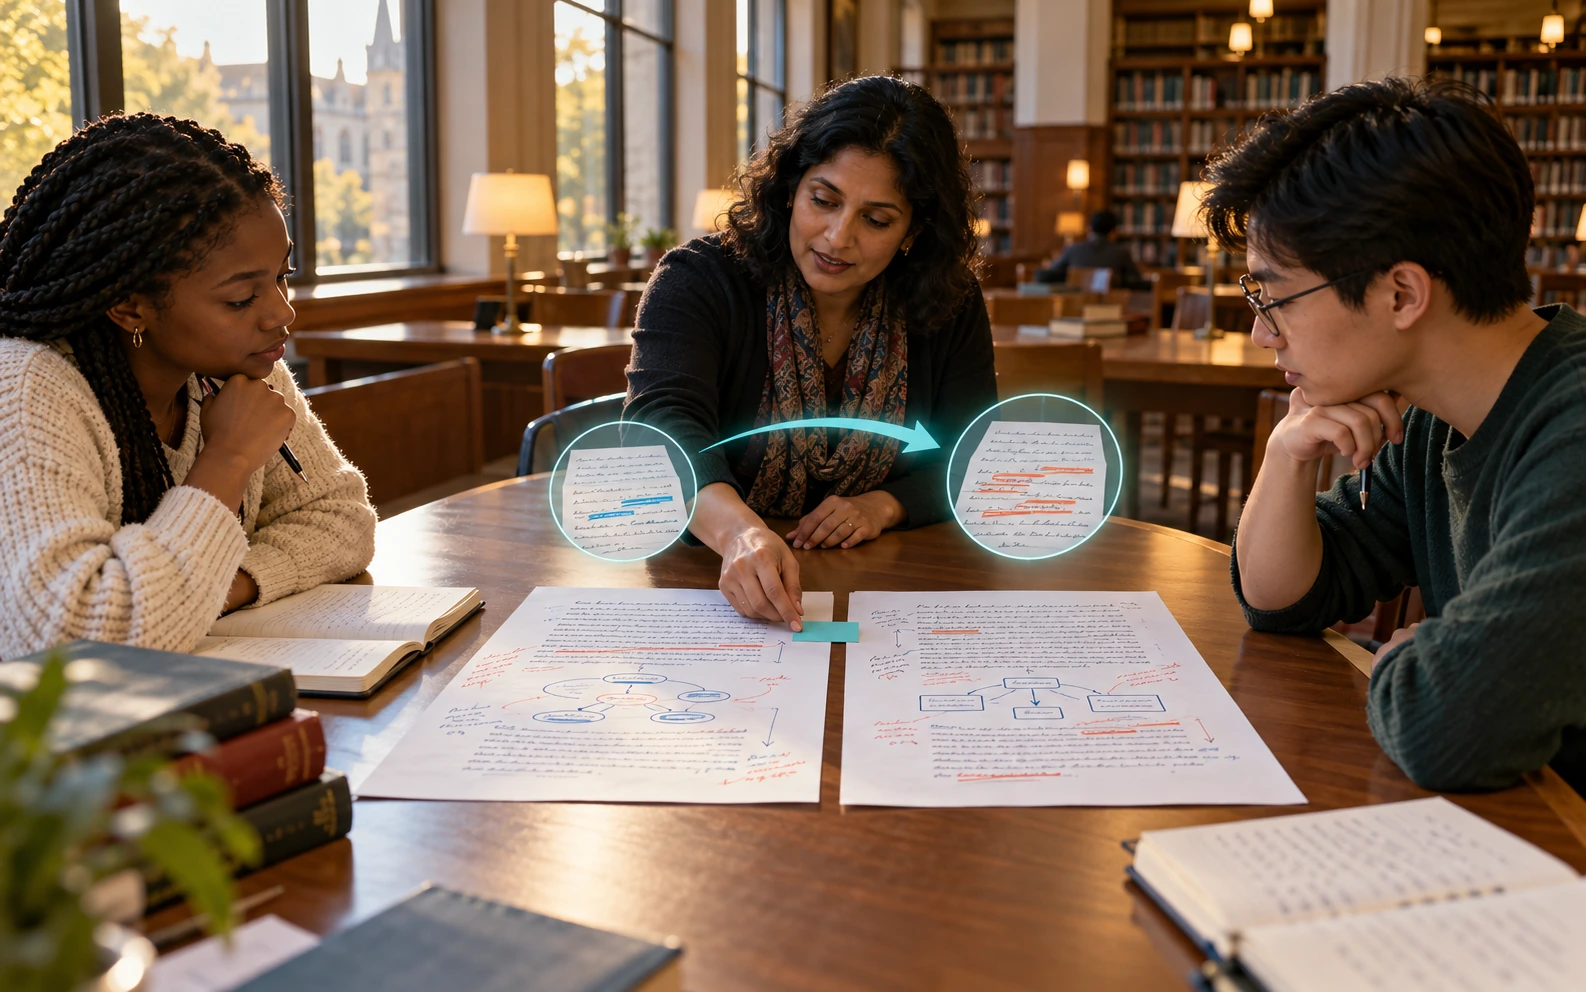
For AIEDHK, consider a proposed writing workshop built around two drafts of the same paragraph. Before reading any generated feedback, the teacher would identify the most consequential next step for that stage of the assignment. Students could then compare suggestions, locate the textual evidence each one addresses, and explain which issue deserves attention first. This is an editorial teaching proposal, rather than an activity evaluated by the benchmark study.
For example, an early draft about a local environmental issue might need a clearer claim supported by an appropriate source. A later draft could already make that connection and instead need a precise explanation of a qualification. Asking for more detail in both cases would miss the different revision priorities. Learners could explain why an apparently helpful comment would distract from the current task, giving the teacher evidence of their judgment about writing.
A local pilot could retain the draft, the suggested comment, the learner’s selected action, and a short reason for that choice. Teachers could inspect a small sample of agreements and disagreements rather than assuming that accepting more suggestions indicates better learning. Reviewers should also examine comments that identify the right category but propose an unsuitable change. The purpose would be to understand how feedback supports a decision at a particular moment in a writing process.
A bilingual writing class could examine whether a comment preserves the writer’s intended meaning across languages. Students could defend a revision using the assignment’s purpose, while the teacher considers whether linguistic polish is distracting from an unresolved argument or an unsupported claim.
For product teams, the study suggests an evaluation question that can be made concrete before deployment: does feedback respond to the assignment, the current draft and the learner’s demonstrated difficulty? That question can guide a bounded review set without turning the teacher’s previous behaviour into an unquestionable standard. Later writing completed with less assistance could provide complementary learning evidence. FeedType supplies a useful research resource for examining adaptive feedback; a classroom or institutional adoption decision still needs evidence about the quality and consequences of the comments learners actually receive.