Product news: Devin's Astra testing case separates a working demonstration from the checks still missing
OpenAI
AI Product and Learning Report
500-word summary
Listen to the summary
Audio summary
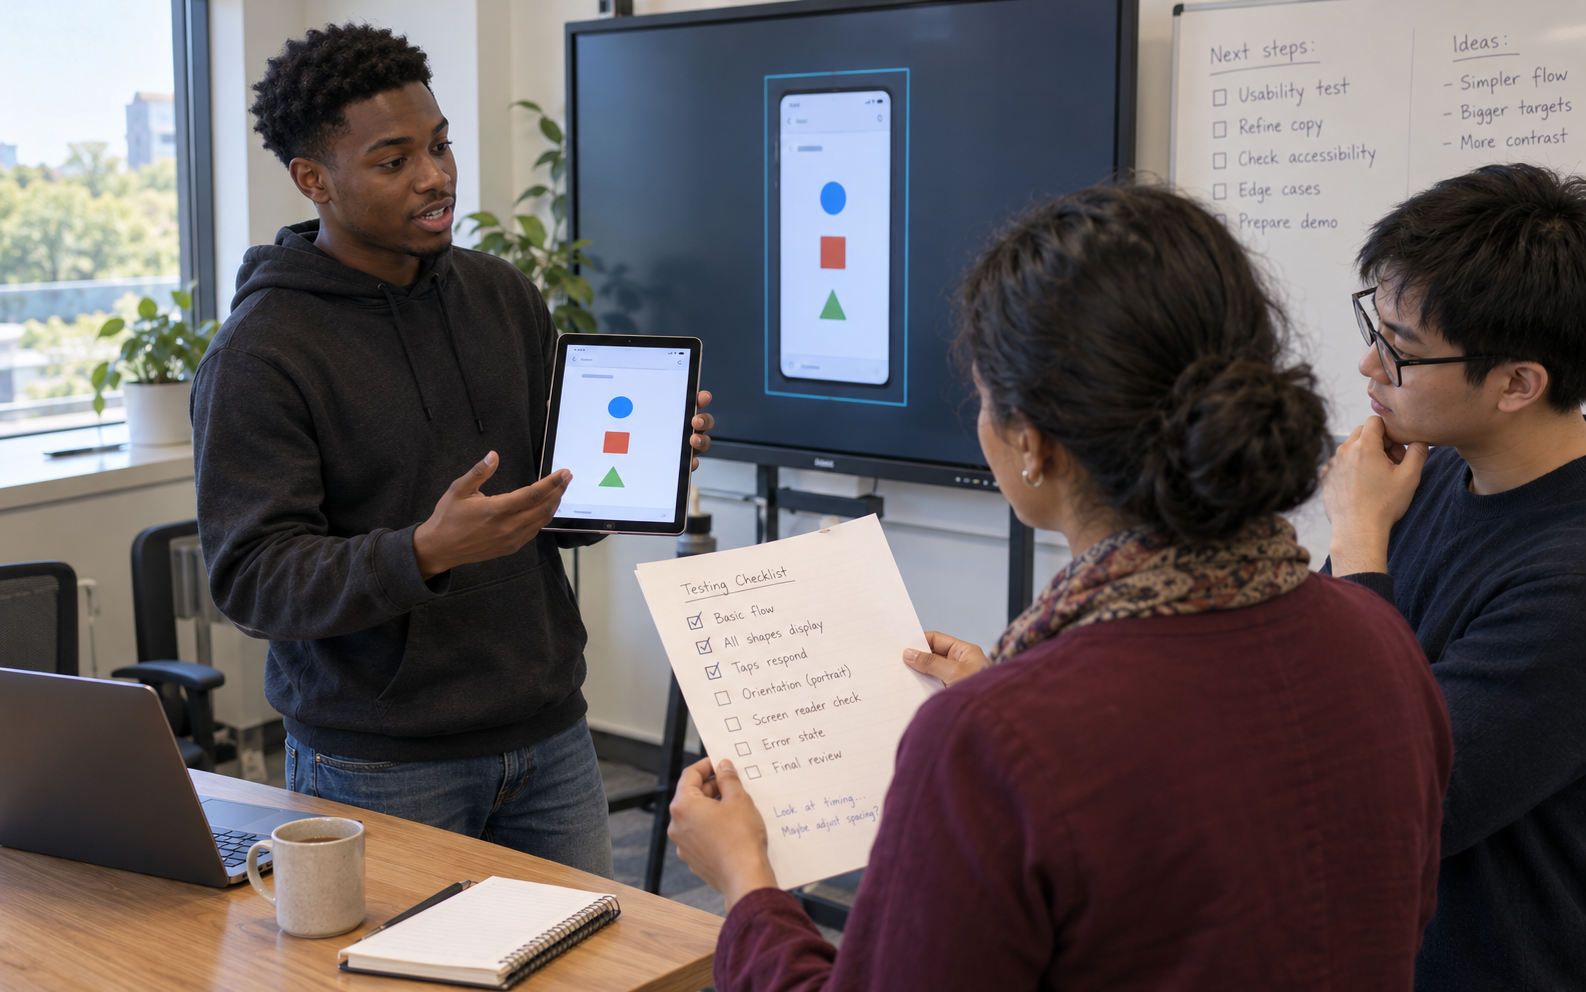
OpenAI published a Cognition case study on September 11, 2026 describing how Devin uses GPT-6 Astra to test software and show its results. One example pairs a recording of a game running in a simulator with a report identifying checks completed and areas left untested. This September 13 article examines that review workflow. It is a vendor-published example, not an independent estimate of reliability or a new report on Astra's original launch.
The combination is useful because a demonstration and a test report answer different questions. A recording can show what happened during one run. A report can specify which conditions were checked and which were omitted. Neither should be mistaken for proof that every user journey, device, or edge case works. Students learning to build software need to understand that boundary before they learn to produce more persuasive demonstrations. Reviewers should be able to reproduce the most important check.
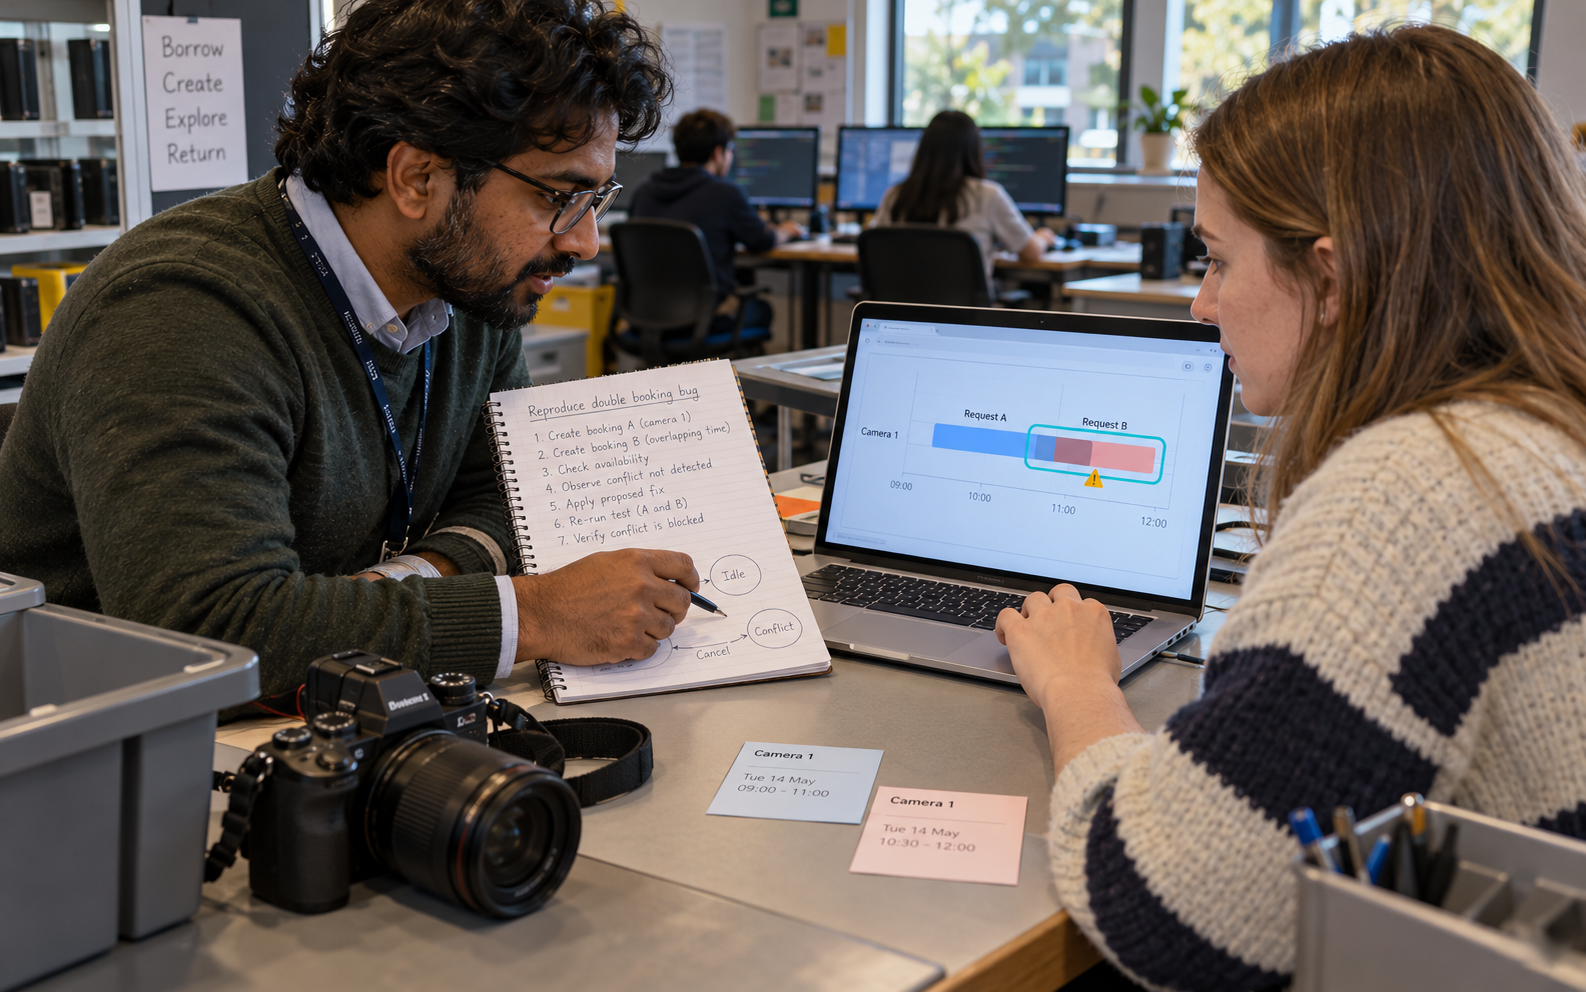
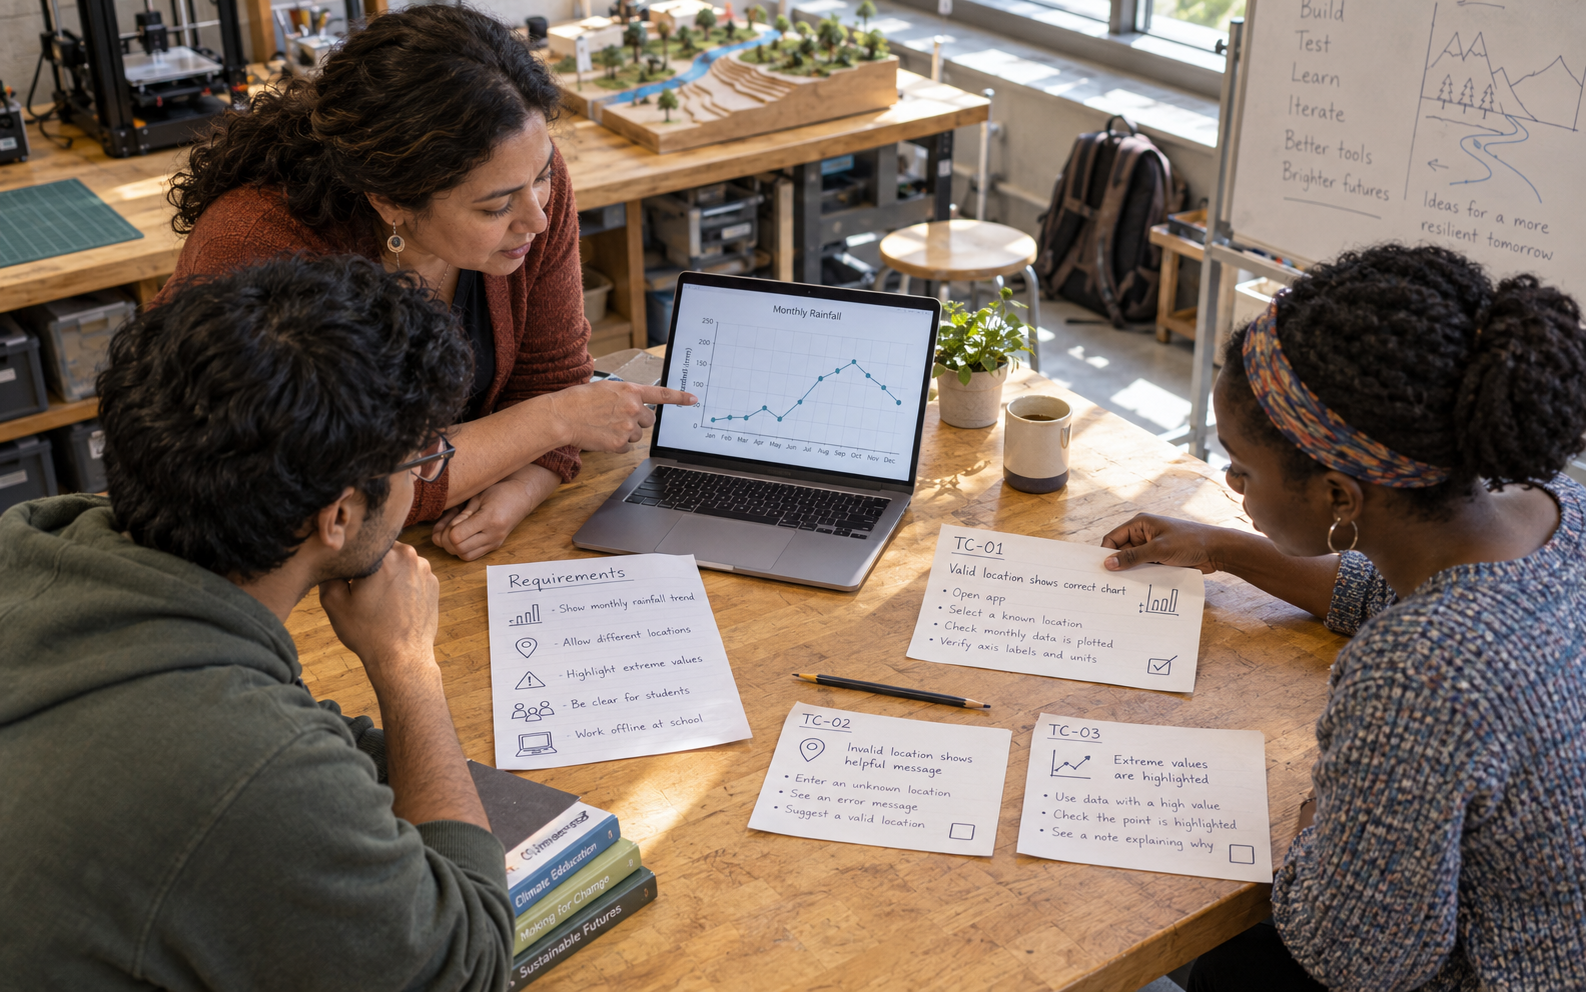
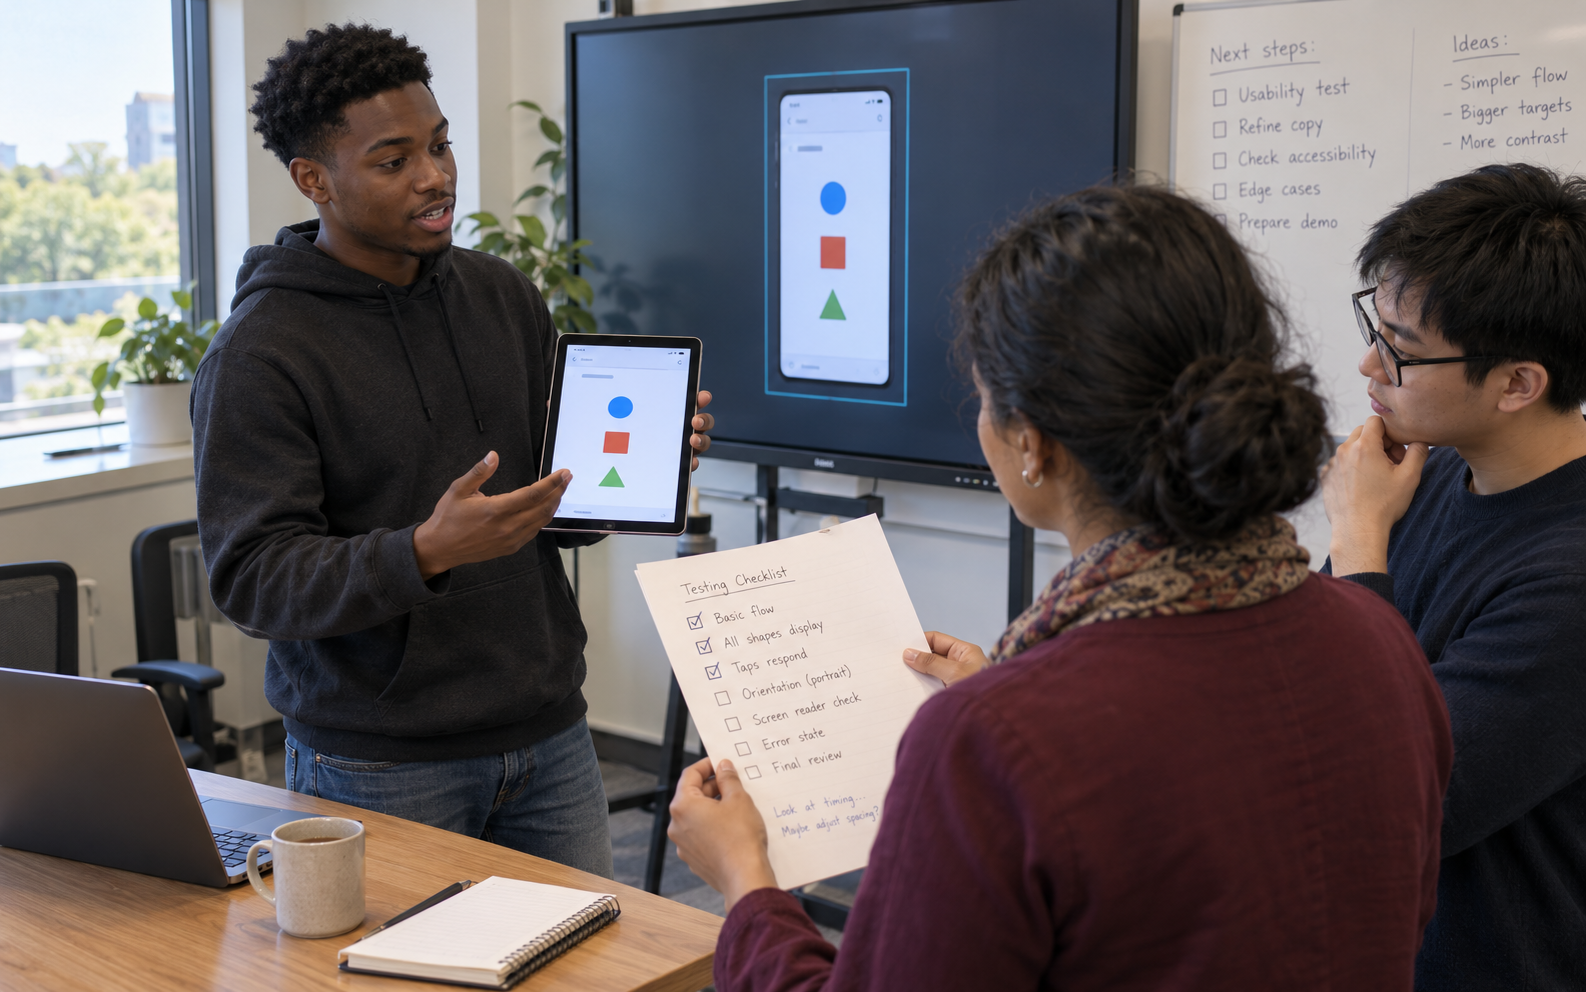
A course project could require a short evidence packet with every proposed change. The packet might include the requirement, the exact version tested, a relevant recording, and a list of unresolved checks. The student would explain why those checks are relevant to the change. A polished video without that explanation would be incomplete, while an honest report of a remaining failure could demonstrate strong engineering judgment.
For example, a team building a quiz interface might show a correct answer being accepted. Reviewers could then ask what happens with an empty response, a keyboard-only interaction, a repeated submission, or a narrow screen. The team does not need to test every conceivable situation at once. It needs to select cases that meaningfully challenge the intended behaviour and state what remains outside the evidence.
Anthropic's browser tools expand an assistant's ability to act on visible interfaces. Google's Gemini 3.8 Flash announcement showcases generated interactive software. These developments make the quality of review increasingly important. OpenAI's Cognition example contributes a useful reporting pattern, but the platforms' different capabilities should not be collapsed into a claim that all generated applications are self-validating. The people accepting a change still need to understand the tests.
Teachers can also ask students to revise their confidence after a new observation. A feature may pass the original check and fail when the input changes. The appropriate response is to update the claim, preserve the failed case, and improve the test, rather than delete the evidence or broaden the success statement. This makes debugging part of the assessed reasoning rather than an embarrassing detour hidden from the final presentation.
The case's most transferable idea is therefore modest: show the behaviour and describe the scope of the checks. In a capstone review, a student should be able to say which requirement a recording supports, which test could falsify their claim, and what another reviewer should try next. An AI agent can help assemble those materials, but a convincing engineering account depends on the connection among requirement, execution, limitation, and human acceptance.