Product news: Claude Managed Agents adds dynamic workflows for larger tasks, making coverage records more important
Anthropic
AI Product and Learning Report
500-word summary
Listen to the summary
Audio summary
Anthropic's October 9, 2026 platform release notes introduce dynamic workflows in beta for Claude Managed Agents. An agent can write a programme that runs other agents in phases and combines their results, with execution continuing on the server. This October 11 report examines the implications for work involving many documents. The release expands orchestration; it does not establish that a large collection has been reviewed completely or interpreted correctly.
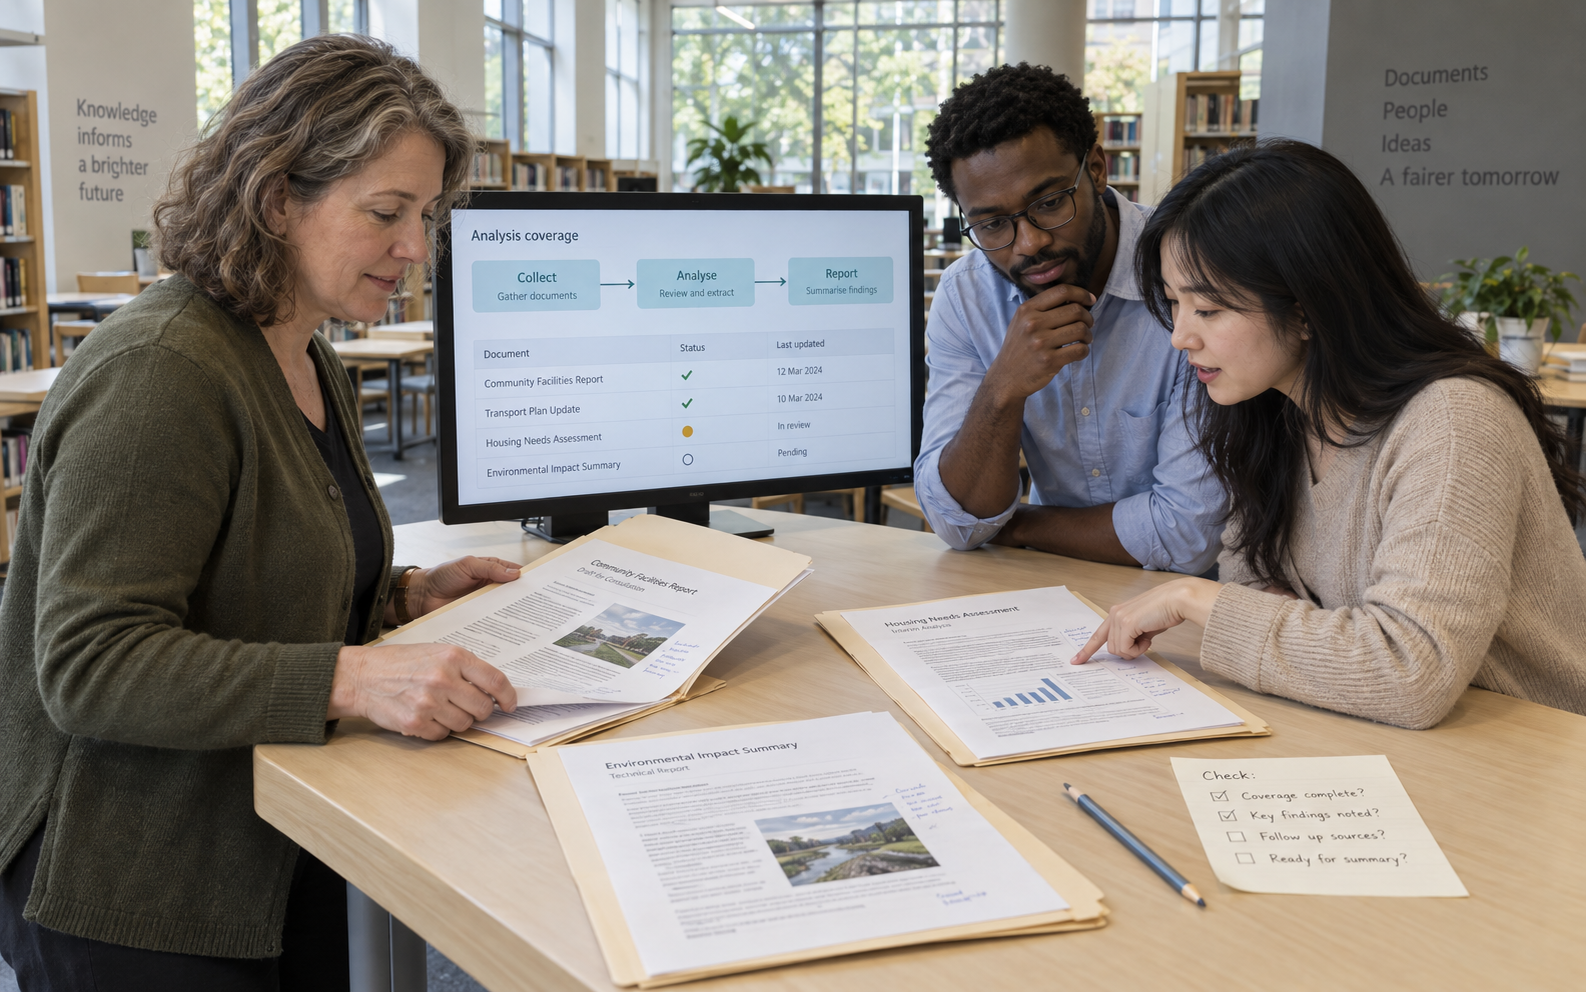
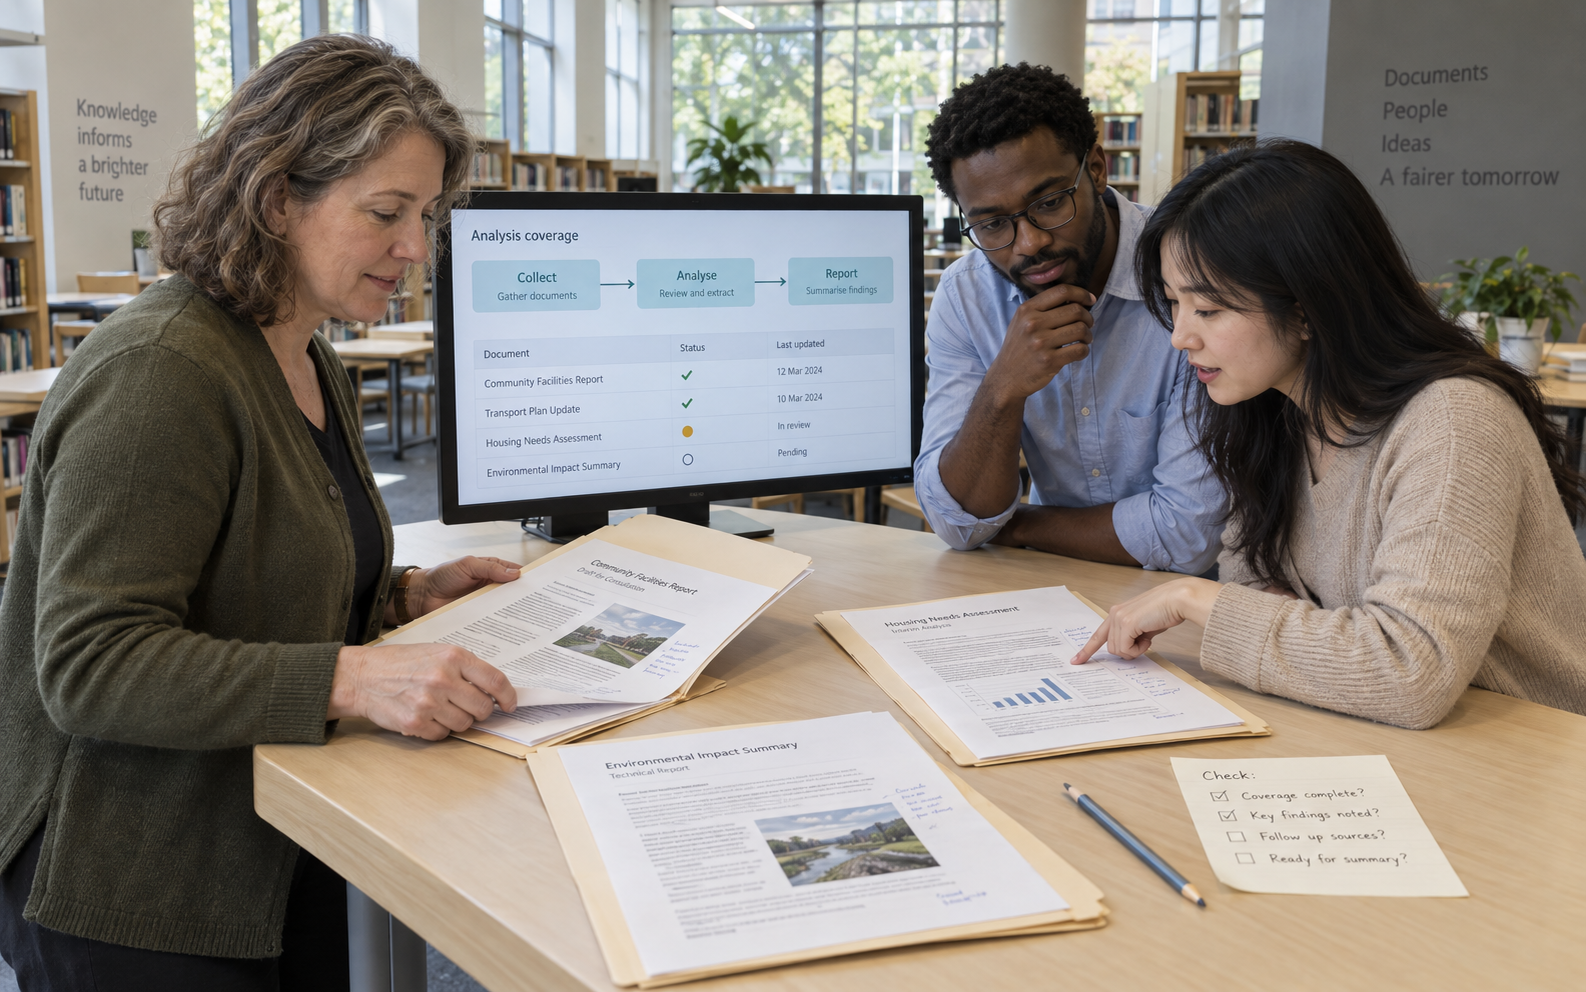
Scale changes the evidence a user needs. When reviewing a handful of files, a person may remember which one failed to open or contained an ambiguous section. Across hundreds of items, those details can disappear inside a polished synthesis. A useful system should preserve an item-level record of what was processed, what failed, and what requires another look. The final summary should not silently treat an unread document as irrelevant. A coverage table can list each source identifier, its processing status, and the reason an item needs review.
A proposed university-library exercise could use a small, known collection of public reports. Students would define the fields to collect, then compare the workflow's coverage with a manually prepared inventory. Some files could deliberately be missing a date or contain an unclear title. The exercise would test how the system represents uncertainty and incomplete access, without requiring a large or sensitive dataset.
The order of phases also matters. Deduplicating documents before extraction is different from merging apparently similar findings afterwards. A mistake early in the process can remove evidence that a later stage never sees. Students can draw the sequence, identify dependencies, and explain which intermediate results should be retained. That makes orchestration a subject of inquiry rather than an invisible efficiency feature.
OpenAI's practical GPT-6 guide similarly discusses independent work, updates, and completion evidence. Gemini's course-context tools offer a smaller-scale example of selecting the material an assistant should use. Compared with those approaches, Anthropic's new workflow mechanism addresses execution across many pieces. The core educational question remains whether the person can reconstruct how the final account was assembled from the available inputs.
A review plan should include exclusions as well as outputs. Why was an item skipped? Was it a duplicate, inaccessible, outside the defined scope, or simply not processed before the run ended? Those are different conditions. A team can sample completed items and inspect every unresolved category, while preserving the distinction between a partial result and a complete collection. Adding more agents does not remove the need for that judgment.
The beta may help developers build larger research-support or administrative tools with less orchestration work of their own. For education, the useful outcome would be a process that is easier to audit and explain, not merely one that finishes sooner. A strong student or developer handoff would include the collection definition, coverage record, important intermediate decisions, and remaining gaps. That makes scale compatible with an honest account of what the system actually did.