Product news: ChatGPT Voice adds GPT-Live-1.1 and multilingual voices, raising practical questions for oral practice
OpenAI
AI Product and Learning Report
500-word summary
Listen to the summary
Audio summary
OpenAI began rolling out GPT-Live-1.1 and GPT-Live-1.1 Quip in ChatGPT Voice on October 15, 2026, alongside additional voices for several languages. The company describes more natural accents, while warning that available voices vary by region and account. This October 18 report concerns that update, rather than the earlier GPT-Live launch or its API release. The accompanying Voice documentation also makes access dependent on factors including plan and workspace settings, so a classroom should check the experience available to its own users.
For language educators, a useful pilot would begin with a communication goal rather than a preferred synthetic accent. A learner might practise requesting clarification, explaining a timetable change, or politely disagreeing with a proposed plan. The teacher could define success as making the intended meaning understandable and responding appropriately to a follow-up question. That leaves room for different voices and speaking styles without treating resemblance to one model voice as the objective. These are proposed assessment choices, not learning effects established by OpenAI's release.
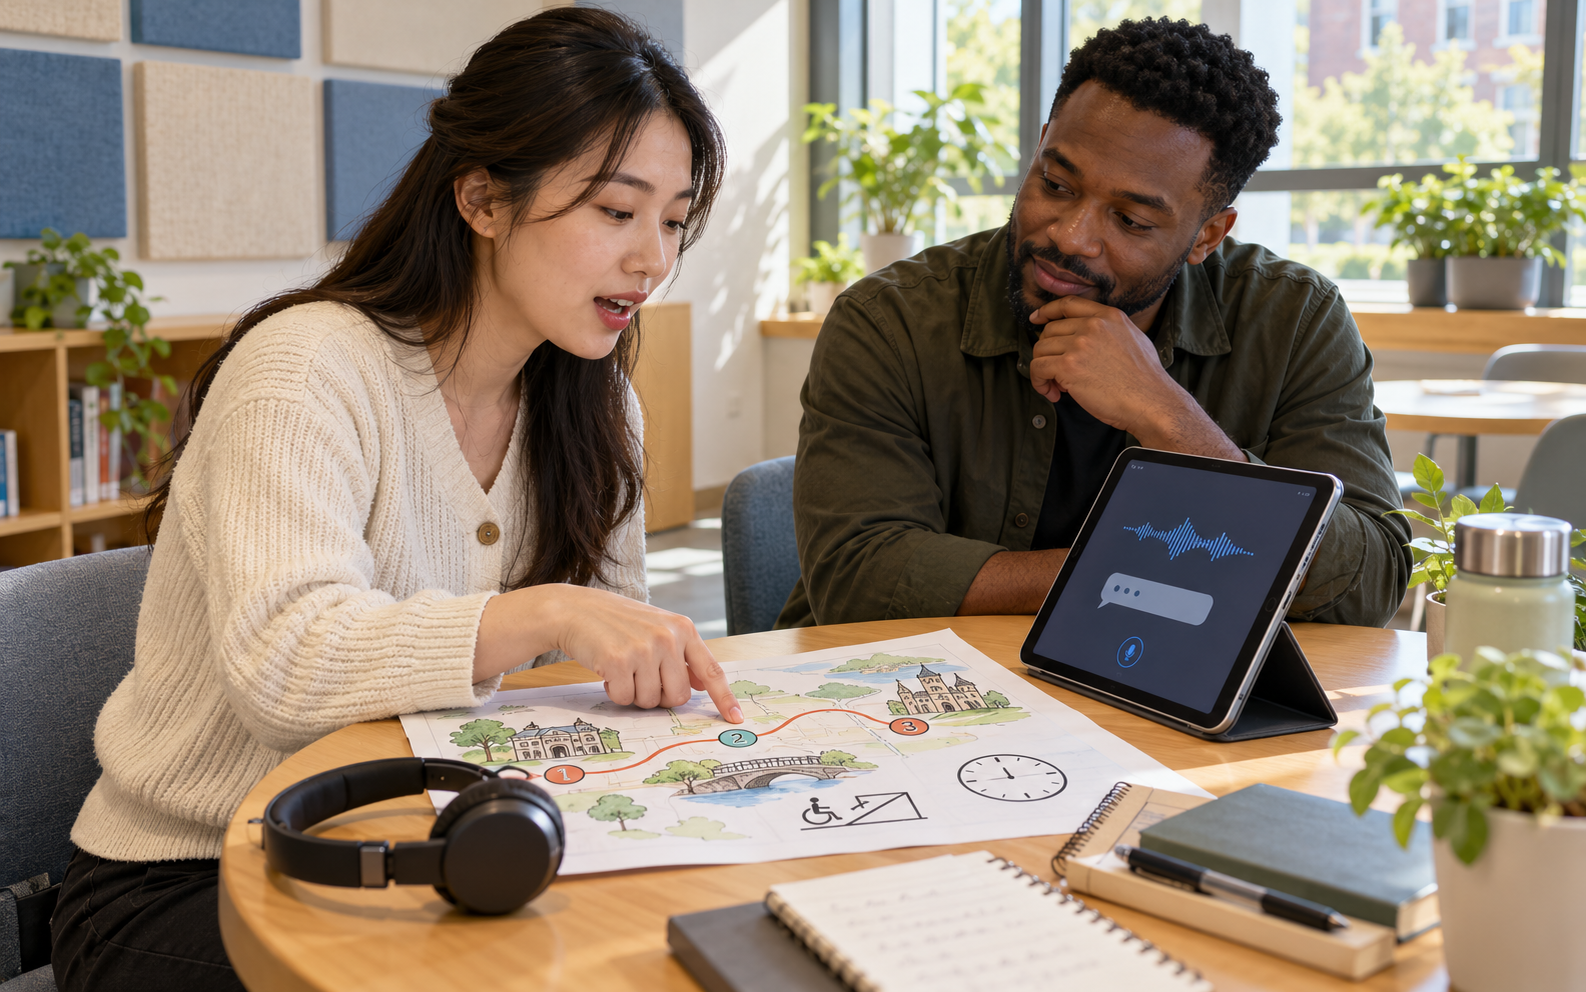
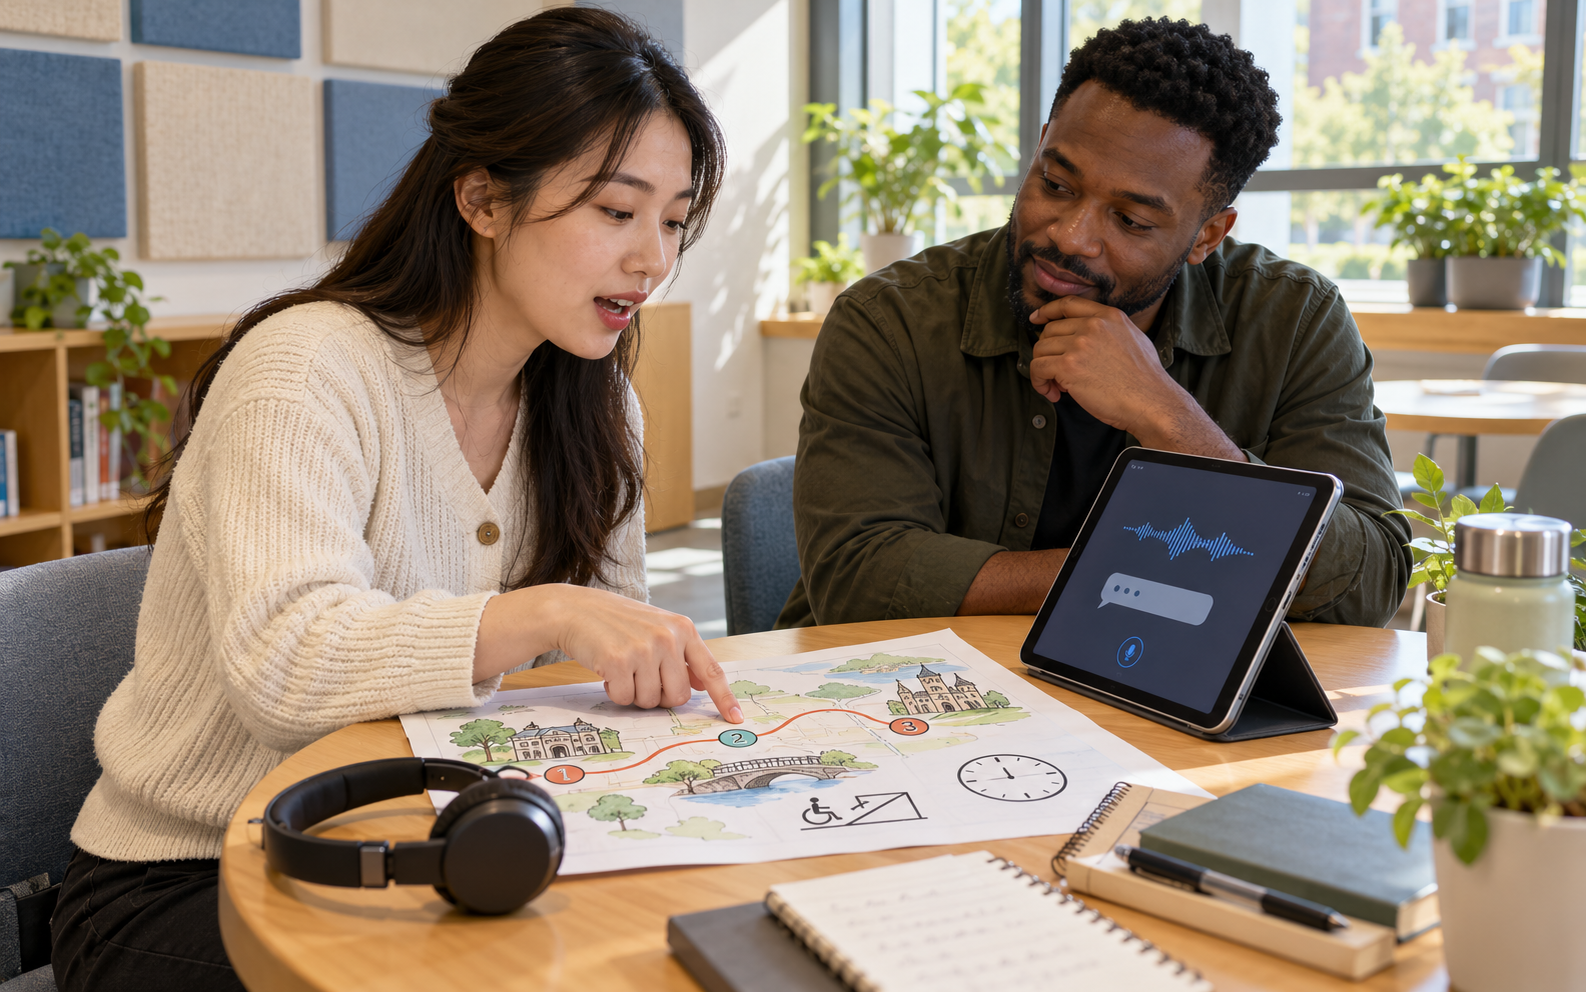
Consider an activity about planning a group excursion. The learner prepares three constraints, such as a departure time, a budget, and an accessibility need, using fictional details. During practice, they must explain the constraints and notice when the assistant proposes something inconsistent with them. Afterwards, they describe one misunderstanding and how they repaired it. The educational focus is on communication and checking meaning. A conversation that sounds agreeable throughout may be less revealing than a short exchange in which the learner successfully identifies and resolves a specific problem.
In a local pilot, a teacher could check which pacing and response-style adjustments the available Voice experience supports before assigning an activity. Learners could then discuss which adjustment makes the task workable and which removes a challenge they want to practise. They should have a way to pause, prepare, or choose another participation format. The purpose of the proposed exercise is deliberate practice, with flexible participation and no assumption that every account provides identical controls.
Evaluation should include a change of partner and context. After assisted rehearsal, two learners could complete a related task together using new constraints. A teacher might look for whether each person asks a needed question, explains a decision, and recovers from a misunderstanding. The comparison would need careful design before it could support any claim of improvement, but even a small classroom review can show whether the intended behaviour actually occurs. Satisfaction with a voice and successful task completion should be recorded separately from an independent judgment of language performance.
The product update expands the options educators may encounter when designing oral activities. It does not supply a language curriculum, an impartial pronunciation standard, or evidence that a particular voice improves proficiency. A bounded trial can instead make learner choice and communication goals explicit, check the settings available in the local environment, and retain only the evidence needed for the teaching question. The most useful outcome would be a clearer account of what learners can communicate beyond the AI conversation and where they still want support.