Teacher, peer, or AI? Comparing effects of feedback sources in higher education
Joshua Weidlich, Flurin Gotsch, Kai Schudel, Claudia Marusic-Würscher, Jennifer Mazzarella, Hannah Bolten, Dario Bütler, Simon Luger, Bettina Wohlfender, Katharina Maag Merki
Computers and Education Open
500-word summary
Listen to the summary
Audio summary
Feedback tools often promise comments that students will find useful, fair, and easy to accept. A classroom experiment in Switzerland asks whether those reactions translate into better academic work. Its answer is qualified: learners' perceptions and the quality of their revisions did not move together. Teacher feedback supported stronger scientific argumentation than language-model feedback, even though students did not judge teacher comments more favorably.
Joshua Weidlich and colleagues studied a real undergraduate assignment at the University of Zurich involving school quality, evaluation, and organizational development. Of 138 enrolled students, 90 contributed the complete information needed for the analysis: 31 in the teacher-feedback condition, 30 in the peer condition, and 29 in the AI condition. Students were assigned within five discussion groups, and the source of the received feedback was concealed. This reduced the likelihood that a label such as “teacher” or “AI” alone explained their reactions.
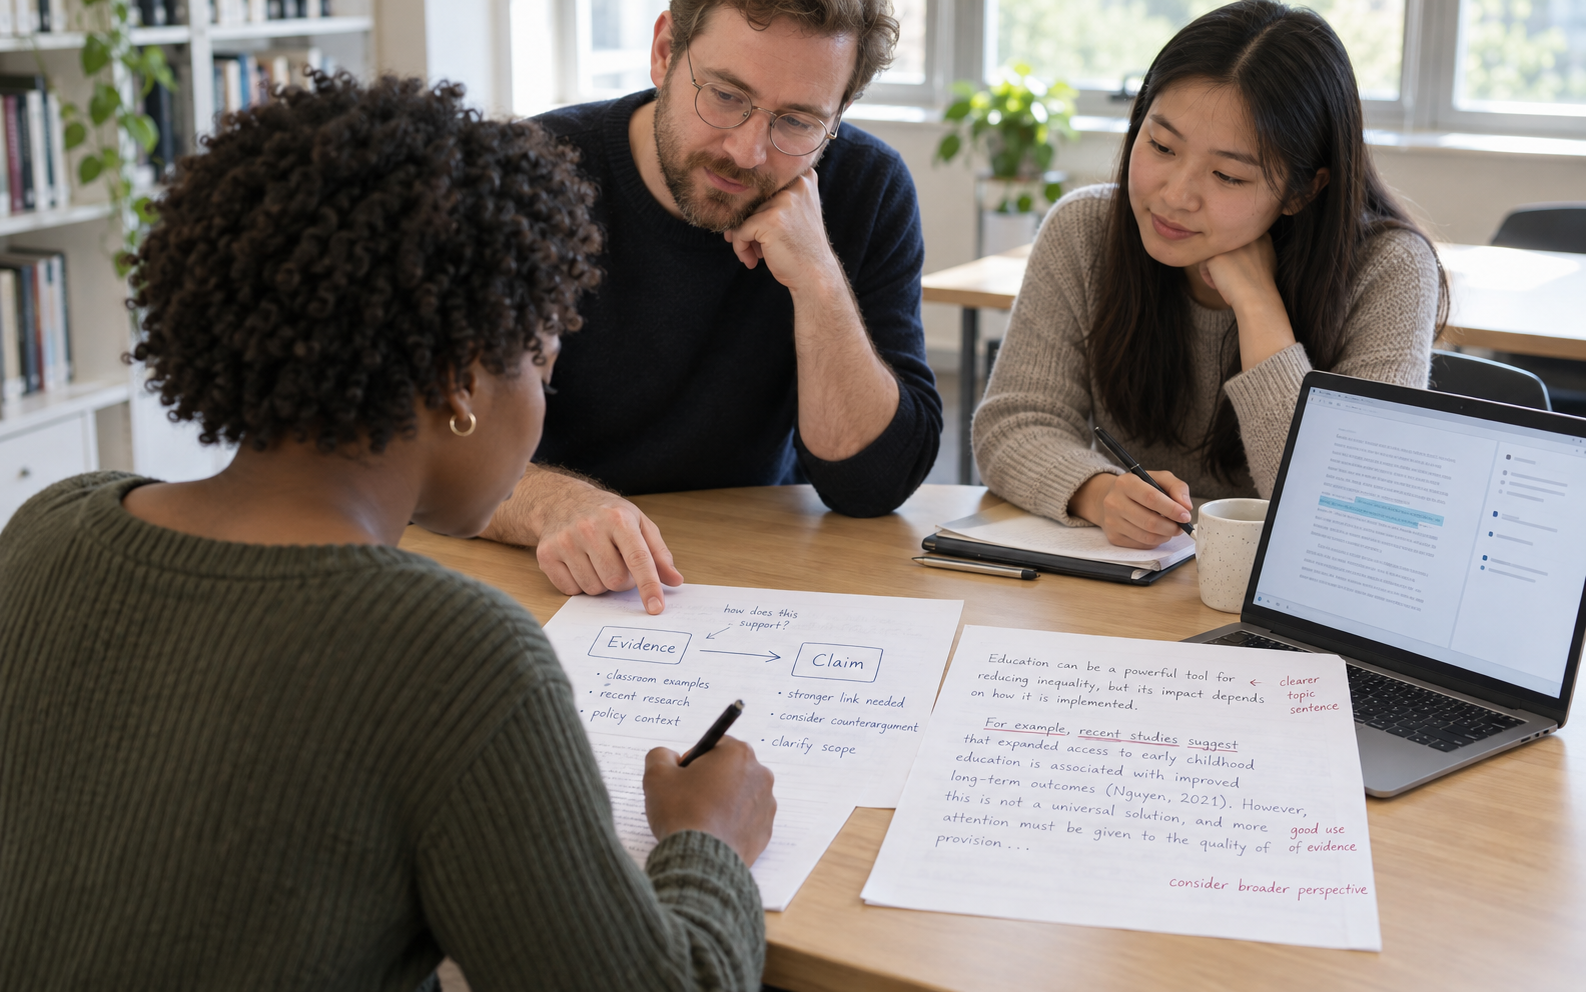
An especially useful design choice was that every student first provided peer feedback. Only the source of subsequently received feedback differed. Giving comments can itself promote reflection, so holding that experience constant helped the researchers concentrate on the receiving side of the process. Students then had a week to revise their submissions. The analysis considered initial submission quality and distinguished content, scientific argumentation, and formal quality instead of compressing everything into a single satisfaction score.
The perception results favored different sources on different measures. Students did not report a significant difference in usefulness. AI and peer feedback were rated as fairer than teacher feedback; peer comments received greater acceptance than teacher comments. Students were also more willing to engage with peer feedback than with either teacher or AI feedback. These distinctions matter: the study does not show that AI won every measure of student reception.
The revision results told a different story. Content quality did not differ significantly by feedback source. For scientific argumentation, however, the adjusted mean was 3.04 following teacher feedback and 2.59 following AI feedback, with a reported standardized difference of 0.82. Teacher and peer feedback also outperformed AI feedback on formal quality. The teacher and peer conditions did not differ significantly on the reported quality comparisons. Favorable reactions to machine-generated comments therefore did not establish equivalent revision support.
For lecturers, the practical implication is to evaluate the student's next action and resulting work, alongside the feedback itself. A pilot could examine whether comments help learners strengthen a claim, connect evidence to an argument, or apply an academic convention. Student acceptance remains useful information, but it answers a different question from whether a revision improved. Peer review also deserves consideration as a structured learning activity, rather than merely a cheaper substitute for expert comments.
The evidence is bounded by one course, a particular assignment and feedback configuration, and a complete-case sample smaller than the enrolled class. It measures revision quality over a short interval, not long-term learning or independent transfer. The findings support careful allocation of feedback roles; they do not establish that every teacher response will outperform every language model, or that positive learner experiences should be disregarded.