← Zurück zu Forschungsnachrichten

#preprint

preprint

10 Beiträge

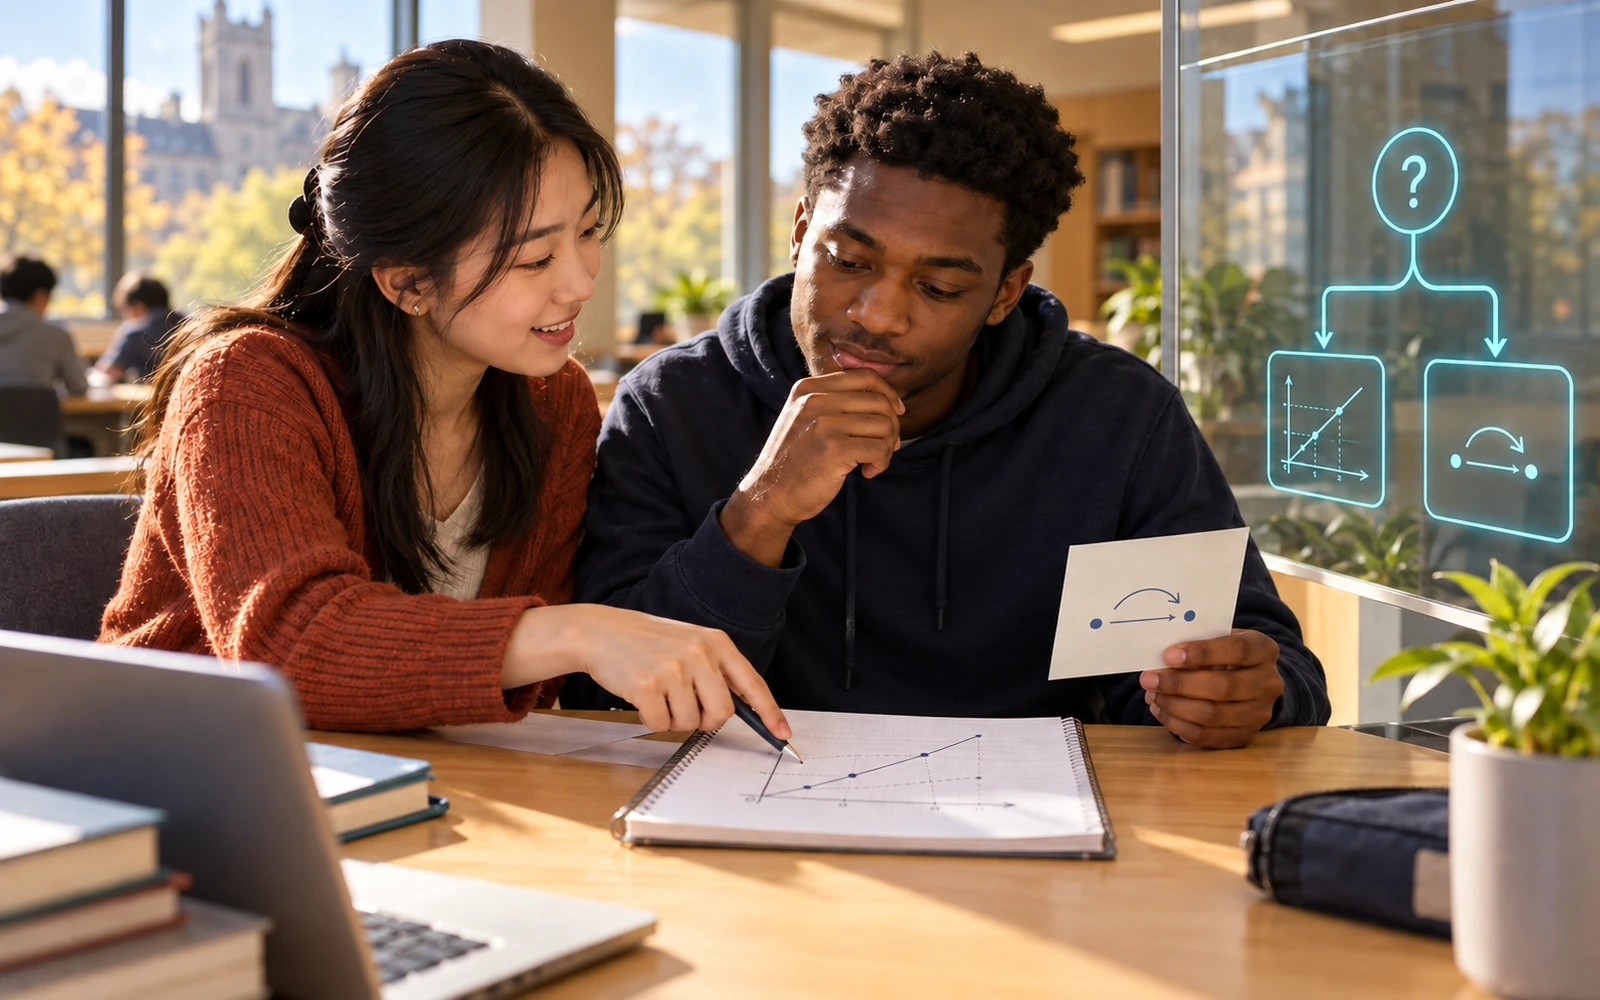
Illustrative photograph of a teacher-education group discussing a short fictional tutoring exchange, with two alternative response cards on a seminar table.
Tool / Datensatz2026
Tool / Datensatz 249

Preprint: TutorCaseBench separates recognizing a strategy from responding to a learner

Yeon Su Park, Chanyoung Park, Tae Soo Kim, Seungju Kim, Hyunwoo Kim, Daho Jung, Jinsung Yoon, Juho Kim

arXiv preprint

A benchmark builds simulated tutoring cases from qualitative education studies. Models were more successful at choosing a proposed strategy than at generating a response adapted to the particular situation.

preprintAI tutor evaluationcase-based assessment
500-Wörter-Zusammenfassung lesen →


Illustrative photograph of two educators examining a simple prediction baseline and uneven error bars on a seminar-room display.
Tool / Datensatz2026
Tool / Datensatz 245

Preprint: Tutoring logs add little to simple score predictions in one course

Zeyu Dong, Mikael Kwame Kuada, Asa Holley Buchakjian-Tweedy, Ibrahem Aljabea

arXiv preprint

A retrospective analysis compares tutoring-interaction features with constant score predictions. Small overall gains and uneven errors show why a support model needs more than a favorable average accuracy figure.

preprintlearning analyticsprediction baselines
500-Wörter-Zusammenfassung lesen →
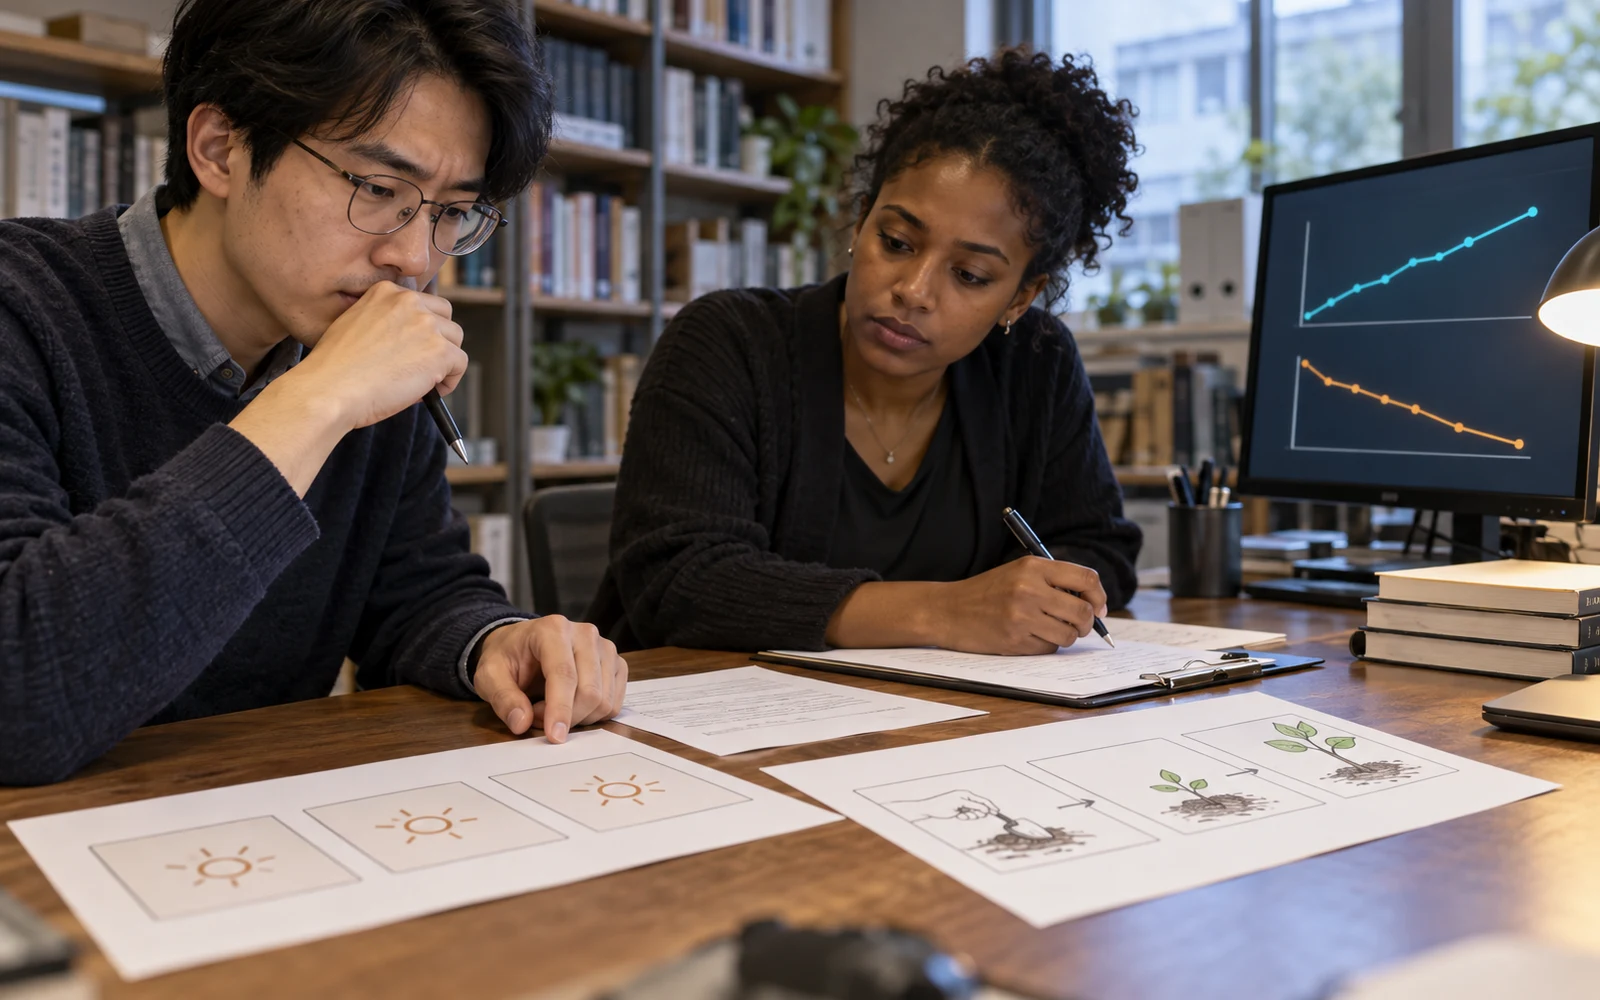
Illustrative research-review scene with two raters comparing repeated and progressive activity sequences beside a screen with one rising and one falling chart.
Tool / Datensatz2026
Tool / Datensatz 239

Preprint: Raising a tutor metric lowered human ratings in an optimization experiment

Daniel Domínguez Figaredo, Rafael Fernández De la Cruz

arXiv preprint

An optimization experiment produced higher automated scores but lower human ratings for instructional sequences. Its synthetic cases and constrained intervention make it a warning about evaluation design, not evidence of harm to actual students.

preprintAI tutoringevaluation validity
500-Wörter-Zusammenfassung lesen →
Ein schwarzer Dozent und ein südasiatischer Studierender betrachten in einem hellen Beratungsraum kommentierte Programmieraufgaben, ein Verzweigungsdiagramm sowie sich überschneidende Balken eines Bewertungsrasters.
Tool / Datensatz2026
Tool / Datensatz 228

Preprint: Detaillierte KI-Bewertungsraster unterscheiden Lernprobleme nicht unbedingt zuverlässig

Xi Zhao, Xinyue Jiao, Zhen Xu

arXiv preprint

Ein Preprint, das 3.041 Antworten aus dem Bereich Informatik untersuchte, ergab, dass die detaillierten Bewertungsdimensionen der KI stark miteinander korrelierten, während das von der KI generierte Feedback weniger Fehlvorstellungen aufdeckte als die Kommentare der Lehrenden. Die Analyse wirft eine praxisrelevante Frage auf: Kann eine Bewertung den Fehler eines Lernenden tatsächlich erklären, anstatt lediglich plausible Punktzahlen zu liefern?

PreprintAutomatisierte BewertungInformatikunterricht
500-Wörter-Zusammenfassung lesen →
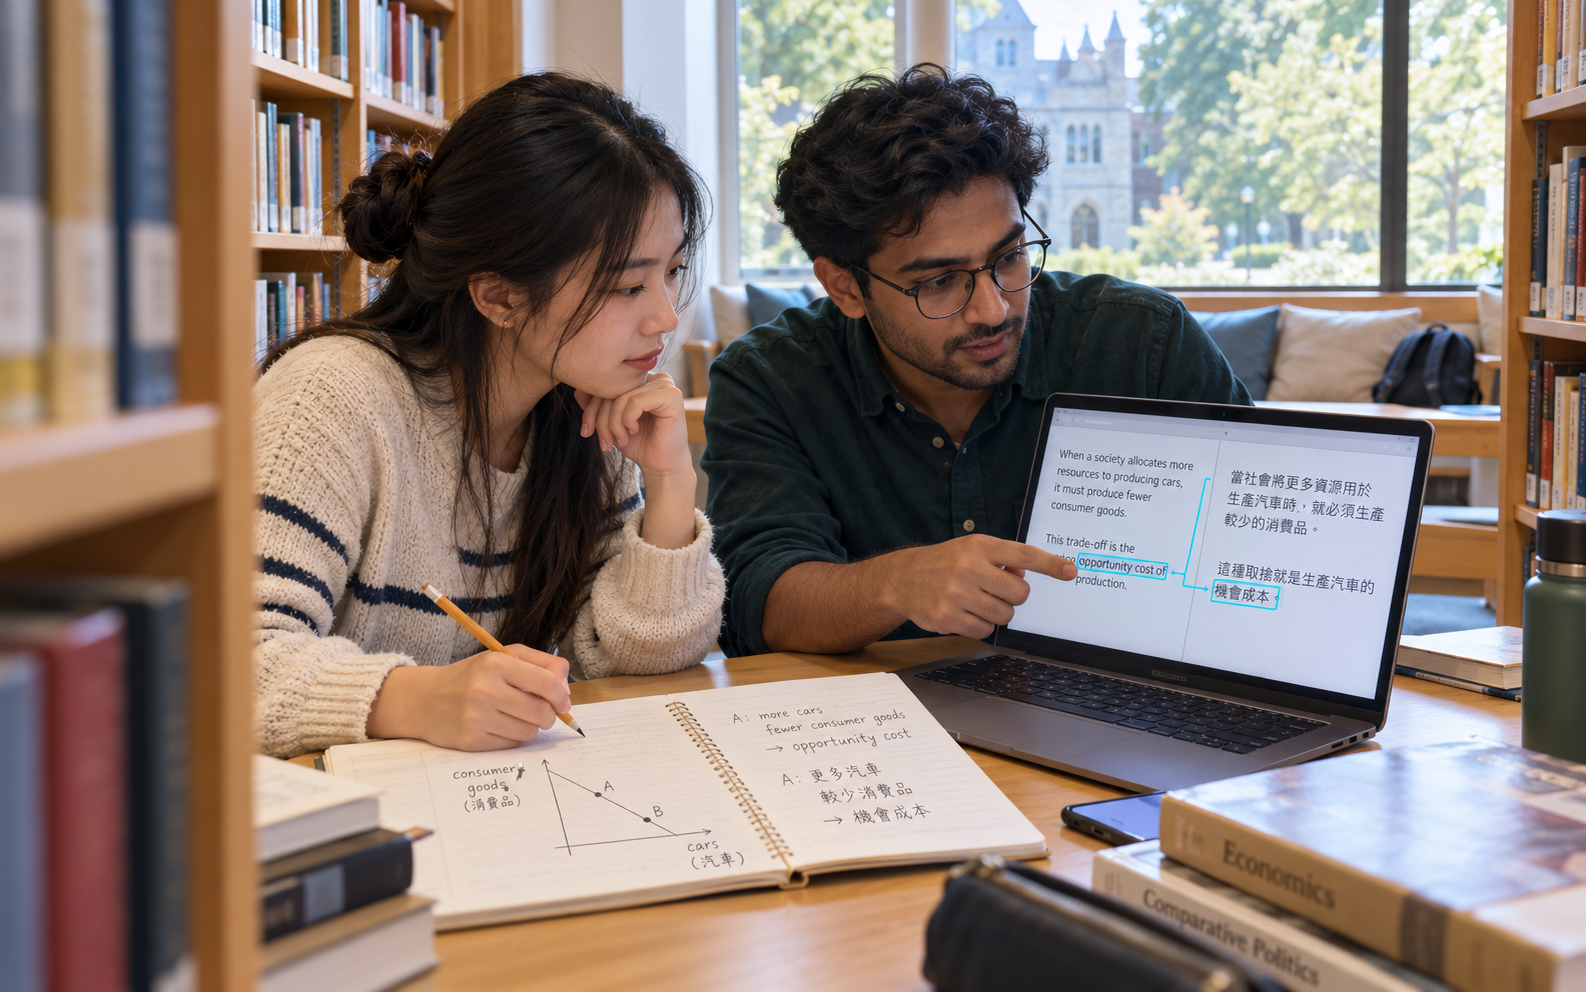
An East Asian female university student and a South Asian male language tutor compare bilingual economics notes and two AI explanations in a sunlit campus language centre
Tool / Datensatz2026
Tool / Datensatz 226

Preprint: Students’ access to generative AI did not ensure equally usable support across languages

Ming Li, Qin Xie, Ariunaa Enkhtur, Lilan Chen, Fei Cheng

arXiv preprint (work in progress)

Interviews with 42 undergraduates at universities in China, Japan, and Mongolia explored how students selected AI tools, chose interaction languages, and checked outputs. Participants described different routes from technical access to useful academic support, including switching languages when responses seemed inadequate. This work-in-progress preprint presents situated accounts rather than national comparisons or measured learning gains. It raises practical questions about evaluating an AI service in the languages students actually use.

preprintmultilingual educationAI access
500-Wörter-Zusammenfassung lesen →
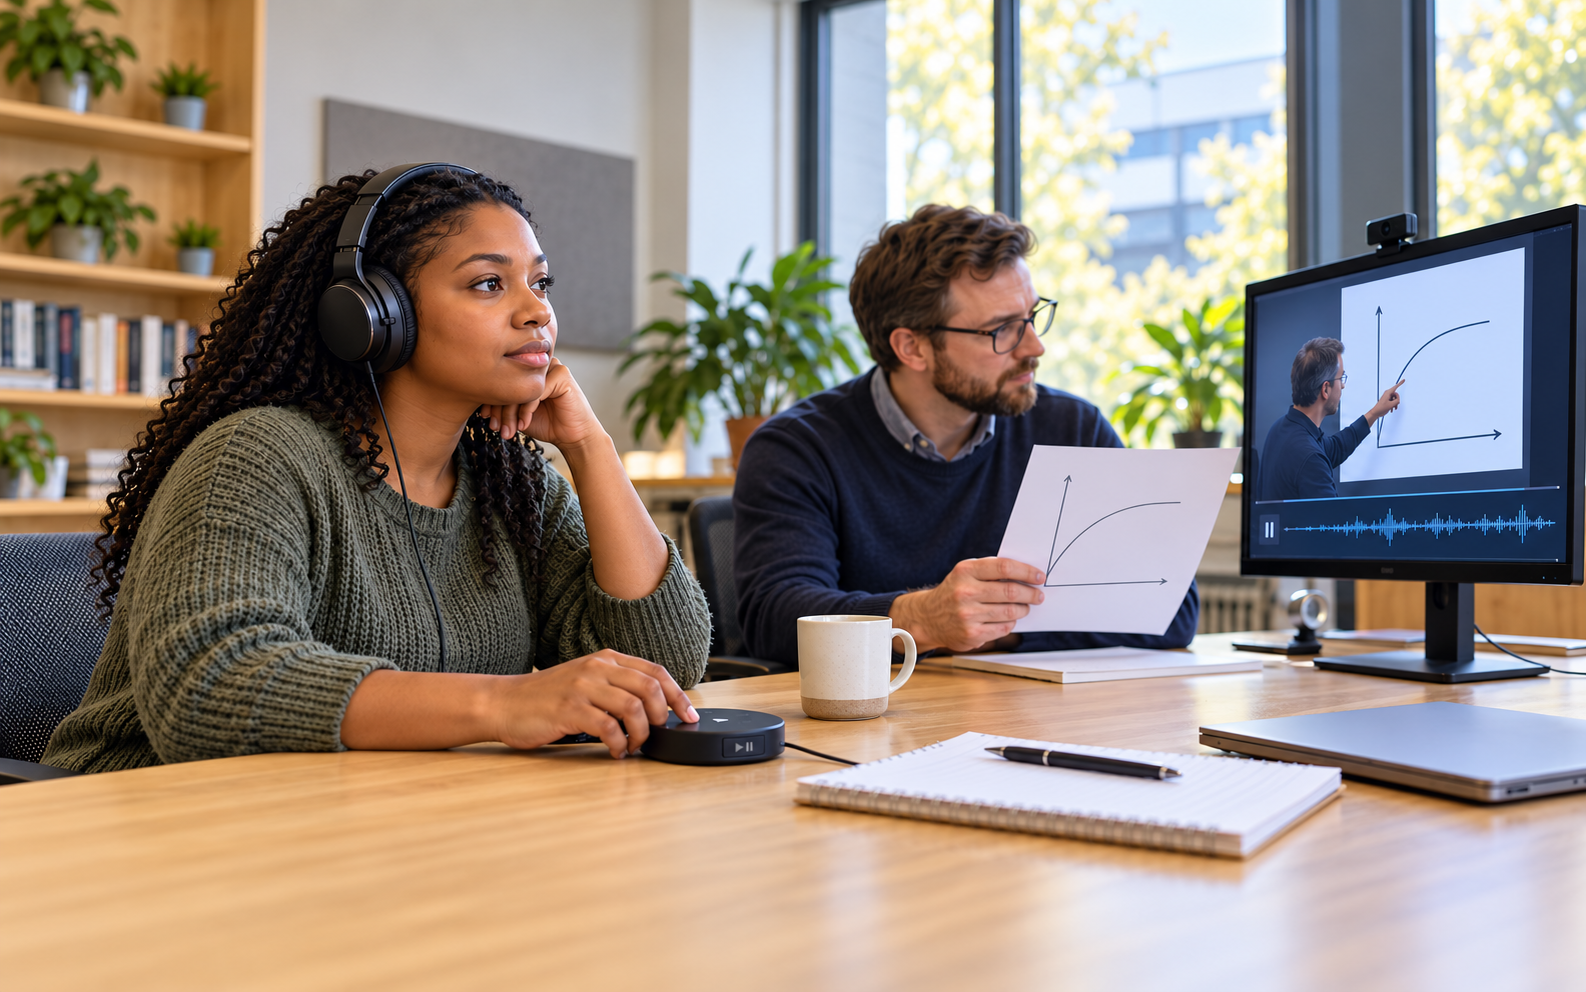
A Black female university student listens through headphones and uses a physical playback control while a White male accessibility specialist reviews a graph and lecture monitor nearby
Tool / Datensatz2026
Tool / Datensatz 224

Preprint: Lecture audio-description rules and listener preferences did not always agree

Stylianos Psychias, Yingqiang Gao

arXiv preprint

AD4Edu proposes a benchmark and evaluation framework for describing visual information in university lectures. Four blind or low-vision raters assessed 400 description pairs, revealing a gap between compliance with the researchers’ rules and individual preferences, especially about length. This preprint offers tools for studying that gap, with small-sample and playback limitations. It does not demonstrate improved course learning or certify that a lecture meets accessibility requirements.

preprintaccessibilityaudio description
500-Wörter-Zusammenfassung lesen →
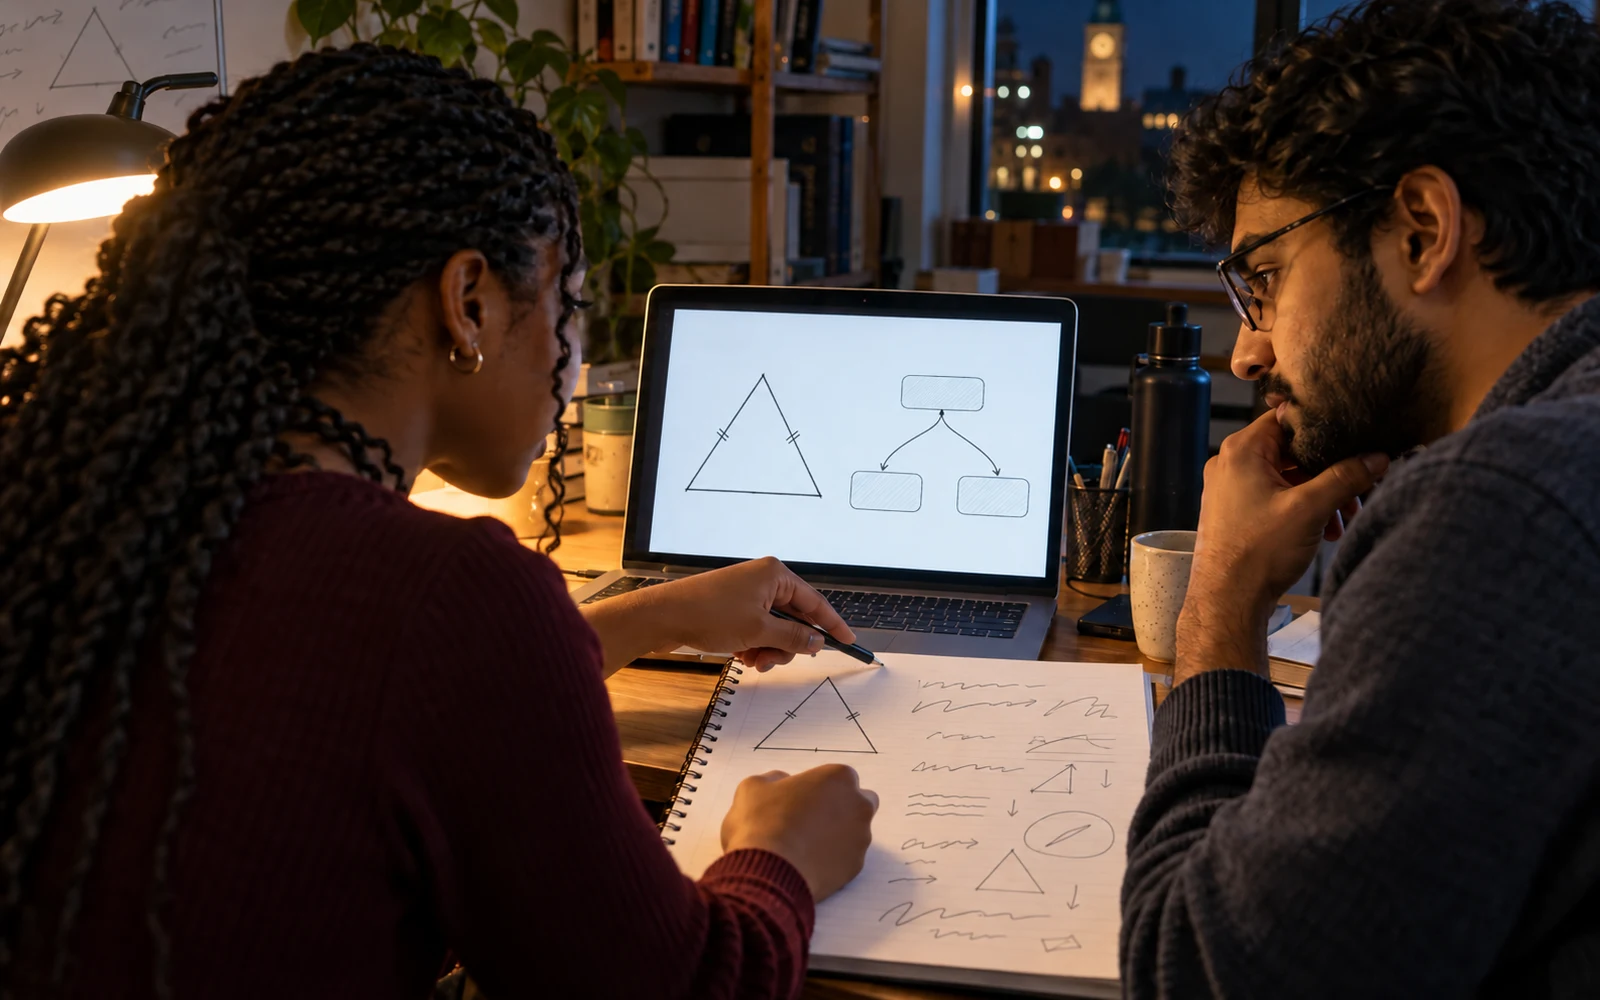
Illustrative scene of a learner and tutor comparing a handwritten triangle solution with a laptop showing a triangle and branching hint paths at an evening study desk.
Tool / Datensatz2026
Tool / Datensatz 235

Preprint: Adaptive tutor prompts changed interaction patterns without establishing better learning

Po-Chin Chang, Nicholas Hogan, Aske Plaat, Michiel T. van der Meer

arXiv preprint, version 1

A high-school tutoring preprint examines adaptive prompt selection. Its interaction results invite closer study, but limited exercise data and nonsignificant outcome comparisons leave the learning advantage unresolved.

preprintadaptive tutoringprompt selection
500-Wörter-Zusammenfassung lesen →