AI writing feedback improved revised drafts, while adding teacher feedback did not yield a clear overall advantage
Linqian Ding, Di Zou, Lucas Kohnke
Education and Information Technologies
500-Wörter-Zusammenfassung
Combining teacher expertise with AI feedback is an appealing proposition, but its benefits need to be measured carefully. Linqian Ding, Di Zou, and Lucas Kohnke compared ChatGPT feedback with a version reviewed and supplemented by an experienced human rater. Both approaches were followed by improvements in students’ revised academic writing. The important qualification is that the combined approach did not produce a statistically significant advantage in overall improvement between groups, even though some individual dimensions showed a more favorable pattern.
The participants were 77 graduate students studying English Language Education at a Hong Kong university. All were native Mandarin speakers with substantial English-learning experience. Two intact Academic English Writing classes, taught by the same instructor, were assigned to the two conditions: 30 students received ChatGPT-only feedback and 47 received combined feedback. The authors describe the study as quasi-experimental. The focal task was one literature-review assignment within a 16-week course, rather than a complete evaluation of the course’s writing development.
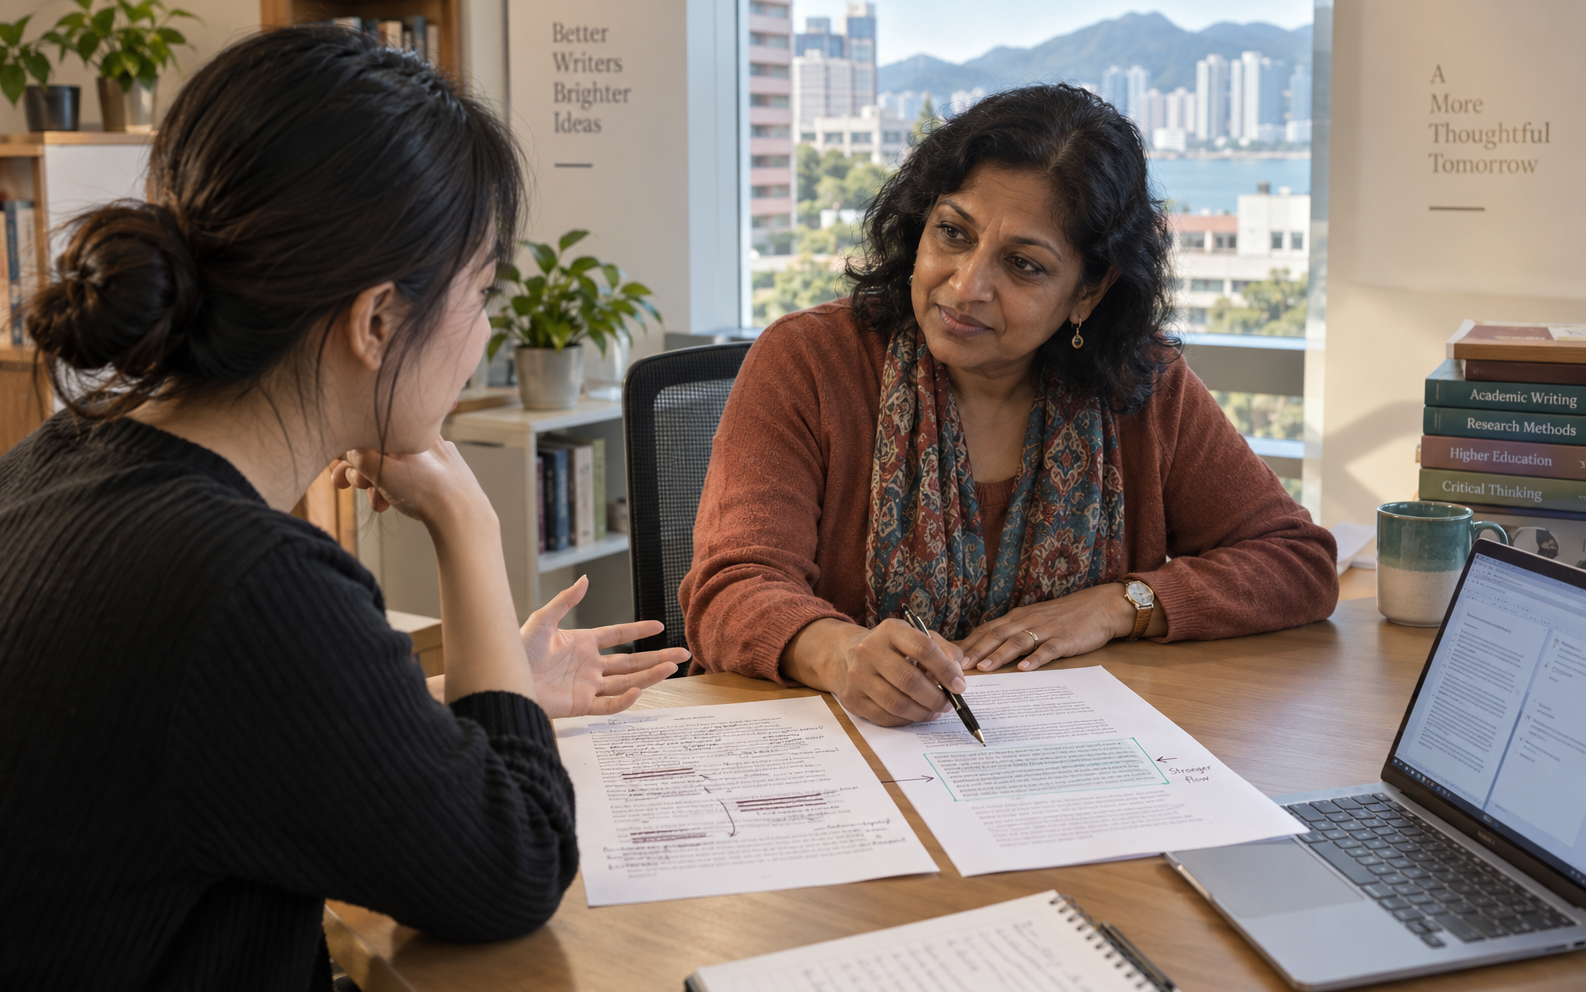
Both groups received training on obtaining and interpreting feedback, then wrote initial drafts during class. A recommended prompt asked ChatGPT for specific, actionable, encouraging comments and examples. The AI-only group revised from that feedback. For the combined group, an experienced academic-writing rater reviewed the original draft and the model’s comments, refined advice about coherence and topic relevance, and supplied tailored revision strategies. Researchers compared first and final drafts across mechanics, tone, grammar, organization, content, and APA formatting, alongside a perception questionnaire.
Within each group, overall scores improved. The AI-only group showed clearer gains on surface-related dimensions, while its content score did not significantly improve. The combined group improved across all assessed dimensions. However, those separate within-group results do not establish a between-group advantage. The direct comparison found greater grammar improvement for combined feedback, but no significant difference in overall improvement or content improvement. The organization comparison also did not reach the conventional significance threshold. Reporting the distinction prevents a stronger claim than the results support.
Students generally found the feedback understandable, yet understanding an instruction was not identical to knowing how to revise. Some described broad advice as abstract or insufficiently tied to their argument. Others questioned whether proposed wording was natural. Their comments point toward feedback literacy as part of the intervention: learners need to formulate a useful request, judge whether the response fits the task, and translate advice into a concrete change. These perceptions help explain the revision experience without independently proving learning gains.
The authors identify two major limitations. First, comparing drafts from a single assignment cannot show long-term writing development. Second, the study did not compare ChatGPT with established automated writing evaluation systems, so its distinctive advantage over those tools remains unknown. The two intact classes and the absence of a teacher-only or no-feedback condition further narrow causal interpretation. The findings therefore support a claim about assisted revision under these conditions, not a general conclusion that AI replaces writing instruction or reliably improves unaided future performance.
For AIEDHK, a useful implication is to evaluate feedback at the level of specific writing goals. A classroom pilot might inspect sentence accuracy separately from argument quality, then ask students to explain a revision and complete a later independent task. Teacher attention could focus on the reasoning that automated suggestions leave unresolved. These are proposed applications, not outcomes tested in the paper, and they preserve the distinction between a stronger submitted draft and a more capable writer.