Self-Supervised Learning
How models create training targets from the structure of existing data, and why learning from unlabelled material still depends on human choices and independent evaluation.
উৎস
সম্পূর্ণ পাঠ সারাংশ
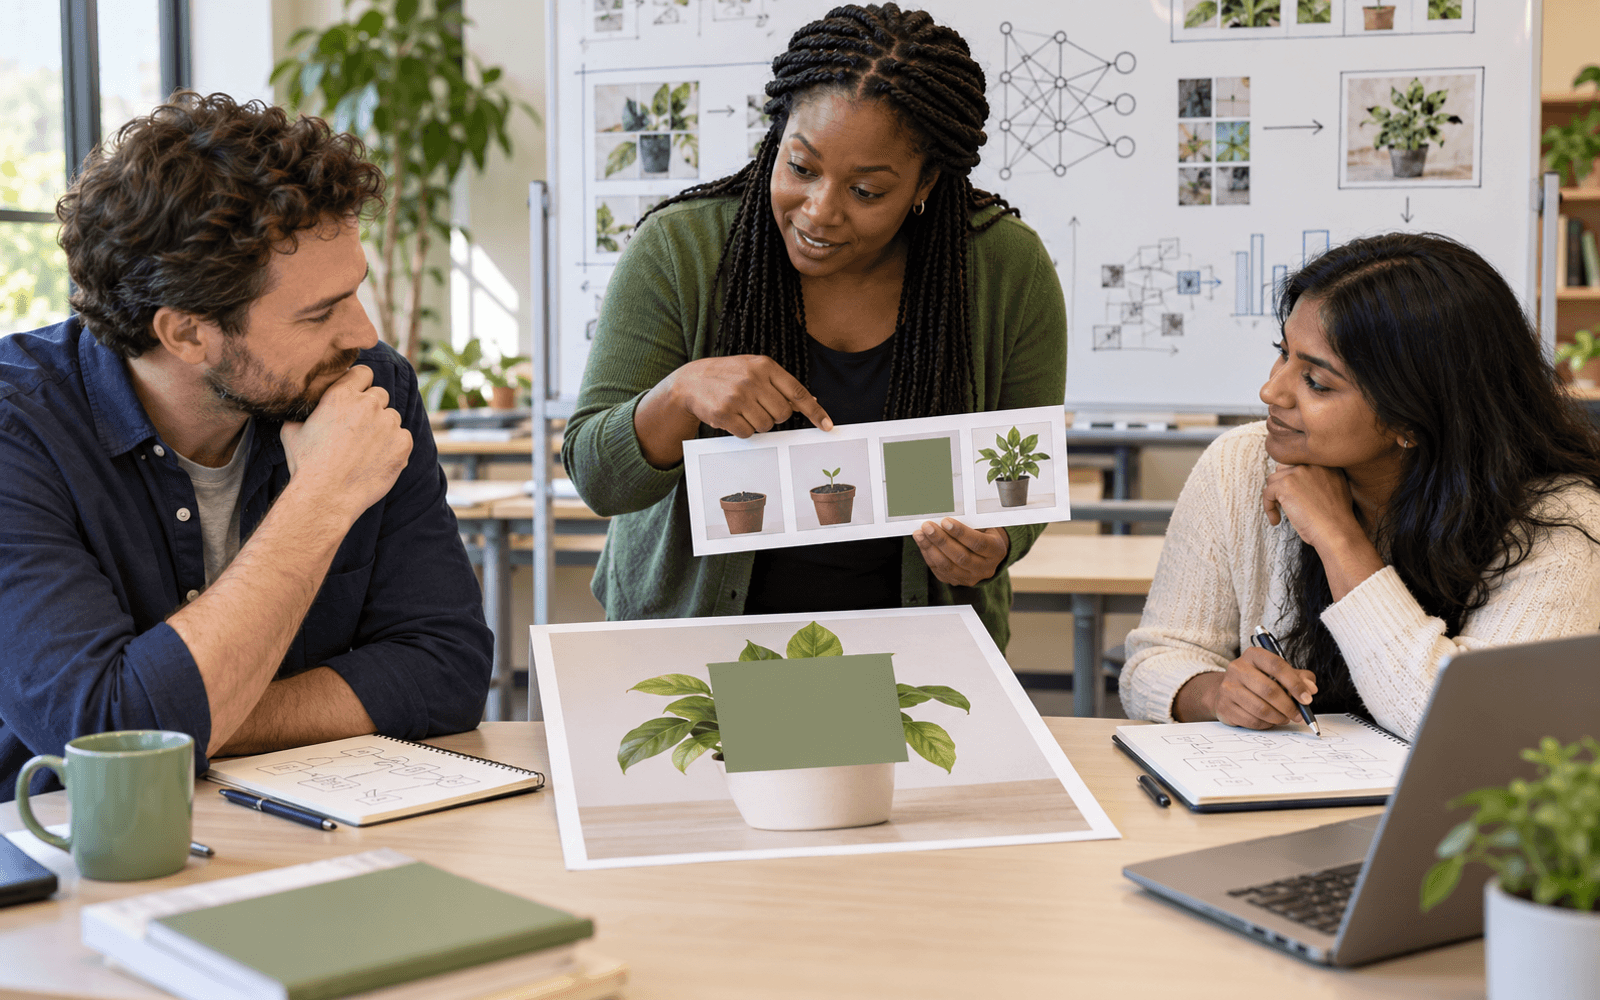
Self-supervised learning creates a training signal from the data itself rather than requiring a person to label every example for the immediate task. A system might hide part of a sentence and predict the missing text, predict a later part of a sequence, or reconstruct missing image patches. The original data supply targets against which predictions can be compared. The term does not mean that the system learns without an objective, a dataset, or human design choices.
This approach is useful because large collections often exist without labels for the eventual application. Pretraining can develop representations that are later adapted to a smaller labeled dataset or another task. BERT uses masked-language modeling as an important pretraining objective. Masked autoencoders study reconstruction of hidden image patches, while wav2vec 2.0 learns speech representations through a different self-supervised task. These examples illustrate a family of methods, not one universal training recipe.
Consider a small classroom demonstration using teacher-written science sentences. In the original sentence, "The plant absorbs water through its roots," the word water is hidden. The original text supplies a target, so a training system can compare its prediction with that word. Learners should notice a limitation: another completion may be linguistically plausible, and predicting the original word is not the same as establishing a complete scientific explanation. The objective rewards a particular relationship in the data, not all aspects of conceptual understanding.
A model trained on many such tasks may learn patterns useful for classifying or retrieving text, but usefulness must be tested. For an educational application, a team might adapt a pretrained representation to organize approved resources and compare it with a simpler baseline. The relevant evaluation should use new resources and the languages, subjects, and formats that the school actually needs. Strong pretraining results on a public benchmark do not establish that the local application improves teaching or supports learners equitably.
Unlabelled data are not automatically neutral or free to use. People created the text, recordings, and images, and choices about collection, filtering, duplication, and representation shape what the model learns. Personal information, restricted materials, and biased patterns can remain present even when no task label has been added. Self-supervision also does not eliminate the need for labeled evaluation data. Without a trustworthy way to judge the final task, it is difficult to know whether the learned representation serves its intended purpose.
Educators can make the mechanism visible by asking learners to design three hidden-information tasks and identify the target available in each. They then consider which features a model could exploit without learning the concept the teacher cares about. This encourages a precise distinction between data-derived supervision and educational understanding. Self-supervised learning can reduce dependence on manually labeled training examples for some tasks, while leaving open questions about data rights, representation quality, transfer, and the evidence needed before using the resulting system in an educational setting.