Learning from Imbalanced Data
Why high accuracy can conceal failure on uncommon cases, and how training and evaluation can respond without inventing evidence about rare learners or events.
উৎস
সম্পূর্ণ পাঠ সারাংশ
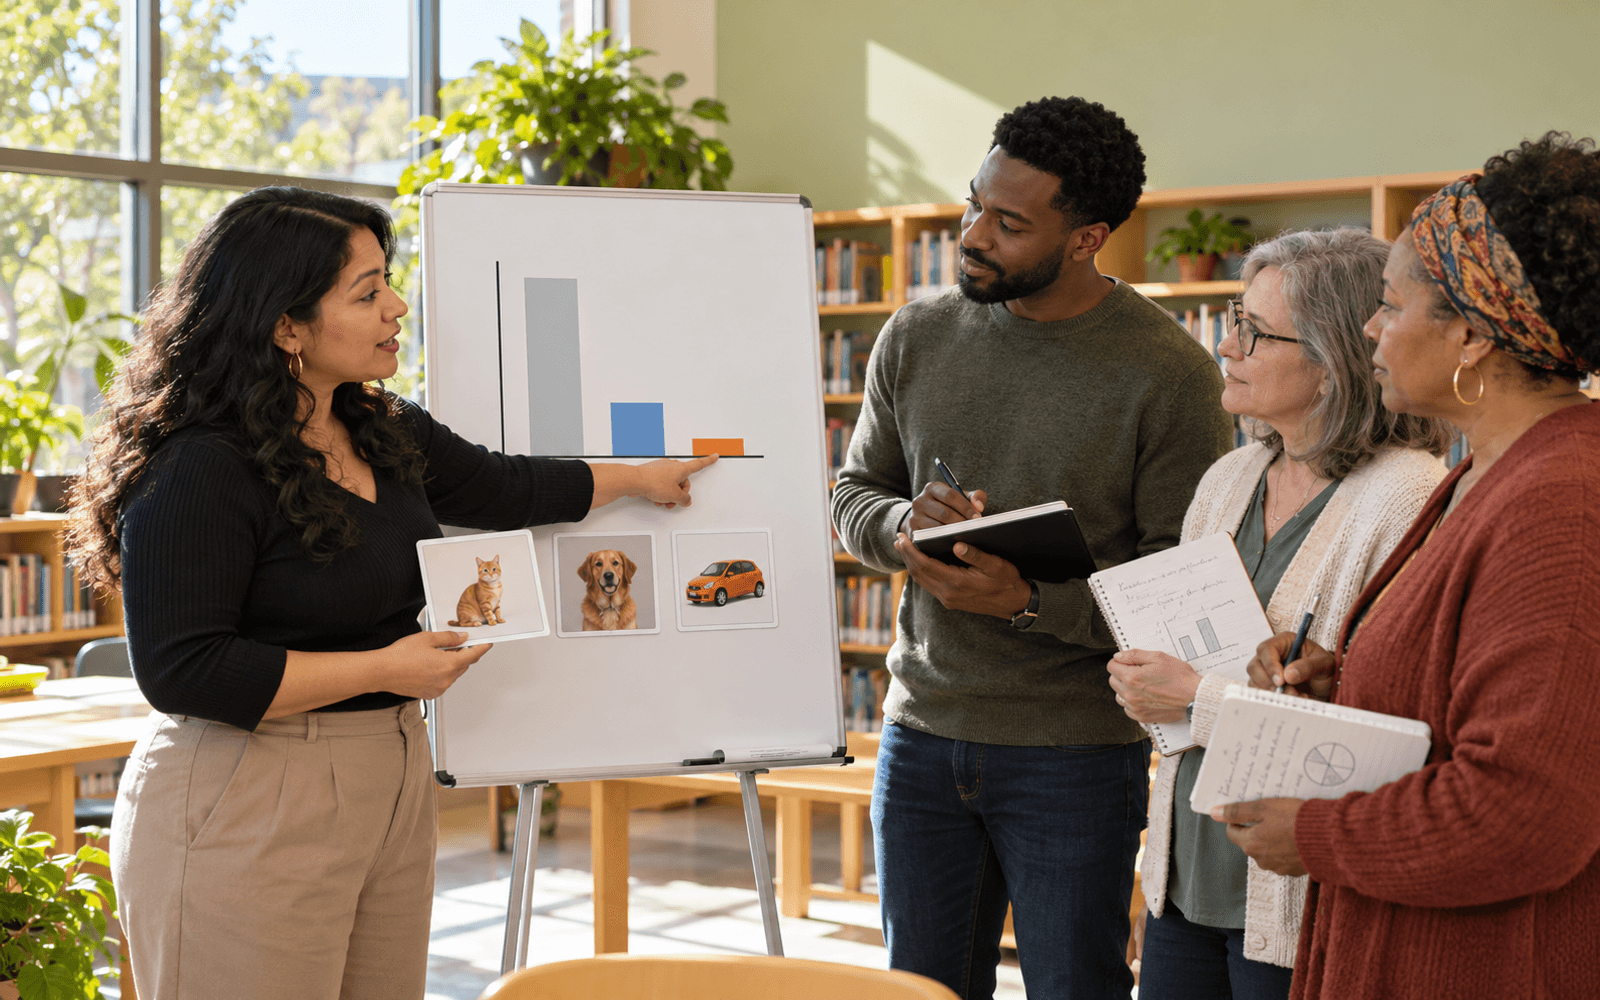
A dataset is imbalanced when some target classes contain many more examples than others. This is common in education: most resources may lack a particular feature, while only a few submissions exhibit a specific error. A model trained to minimize ordinary error can perform well on the majority while paying insufficient attention to rare cases. The importance of the minority class depends on the task, not simply on how small it is.
Suppose a resource library contains 100 items, only five of which include an interactive diagram. A classifier that labels every item "no interactive diagram" reaches 95 percent accuracy while finding none of the items the teacher wants. This illustrates why overall accuracy can be misleading. Report the class distribution, a confusion matrix, and measures such as recall for the rare class and precision among flagged items. The toy example describes class frequency, not a demographic group of learners.
Several training strategies can respond to imbalance. Class weights increase the contribution of selected errors to the training objective. Oversampling repeats or synthesizes examples from a smaller class; undersampling reduces examples from a larger class. SMOTE, introduced by Chawla and colleagues, creates synthetic feature-space examples between selected minority-class neighbors. These methods change what the algorithm sees or values during training. They do not create independent observations of the real world or guarantee better performance.
A teacher and developer evaluating the resource tagger might first collect more diverse, accurately labeled examples of interactive diagrams. They should include different subjects, visual styles, and file formats so that the model does not learn one superficial cue. If they try class weighting or resampling, they compare the result with a simple baseline using the same untouched evaluation set. A gain in rare-class recall may come with more false flags, which could be acceptable for a search aid but burdensome in another workflow.
Resampling must occur within the training data, including within each training fold during cross-validation. Doing it before the split can place duplicates or closely related synthetic examples on both sides and inflate apparent performance. Synthetic data also require a plausible feature representation. Interpolating numerical measurements can produce examples that make little sense for text, categorical variables, or tightly constrained educational records. A convenient software option is not evidence that its assumptions fit the task.
Rare classes create evaluation uncertainty as well as a training challenge. If only five positive cases appear in a test set, one error changes recall substantially. Report counts and uncertainty, inspect errors, and avoid strong conclusions about subgroups with little evidence. Class imbalance is also different from unequal representation of social groups, though the two can interact. A fair workflow examines both. The practical aim is not to force every dataset into equal class sizes, but to make important uncommon cases visible while preserving realistic evaluation and an honest account of what the available data can establish.