Caption Alignment and Timing
Why correct words are only part of caption quality: educators also need meaningful cue boundaries, readable pacing, speaker information, and synchronization with visual teaching actions.
উৎস
সম্পূর্ণ পাঠ সারাংশ
Caption alignment and timing connect written language to the moment it is spoken. A transcript records content; captions divide that content into timed segments that appear while a video plays. Good captions also identify relevant speakers and meaningful sounds. Accurate words displayed several seconds late can still make an explanation difficult to follow, especially when a teacher points to a changing diagram or demonstrates a procedure.
An automatic pipeline may first recognize speech and then estimate timestamps. Forced alignment takes an existing transcript and tries to locate its words in the audio. Voice activity detection identifies likely stretches of speech, helping separate utterances from silence. These are different tasks: alignment cannot reliably repair a wrong transcript, and detecting a voice does not establish what was said. Research systems such as WhisperX combine recognition, voice activity detection, and alignment to improve temporal precision.
The final caption file usually groups words into cues with start and end times. Cue boundaries should follow meaningful phrases where possible, giving readers time to understand a unit without covering important visual information. Word-level timestamps can help an editor create cues, but a stream of rapidly changing individual words is not automatically accessible. Reading speed, line breaks, punctuation, and speaker changes all affect usability alongside timing.
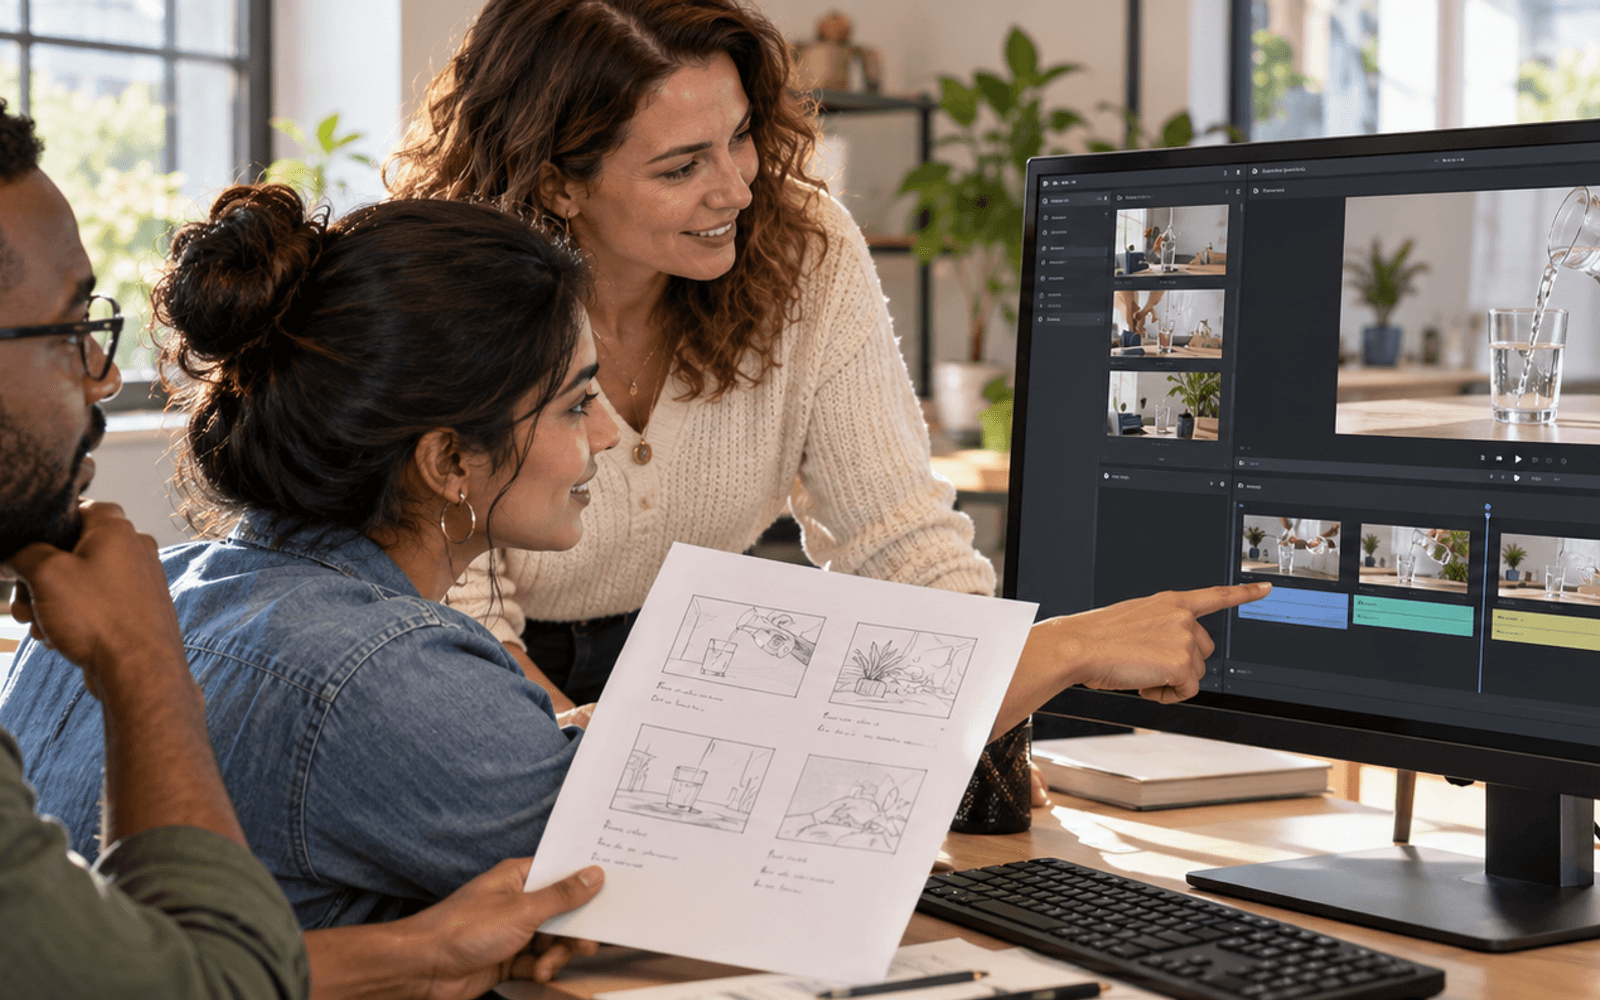
Consider a chemistry demonstration in which a lecturer says 'add the water after removing the container from the heat'. If captions appear too early, viewers may associate the instruction with the wrong action; if a cue breaks after 'add the water', its first fragment can temporarily suggest an unsafe sequence. An editor checks the whole sentence against the demonstration, keeps the relevant phrase together, and confirms that the caption remains visible long enough to read.
A practical classroom exercise begins with a short video containing a pause, a technical term, and a change of speaker. Learners correct the transcript before adjusting cue boundaries. They then watch with sound muted and compare the text with gestures and diagrams. Next they listen while watching the captions, checking whether each cue starts and ends near the corresponding speech. These two passes reveal different problems: missing sound information versus poor synchronization.
W3C accessibility guidance emphasizes captions for speech and relevant non-speech audio. An important alarm or audience response may need a concise description; decorative background detail need not overwhelm the lesson. Captions should avoid obscuring equations, faces used for communication, and other essential visual information. A separate transcript remains valuable for searching and reviewing, while captions serve the time-based experience. Providing one does not make the other unnecessary in every context.
Automatic timing is a starting point, particularly with overlapping speech, unfamiliar names, accents, music, or noisy rooms. Editing the video can invalidate previously accurate timestamps, so review the exported version after cuts and speed changes. Live captions require different expectations because processing creates delay and correction may occur after display. For both live and recorded teaching, the quality question is whether learners can connect the right words, speaker, sounds, and visual event without avoidable effort.


